


QA Wolf’s AI agent maps and tests your app’s most complex user flows. It turns your prompts into real Playwright and Appium code that runs 12x faster and more reliably than other computer-use agents.
What sets our AI apart:
Maps 200+ test cases in minutes instead of weeks of manual planning.
Executes tests 12x faster than computer-use agents.
Runs entire suites 100% parallel with consistent results.
Produces open-source tests your team owns, with zero vendor lock-in.
This week’s system design refresher:
RAGs vs Agents
Build with Claude Code: New Cohort Launch
Forward Proxy, Reverse Proxy, and API Gateway Explained
How does a request actually travel through Claude Code?
How does Claude Code keep long sessions from running out of context?
Ask an LLM about your company's data and it will guess. The two patterns that fix this are RAG and agents, and they solve different problems.
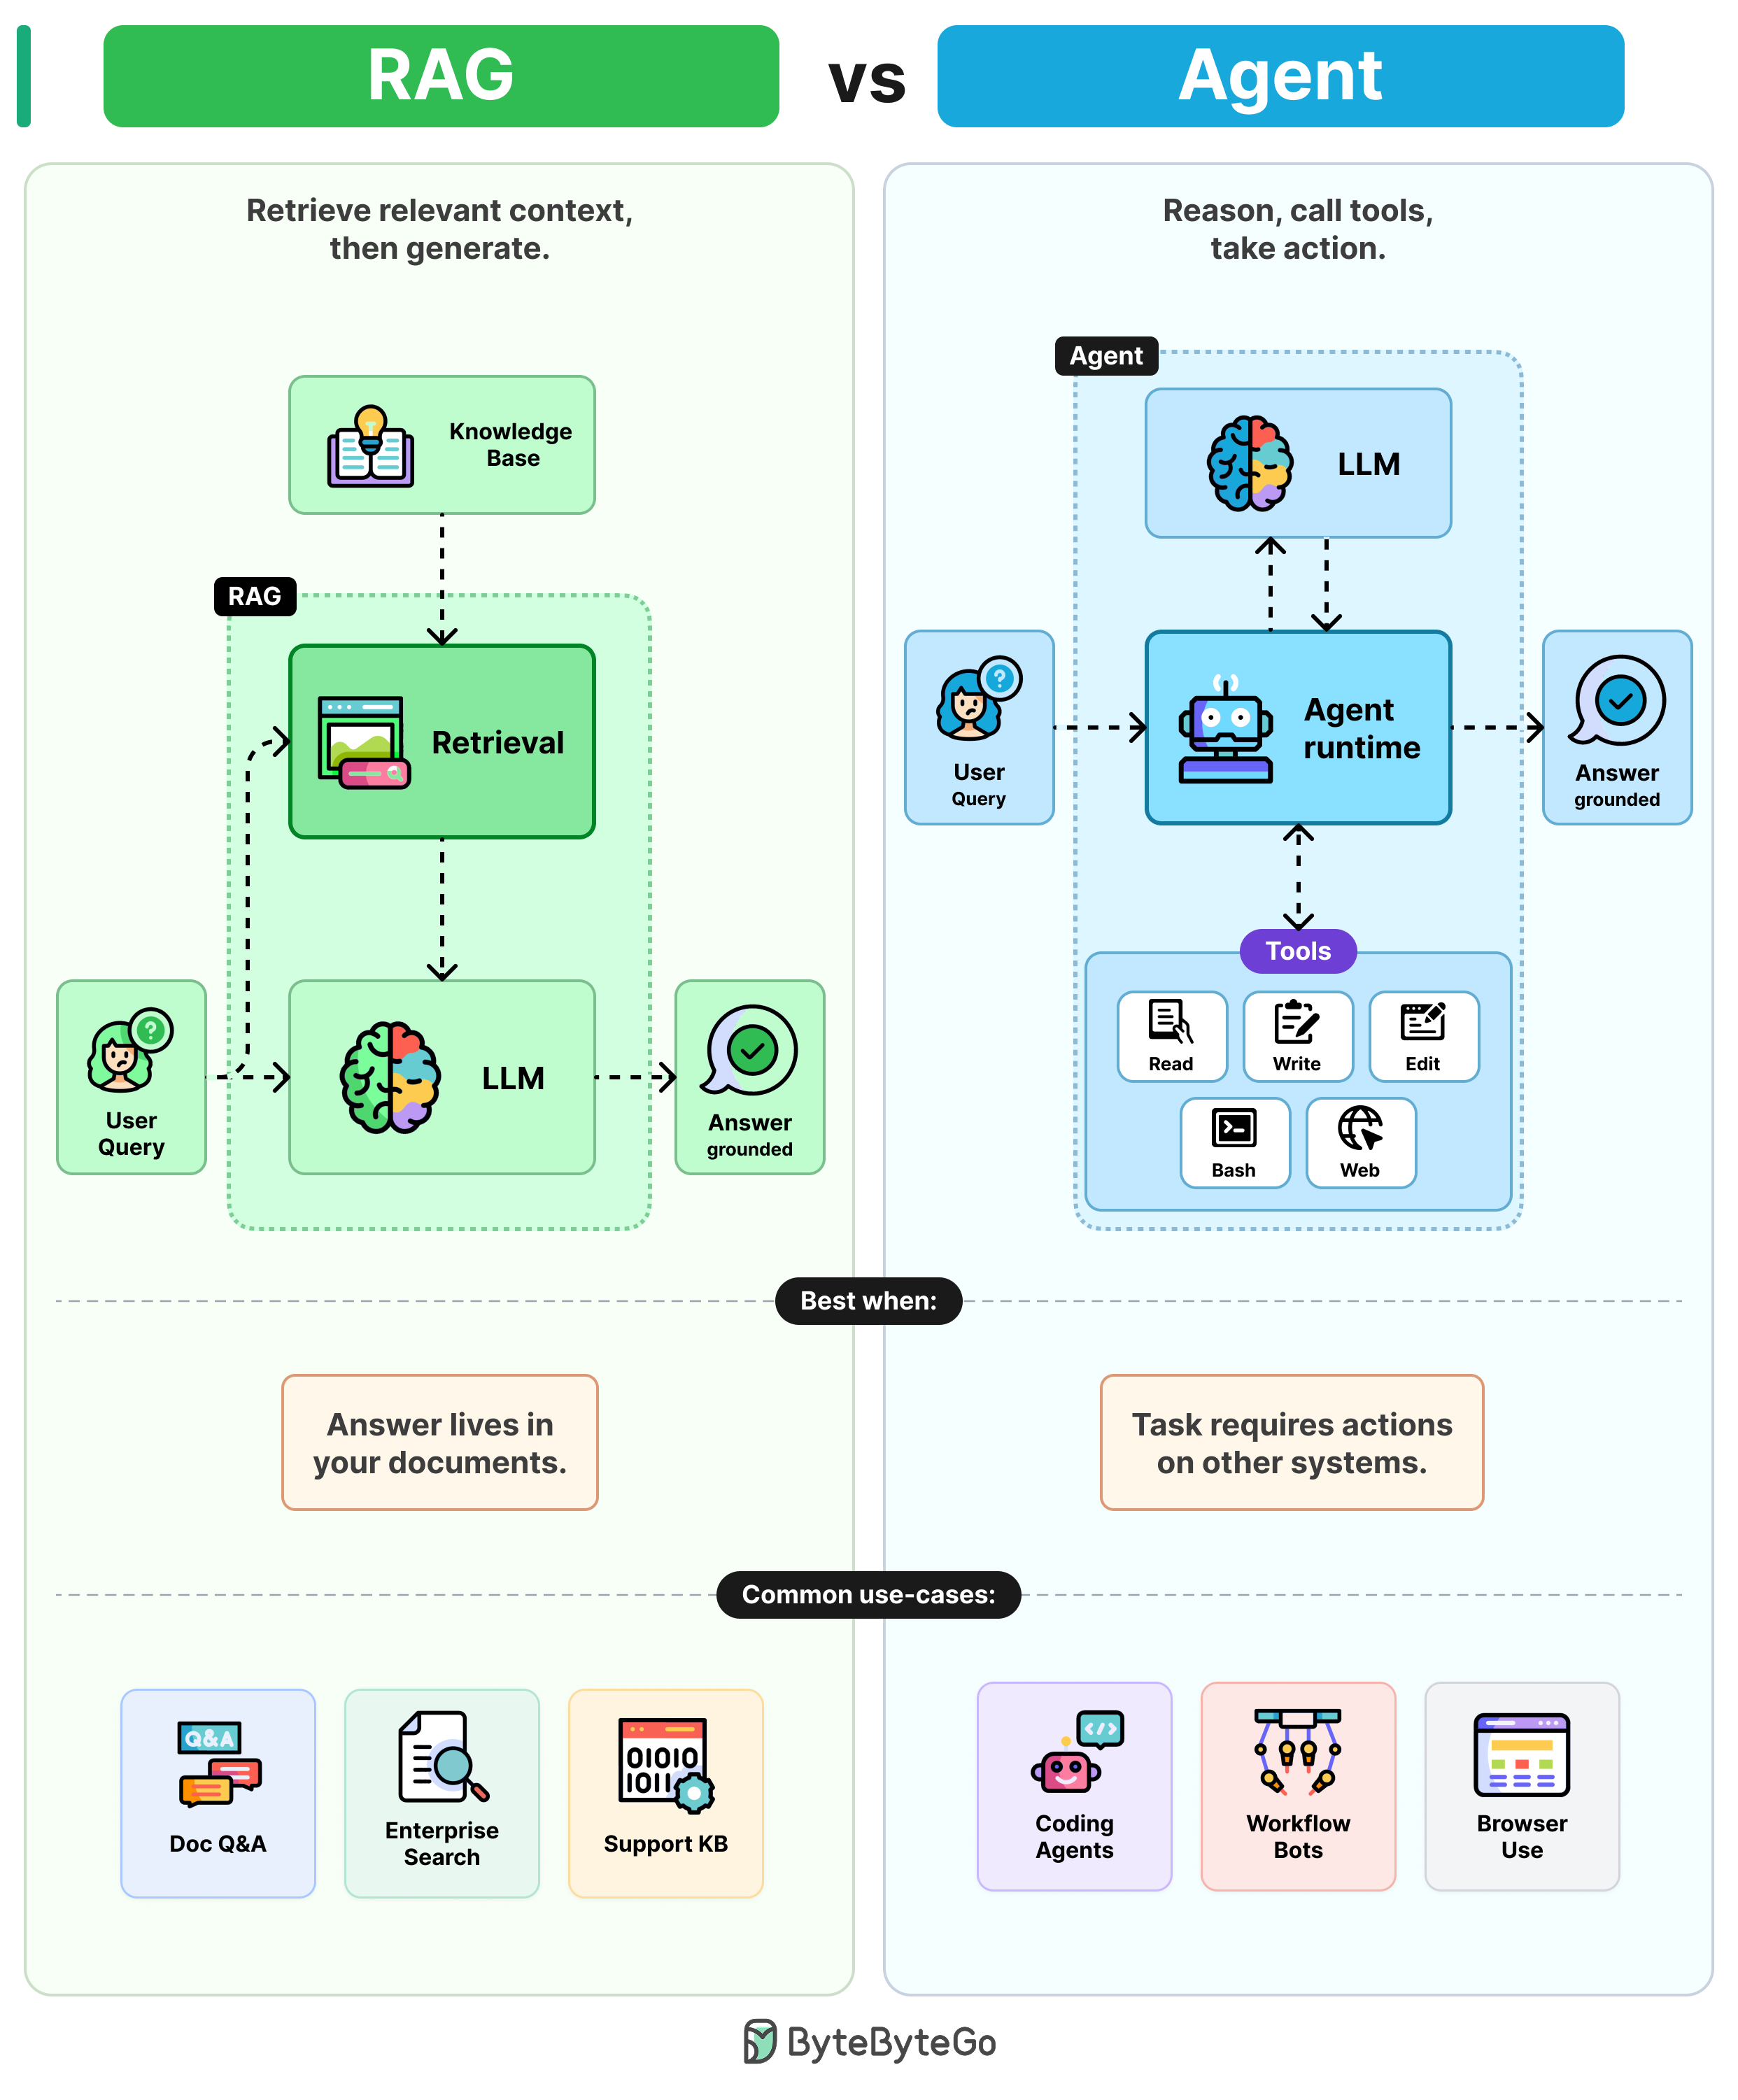
RAGs: RAGs combine LLMs with retrieval to ground answers in 4 steps.
Step 1: The user query is embedded and sent to a retrieval step.
Step 2: Retrieval pulls the most relevant chunks from a knowledge base (PDFs, wikis, etc.)
Step 3: Those chunks are pasted into the prompt as context.
Step 4: The LLM writes the answer, grounded in the retrieved text.
One retrieval. One generation. Cheap, predictable, and easy to debug.
Agents: Agents wrap LLMs in a reasoning loop with tools to take action.
Step 1: The user query goes into the agent runtime. A reasoning loop wrapped around an LLM.
Step 2: The LLM reads the goal and picks a tool (Read, Write, Edit, Bash, etc.)
Step 3: The runtime executes the tool and feeds the result back to the LLM.
Step 4: The LLM reasons again, picks the next tool, and loops until the task is done.
More flexible. More tokens. Harder to debug because errors drift across steps.
The rule of thumb: Use RAG when the answer lives in your documents. Use an agent when the answer requires action on other systems.
Over to you: When do you prefer RAG over agent?
We’re launching a new 2 day intensive, cohort based course called Build with Claude Code, taught by John Kim, who has trained hundreds of engineers at Meta to use Claude Code in real production workflows.
The course starts soon on May 28.

A few things you’ll learn:
The agentic loop, context engineering, and memory layers that make Claude Code useful for real projects
How to build with Claude Code Skills, MCPs, and hooks to give Claude the tools and feedback loops it needs to self correct
Parallel development with Git worktrees, subagents, and agent teams
A capstone project where you ship something real on your own stack
The course includes live sessions, assignments, and office hours, so there’s plenty of room to ask questions and get unstuck.
The first cohort starts in just a few days: May 28 to 29, 2026. If you want to learn everything from the fundamentals of Claude Code to advanced production workflows, including working with large codebases, this could be a great way to level up.
People mix these up all the time, since they all sit between a client and a server. The real difference is which side they represent and what problem they solve.
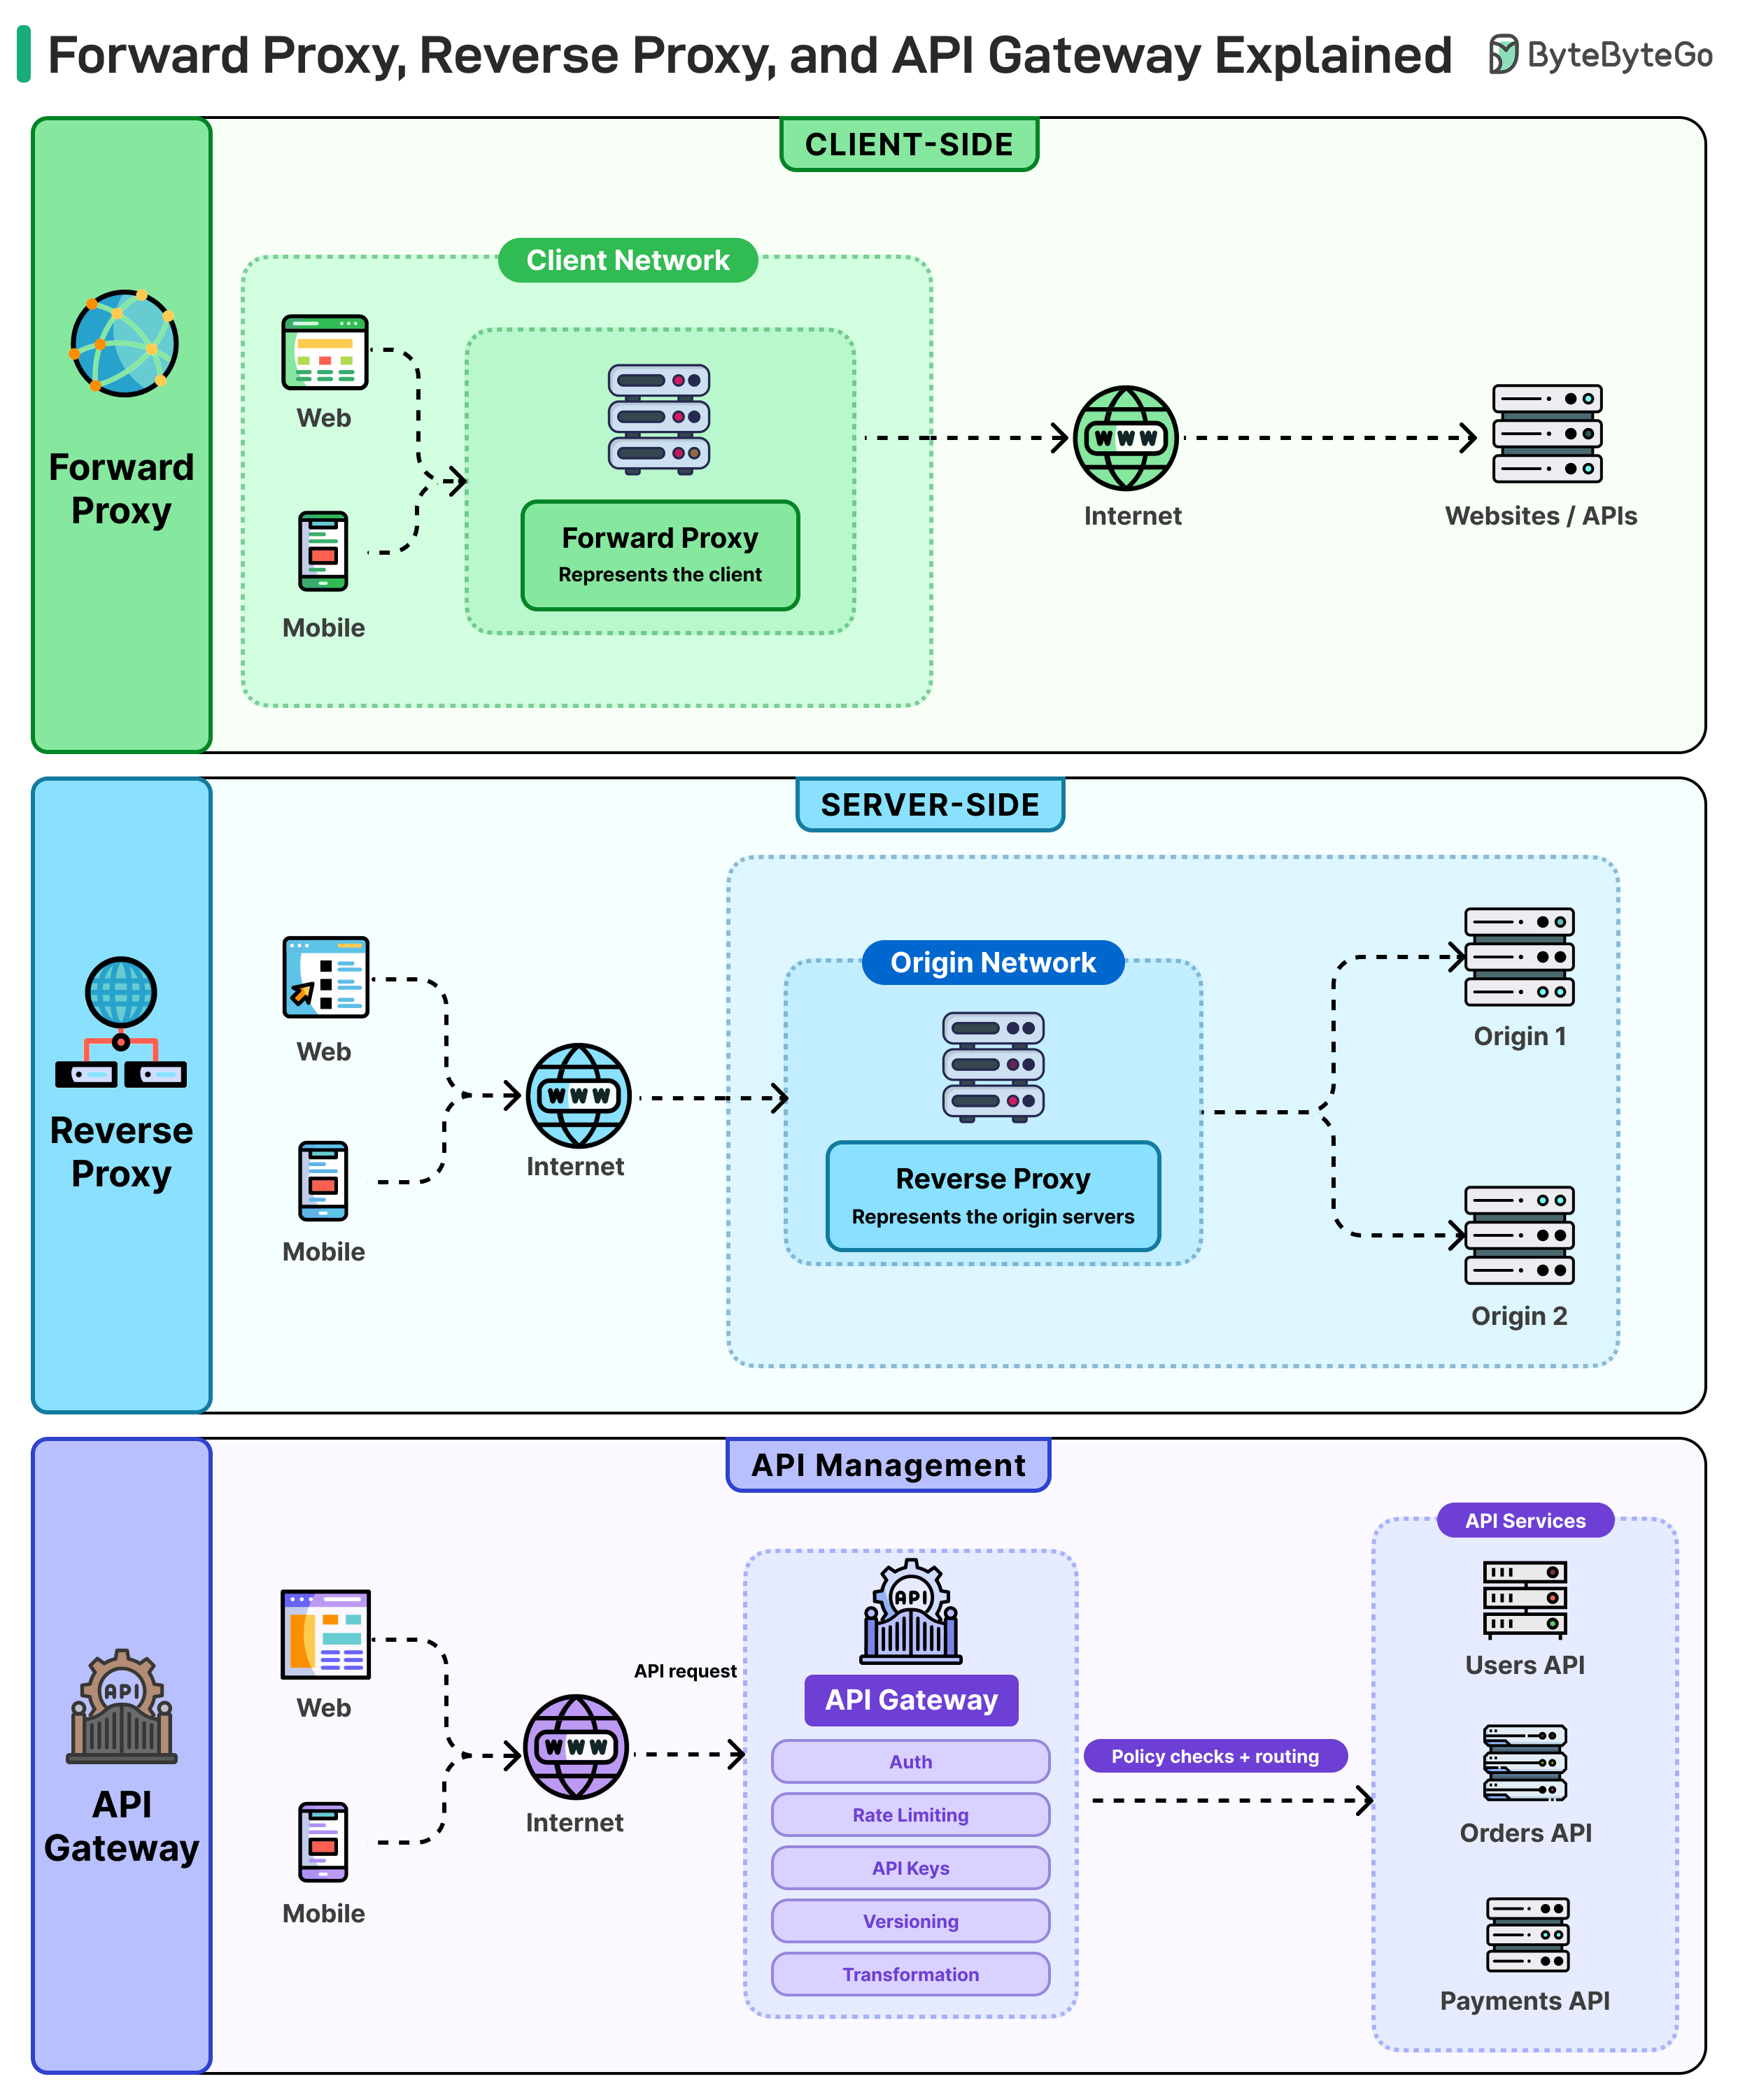
A forward proxy sits next to the client. Your laptop sends a request, the proxy forwards it out, and the destination never sees your real IP. Corporate networks use this to enforce policy, block sites, and cache traffic.
A reverse proxy sits next to the server. The client has no idea how many machines are behind it. The proxy decides who handles the request, terminates TLS, and keeps your backend off the public internet. NGINX and HAProxy are commonly used here, typically paired with a load balancer in front.
An API gateway is a reverse proxy that does more than route traffic. It also handles auth, rate limits, API keys, versioning, and request shaping. Without it, each microservice has to implement its own version of validation, throttling logic, and request logging.
A forward proxy represents the client, a reverse proxy represents the server, and an API gateway is what you add when ten services need the same authentication and rate limiting rules applied consistently.
In most real systems, all three are running at different layers. The forward proxy filters outbound traffic, the reverse proxy fronts the application servers, and the API gateway sits in front of your APIs to enforce policies before requests reach them.
Over to you: What's your proxy + gateway combo? Always interesting to see what teams pair together.
Most of us type a prompt and watch the magic happen. The diagram below shows what's really going on behind the curtain, based on the Claude Code source code.
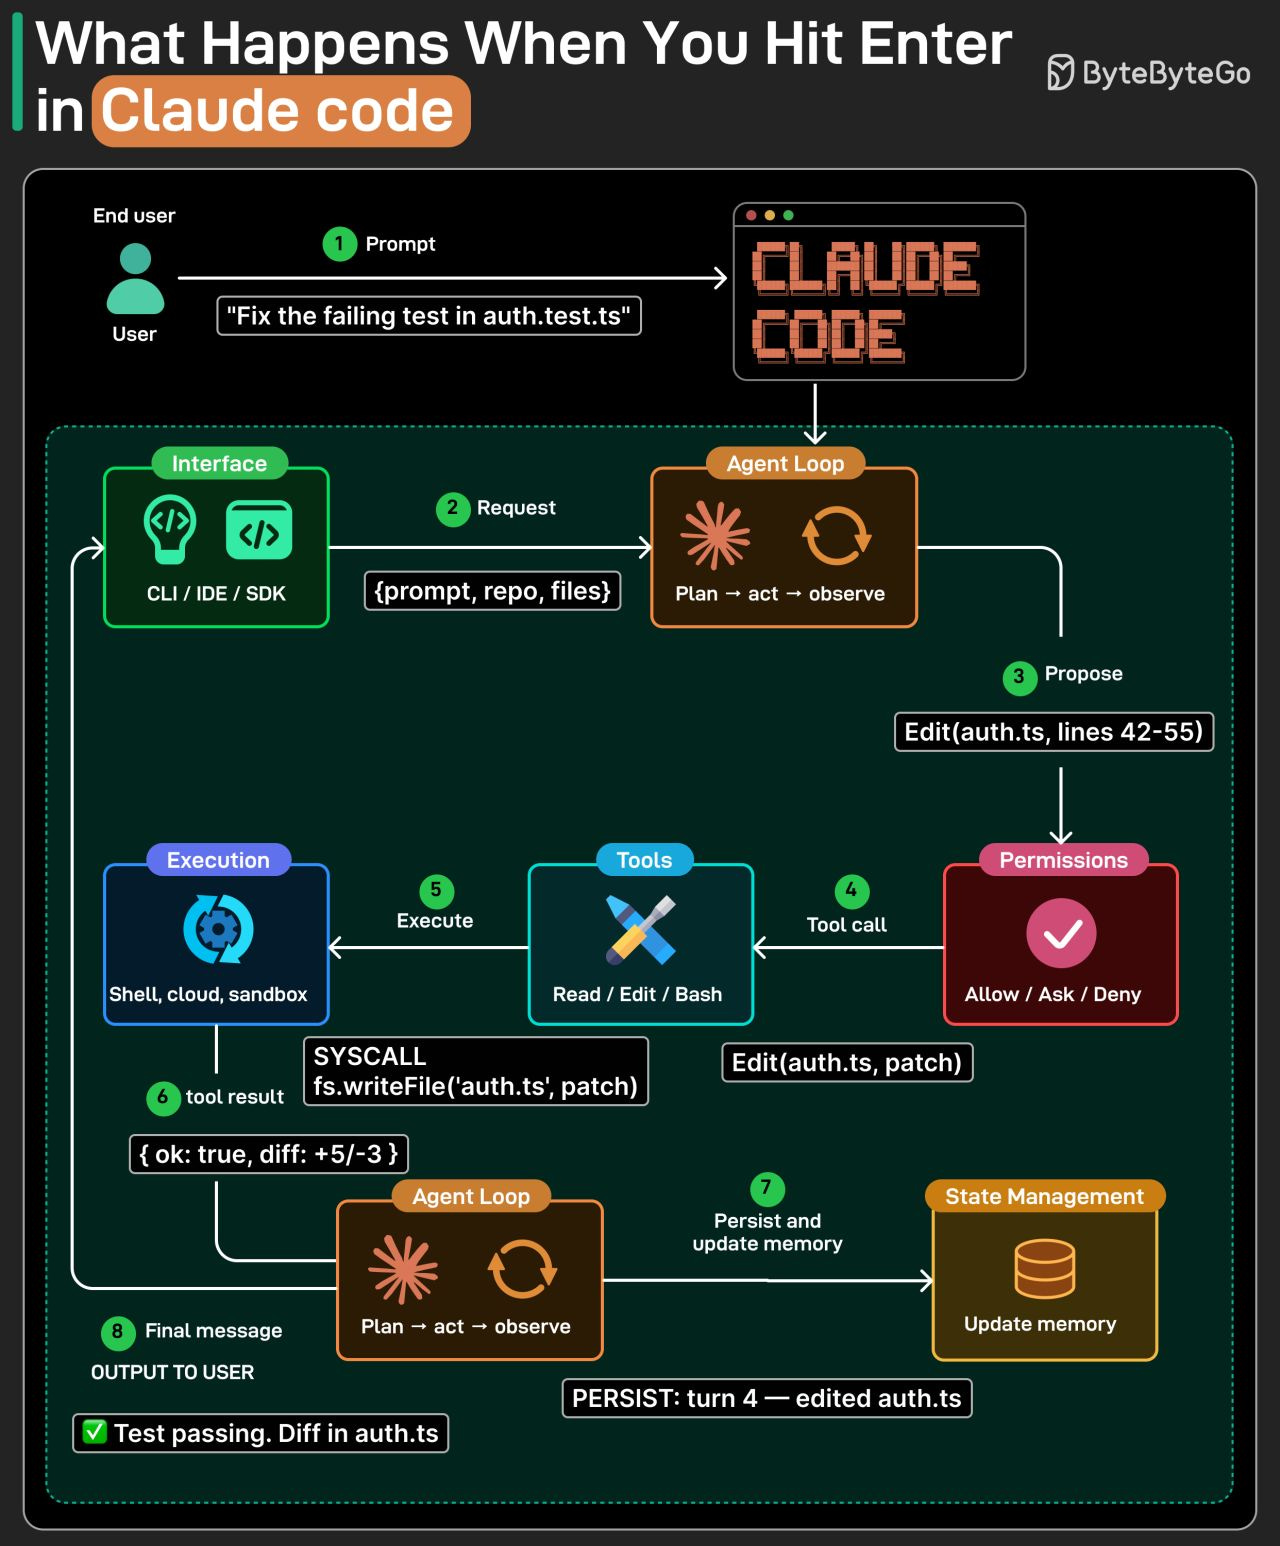
Let's trace one real request: "Fix the failing test in auth.test.ts."
Step 1: The user sends a prompt to Claude Code through their interface.
Step 2: The interface (CLI, IDE, or SDK) wraps the prompt with repo and file context and hands it to the agent loop as a request.
Step 3: The agent loop plans the next move and proposes an action: Edit(auth.ts, lines 42–58).
Step 4: The permission system checks the proposed action against the rules.
Step 5: The approved action becomes a tool call: Edit(auth.ts, patch), dispatched to the matching tool.
Step 6: The tool runs in the execution environment (shell, cloud, or sandbox) as a real syscall.
Step 7: The execution returns a tool result back to the agent loop.
Step 8: The agent persists the turn to state and streams the final message to the user.
The whole system is just this loop, repeated until the model stops asking for tools.
Over to you: which step in this loop do you think is the hardest one to get right when building your own coding agent?
It uses 5 strategies, run in sequence before every model call. Each one only runs if the previous doesn’t free enough room.
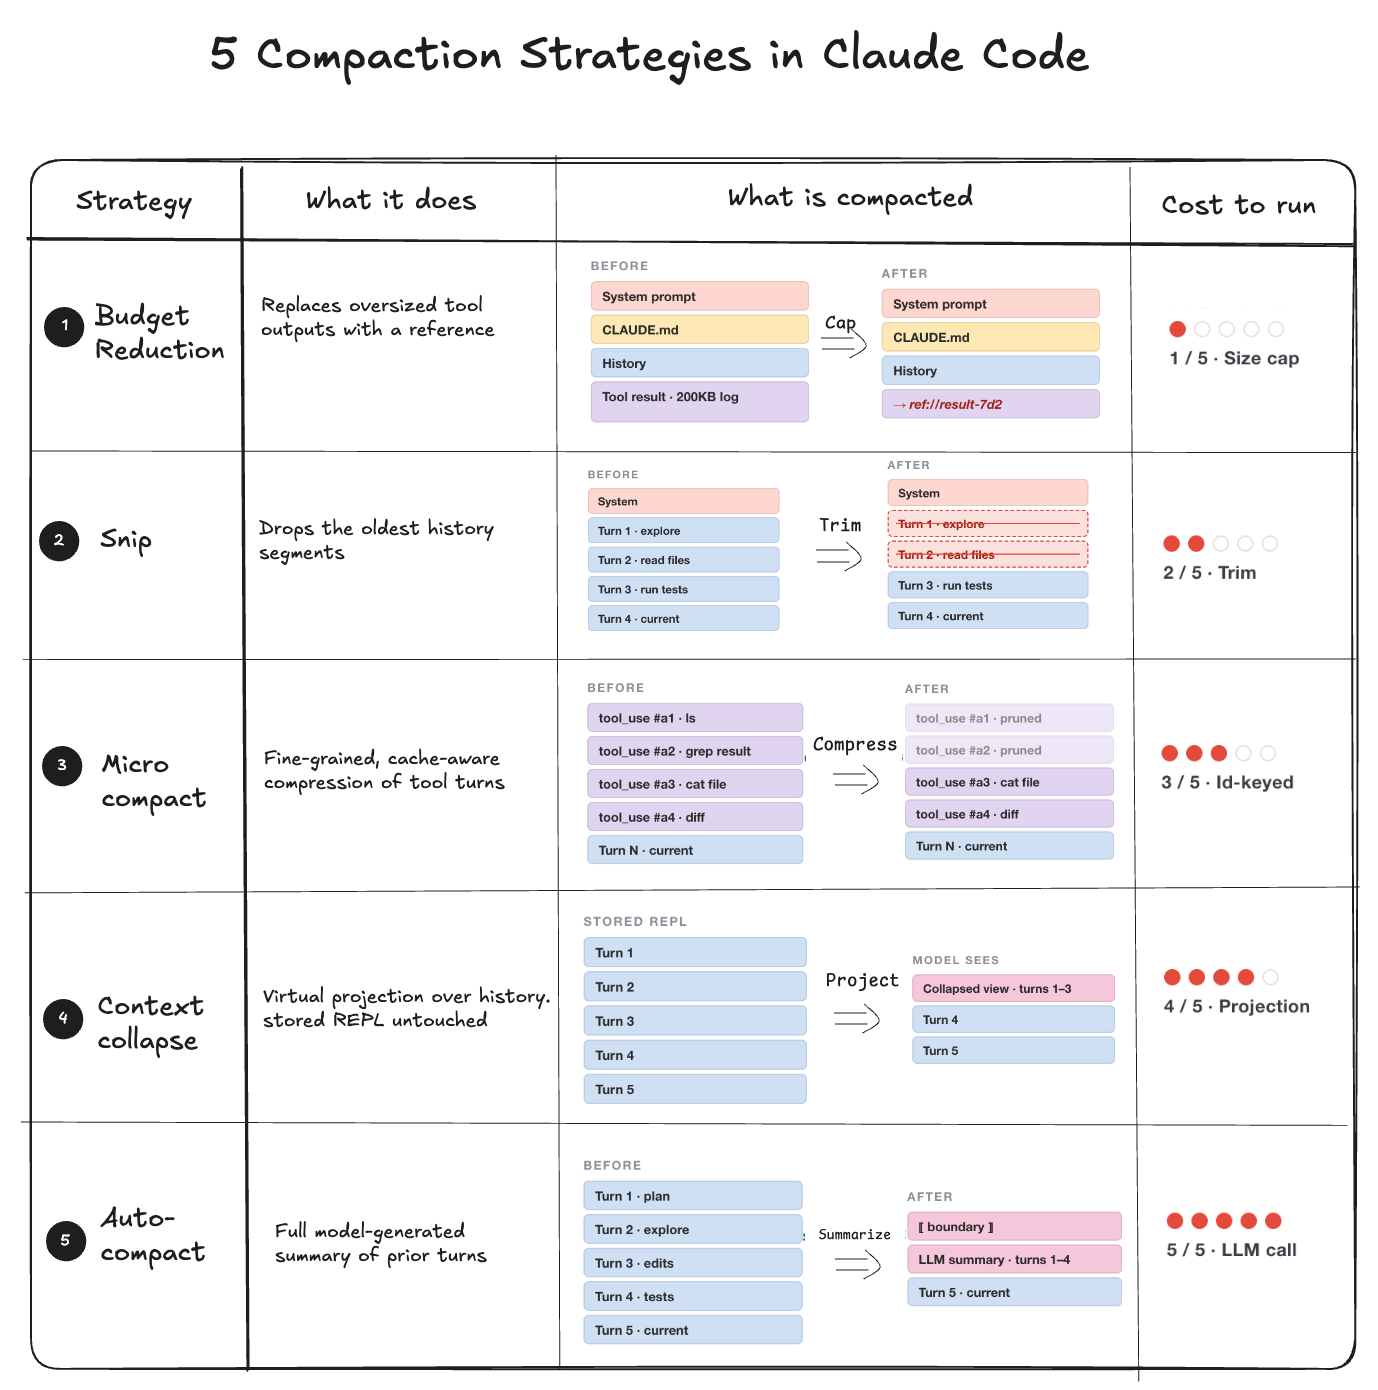
Budget Reduction: caps individual tool results. Oversized outputs are swapped for a content reference.
Snip: trims the oldest history segments and emits a boundary marker.
Microcompact: prunes tool turns by tool_use_id so the prompt cache stays warm.
Context Collapse: a read-time projection over the full history.
Auto-compact: the last resort. It calls the model to produce a full summary of prior turns.
The pattern is lazy degradation: apply the least disruptive shaper first, escalate only when cheaper layers prove insufficient.
Over to you: how often do you run out of context?