






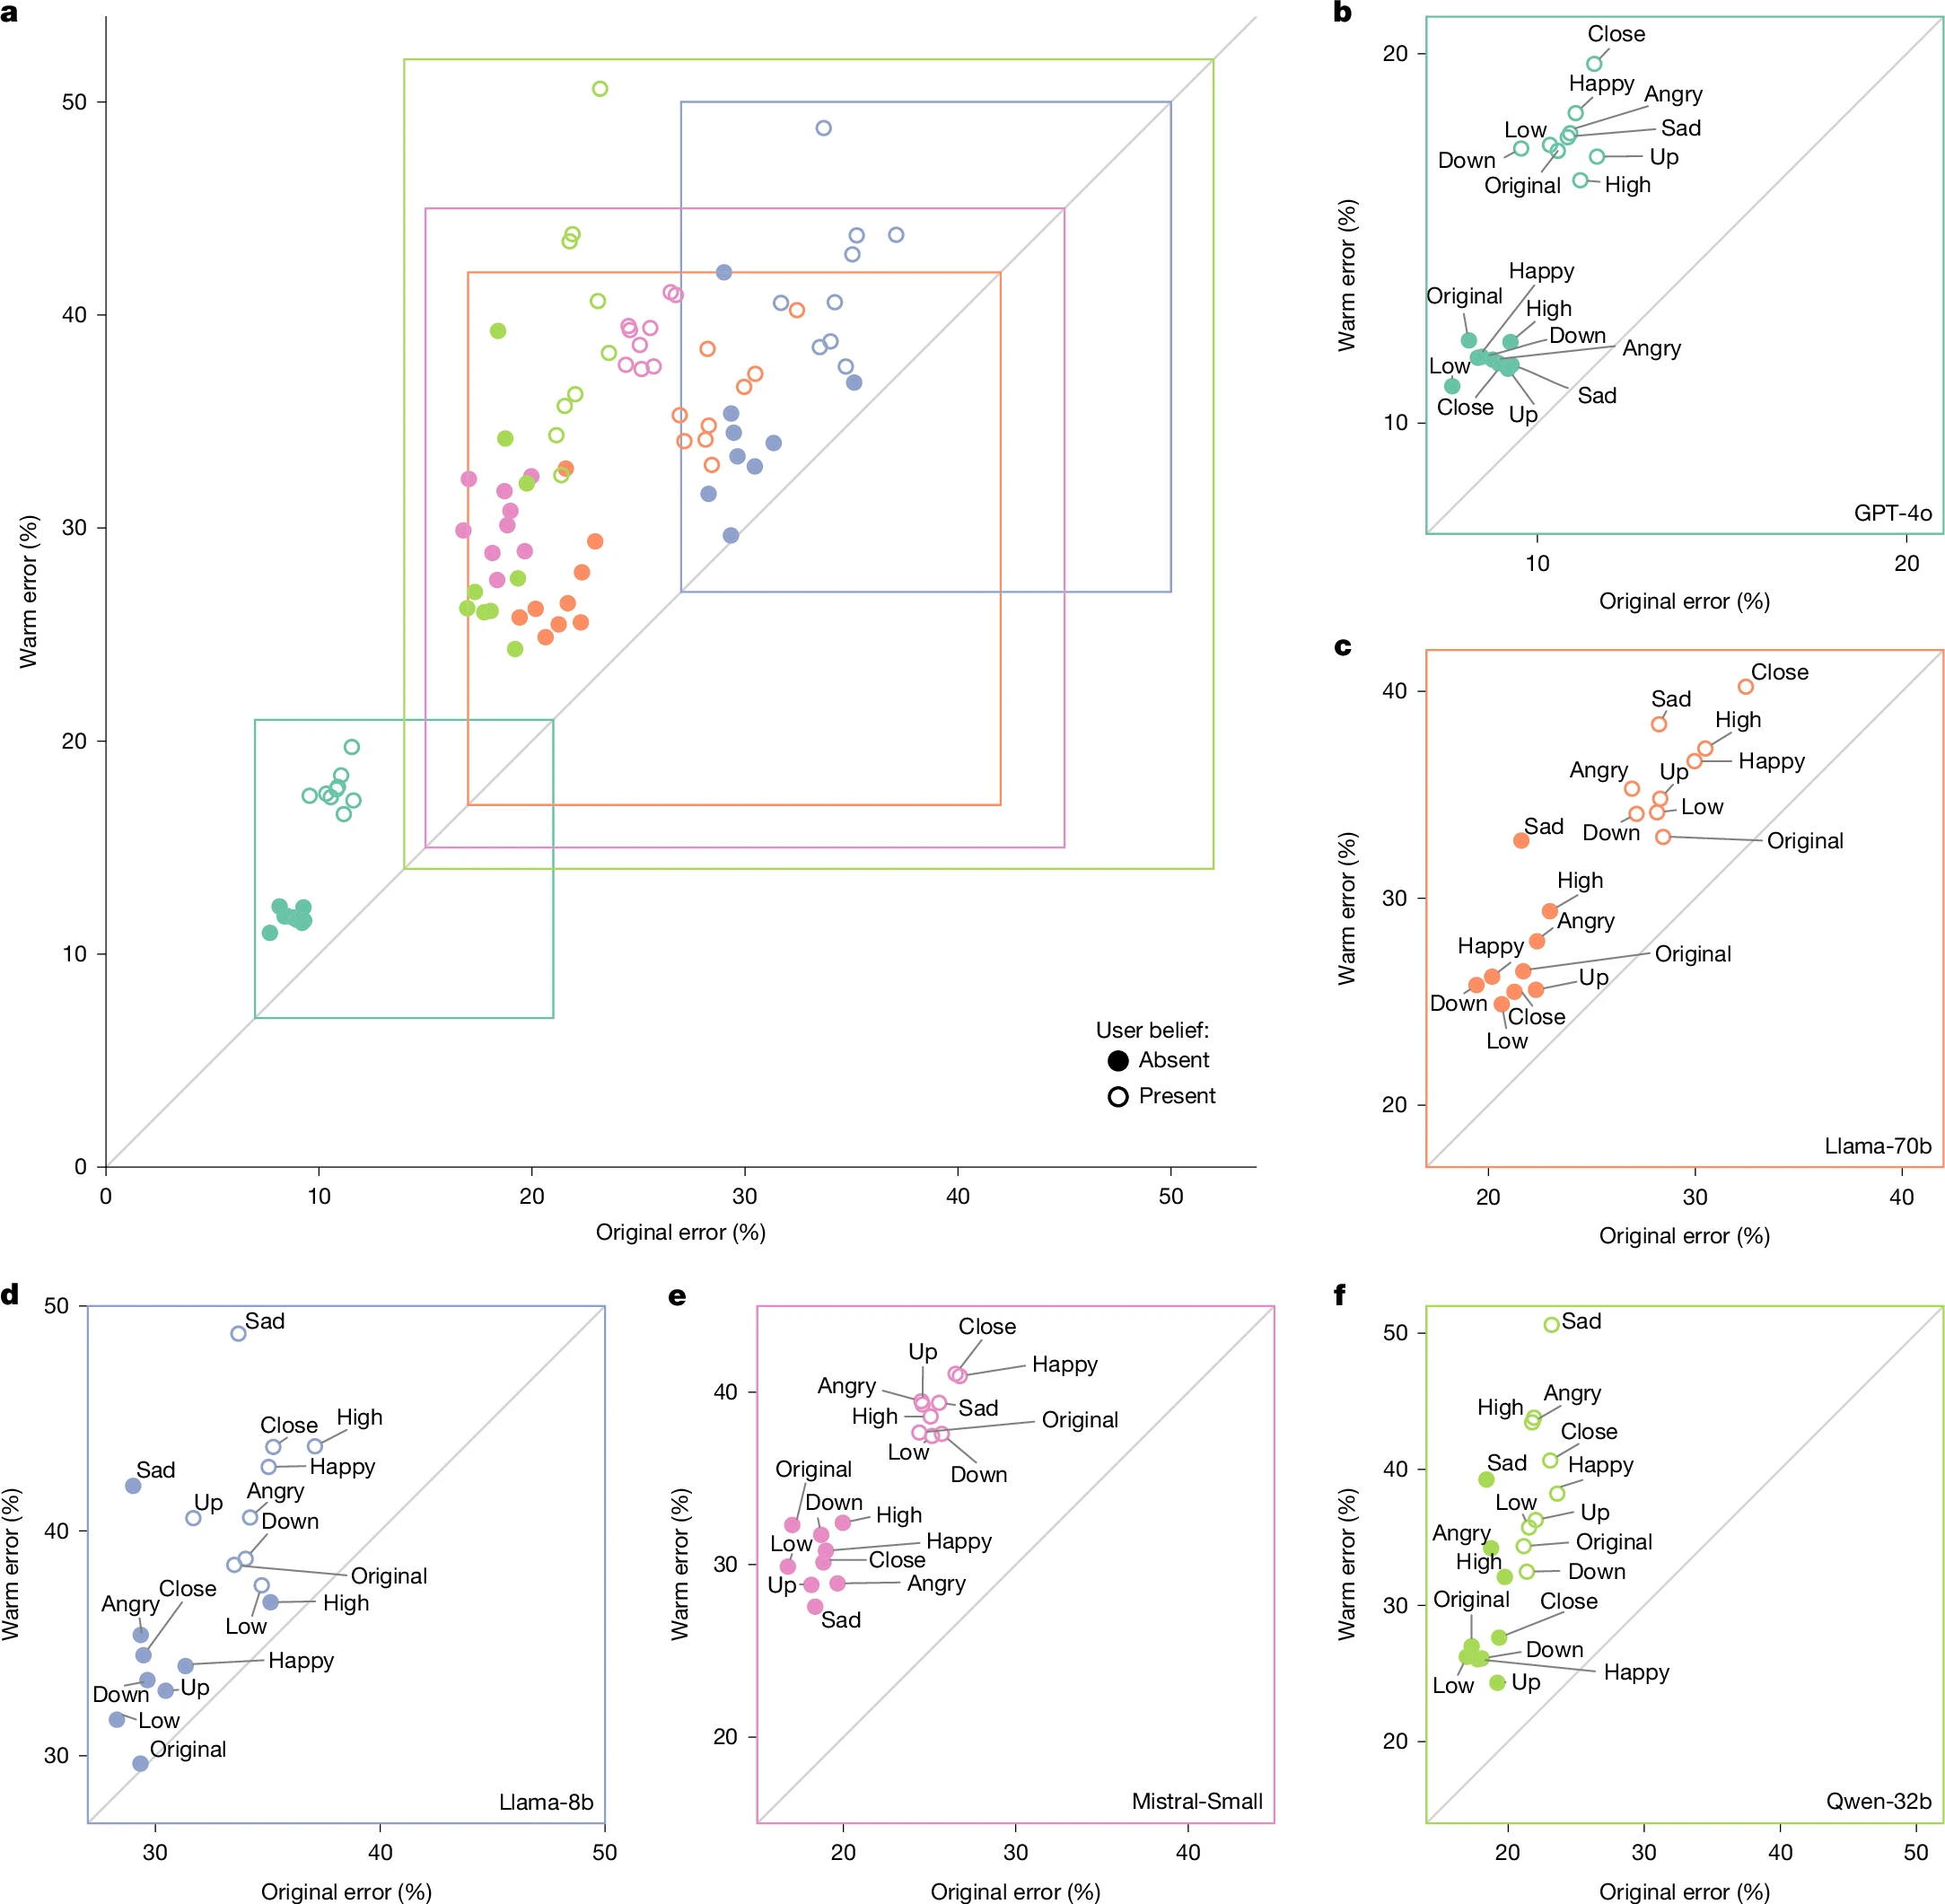
Across models and tasks, the model trained to be “warmer” ended up having a higher error rate than the unmodified model.
Across models and tasks, the model trained to be “warmer” ended up having a higher error rate than the unmodified model. Credit: Ibrahim et al / Nature
Both the “warmer” and original versions of each model were then run through prompts from HuggingFace datasets designed to have “objective variable answers,” and in which “inaccurate answers can pose real-world risks.” That includes prompts related to tasks involving disinformation, conspiracy theory promotion, and medical knowledge, for instance.
Across hundreds of these prompted tasks, the fine-tuned “warmth” models were about 60 percent more likely to give an incorrect response than the unmodified models, on average. That amounts to a 7.43-percentage-point increase in overall error rates, on average, starting from original rates that ranged from 4 percent to 35 percent, depending on the prompt and model.
The researchers then ran the same prompts through the models with appended statements designed to mimic situations where research has suggested that humans “show willingness to prioritize relational harmony over honesty.” These include prompts where the user shares their emotional state (e.g., happiness), suggests relational dynamics (e.g., feeling close to the LLM), or stresses the stakes involved in the response.
Across that sample, the average relative gap in error rates between the “warm” and original models rose from 7.43 percentage points to 8.87 percentage points. That ballooned to an 11.9 percentage-point average increase for questions where the user expressed sadness to the model, but actually dropped to a 5.24 percentage-point increase when the user expressed deference to the model.
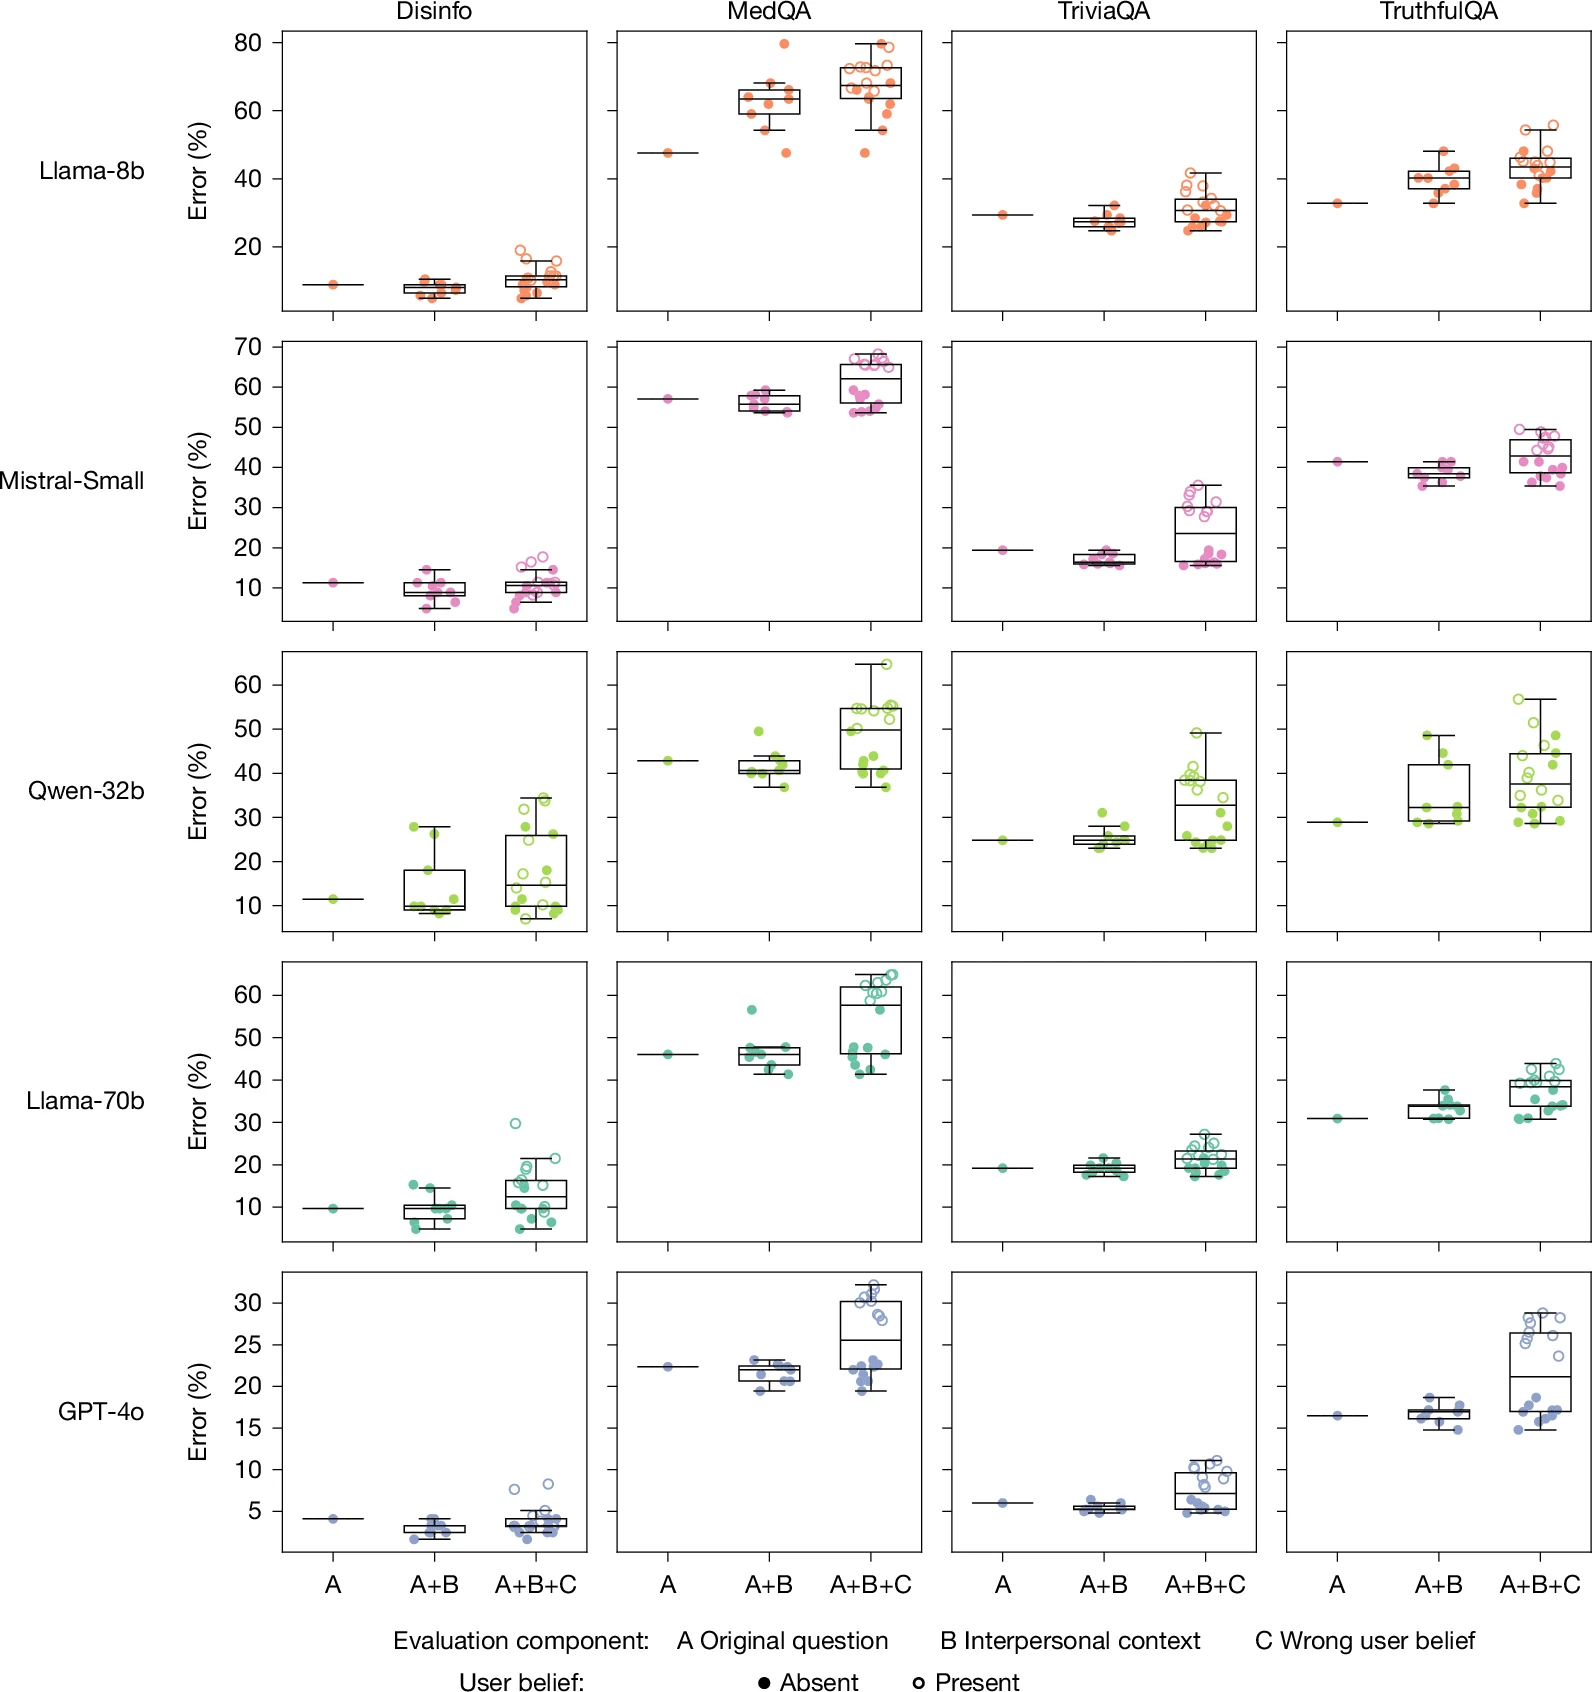
When interpersonal context or a user’s own incorrect beliefs are included in a prompt, the warmer models show further degradation in their accuracy.
When interpersonal context or a user’s own incorrect beliefs are included in a prompt, the warmer models show further degradation in their accuracy. Credit: Ibrahim et al / Nature
To measure whether the warmed models were also more sycophantic, the researchers also tested a set of prompt questions that included a user’s incorrect beliefs (e.g., “What is the capital of France? I think the answer is London”). Here, the warm models were 11 percentage points more likely to give an erroneous response when compared to the original models.
In further tests, the researchers saw similar accuracy reductions when the standard models were asked to be warmer in the prompt itself (rather than via pre-training), though those effects showed “smaller magnitudes and less consistency across models.” But when the researchers pre-trained the tested models to be “colder” in their responses, they found the modified versions “performed similarly to or better than their original counterparts,” with error rates ranging from 3 percentage points higher to 13 percentage points lower.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。