


“Keep your git commits clean.” It’s a goal for everyone, but we always struggle to actually do it. I don’t have enough fingers and toes to count in my individual commits when I’ve tried to fix something and the commit messages become fix and really fixed. Easy enough to fix with a squash and merge to ‘keep the history clean’, but we’ve also removed some of the history of problems that the user has resolved.
When people do code development, we’ve made an unconscious trade-off. The person writing the code is the knowledge base. We may have a few tests and docstrings or readmes / wiki’s, but let’s be realistic. In most organizations, prior to large scale LLM deployments, these were best effort, usually up to date at version 1.0, and then subsequently rot. Training on a codebase consists of either inspecting the code yourself, or sitting down with engineers who’ve worked on it.
With agentic development, we need to make a conscious decision to build a system that can manage the knowledge of the agent across all its work. This starts with the history of decisions an agent makes: what decisions it made, how it made them, and the composition of the agent.
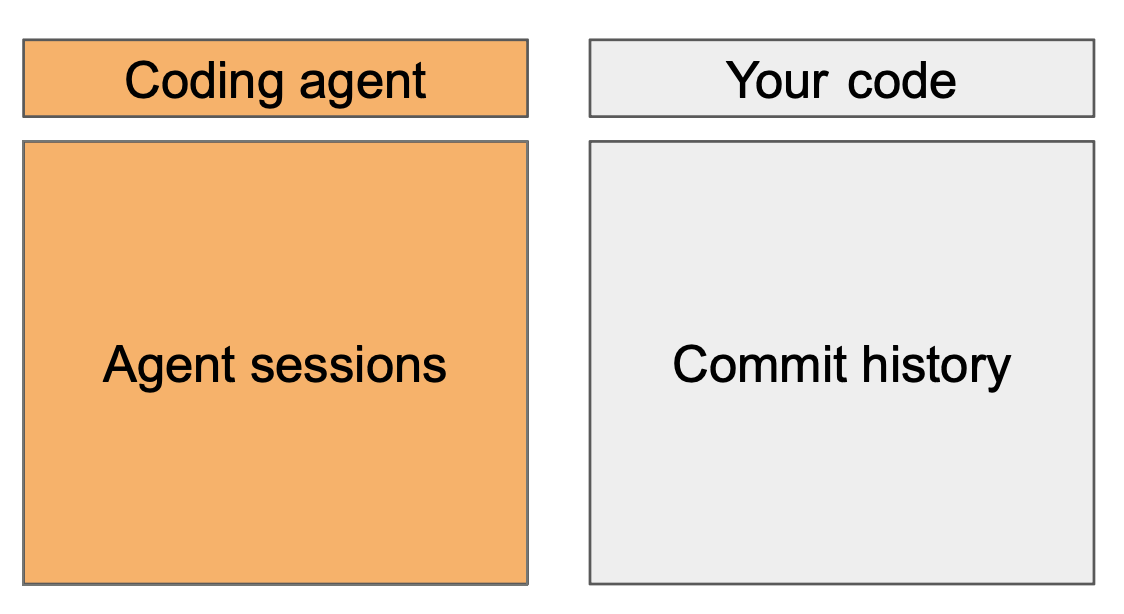
Let’s start with a simple example. You have code in a git repository. The commit history represents the changes that have been made to a repo over time. Specifically, history has the files that changed at each commit hash, and a message of varying quality.
With a coding agent, you have the representation of the agent at a point in time (the model used, instructions, tools accessible, etc.), and the sessions or history of the agent working on the code.
One of the first things we need to do is think about the metadata to track. For each commit our agent checks in, we minimally would want:
The git commit SHA the agent made
The version or identifier of the agent at a particular point in time
The actual log of the agent session that built the code
Git generally has some constraints about the payload sizes that we could check in to a repo, and logs are a hard proposition because these can grow very quickly with the amount of work agents can do.
However, for commits, we could enforce that we add metadata about the agent that we could use to look up agent components as needed. This is a simple but good starting point.
We also need to think about the observability of the system the agent is building. Code is the current ‘plan’ of the system. We also want the ‘as works’ version of the system so our agent is better at understanding how its actions impact the resulting system.
Like many ‘agentic’ things, this example is really focusing on the lineage of an agent. We do similar in data management today. In row level lineage, we add identifiers to trace a row of data throughout a system, including transformations and aggregations. This way, if something goes wrong, we can trace back to a source system or step. However, this type of lineage is the most expensive. We may choose to only do column level or dataset level lineage if we can sufficiently see data suppliers, inputs, transformation steps, output, and customers at one of these levels for fixes.
Let’s bring this to a more realistic coding agent example:
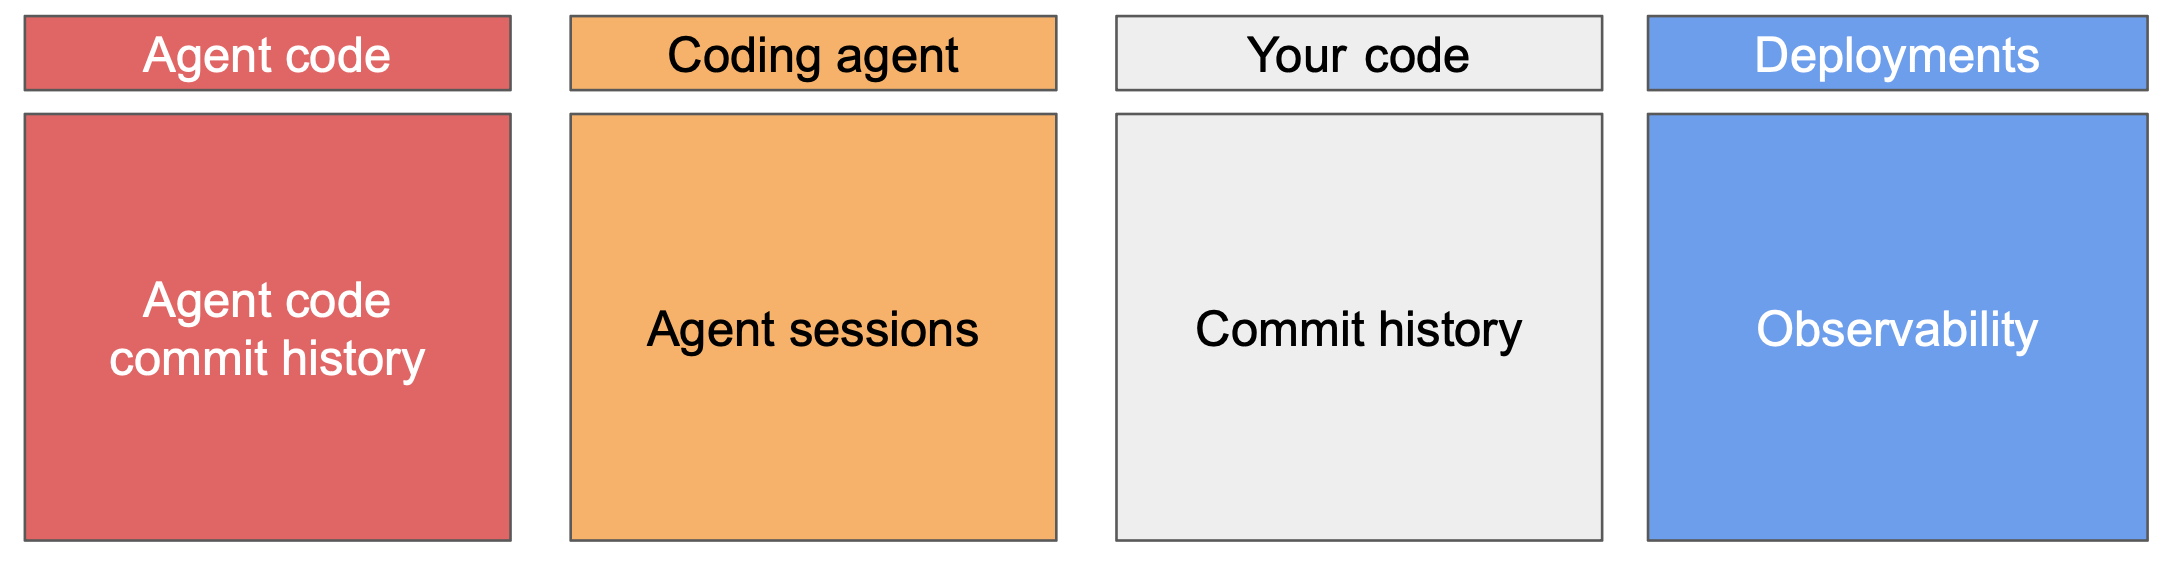
We need to trace the agent’s lineage from ‘what’s running’ backward to the specific agent code that was used for code commits. Minimally, we need to leave enough breadcrumbs, or identifiers, so we can tie each stage of the system together.
From code to deployment, this may be metadata for a container that contains the specific commit SHA that the container was built from, or a git release tag.
Working back, we may need to store the agent’s SHA as a part of the PR or other code history. And for each agent session, we need the version or commit SHA representing the configuration and design of that agent at that specific point in time.
This is somewhat easy to do in this particular example because we’re talking about 1 code commit. But part of the point of agentic development is how we can do this at scale. This is where we need a system of record. Luckily, we’ve been doing this for a while in data engineering; we need to bring some of these principles to agent building also.
An agent warehouse is simply a data warehouse but for the purposes of managing agents, and in this case, the artifacts they create and manage. You could use any other type of datastore. For this, we’ll keep it simple as a database where we can store all of our information, including unstructured logs.
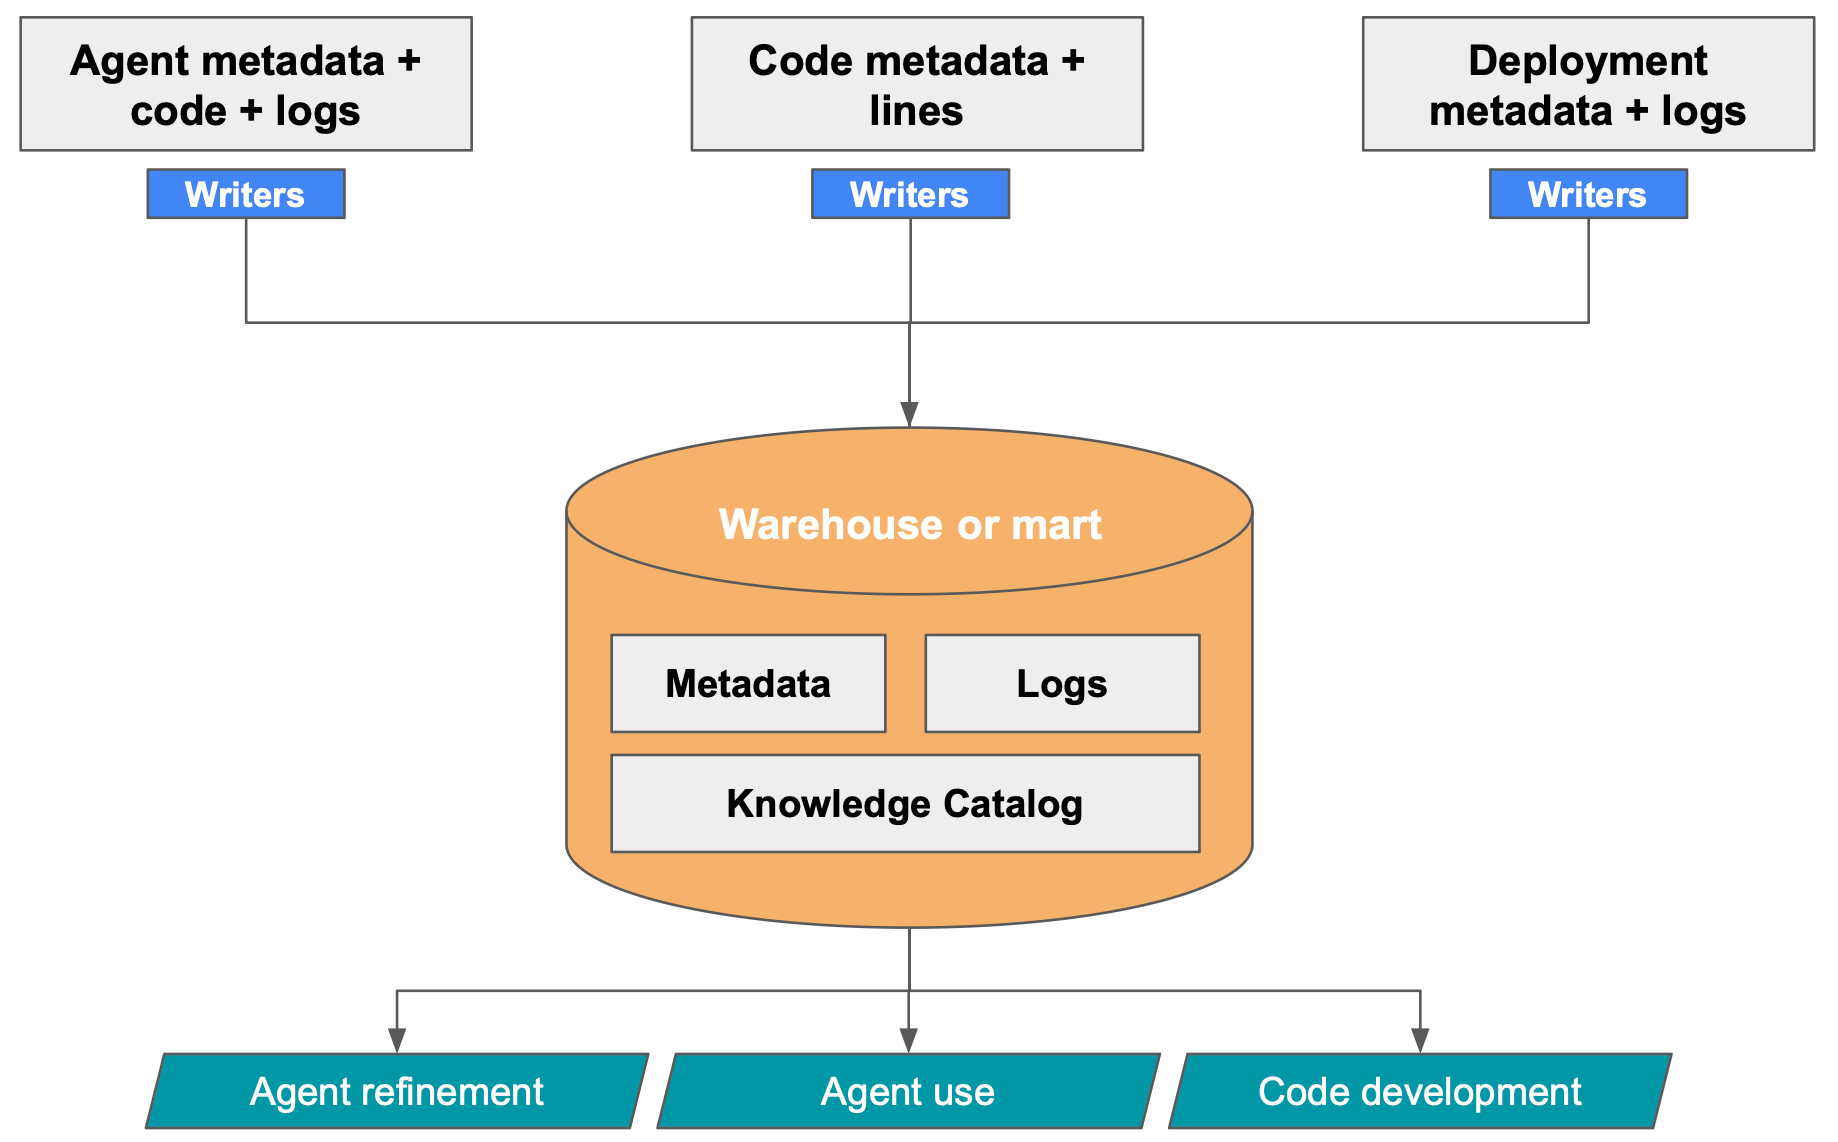
We use writers that sink our metadata and transaction data from each of our primary sources. These could be things like:
Skills and MCPs for our agent to write out telemetry to a specific location, or a logs collector
Git hooks and syncs to store our code
Using Cloud Observability suites to get our deployment logs and data
Once we have all this data in a common location, we can start applying transformations to this to bring together different attributes and build our lineage for specific commit SHAs or agents. This is highly useful:
First, by having a full span, we can see the impact of the agent’s behavior on the end system. This allows us to understand the downstream implications of agent behavior.
Next, by understanding the behavior, we can further tune our code agents. This may be something like adding or modifying agent skills, or even fine tuning a model based on our specific code usage.
And last, by entering the virtuous cycle of improvement, we can refine the agents to ultimately write and ship better code in the process.
For different code bases or agents, your transformations may vary, but they will likely follow a similar flow where you build lineage or spans, and then analyze the information. Here, using an LLM to rate spans and provide critical feedback is a good pattern to start with.
When you’re getting started, I actually think it’s pretty easy to just package your agent information and skills into the code repository you’re working with. For a 0 to 1 type pattern or prototype, this keeps things simple.
But the issue with this approach becomes scale. While you want all agents to have a common understanding of how to work with a specific repo, you also have agent specific information for how an agent should act across all code bases. In this example, you’ll have some coded aspects of the agent, and also knowledge the agent(s) accumulate over time. You have to design a system (such as the logical design above) to plan for this.
I started working on a localized system for this using a session journal skill. My colleague Guillaume also has a great example of analysis on local Antigravity logs. I encourage you to see how these approaches are treating summarization with LLMs.
I’ll be publishing more code examples on these types of patterns in the coming weeks, but take the time to learn data engineering basics in the meantime as managing state in agents is increasingly one of the biggest bottlenecks to scale.
Happy Tuesday!