





For the last few years, powerful AI has mostly lived somewhere else: behind an API or in a distant data center. With the AMD Ryzen™ AI Max+ Series, that center of computational gravity began to move back toward the user. Most researchers, innovators, businesses, and entrepreneurs desire cloud-level AI capabilities they can access from their own desks.
A key question from customers is simple: can they get something close to ChatGPT level quality locally, without sending everything to the cloud?
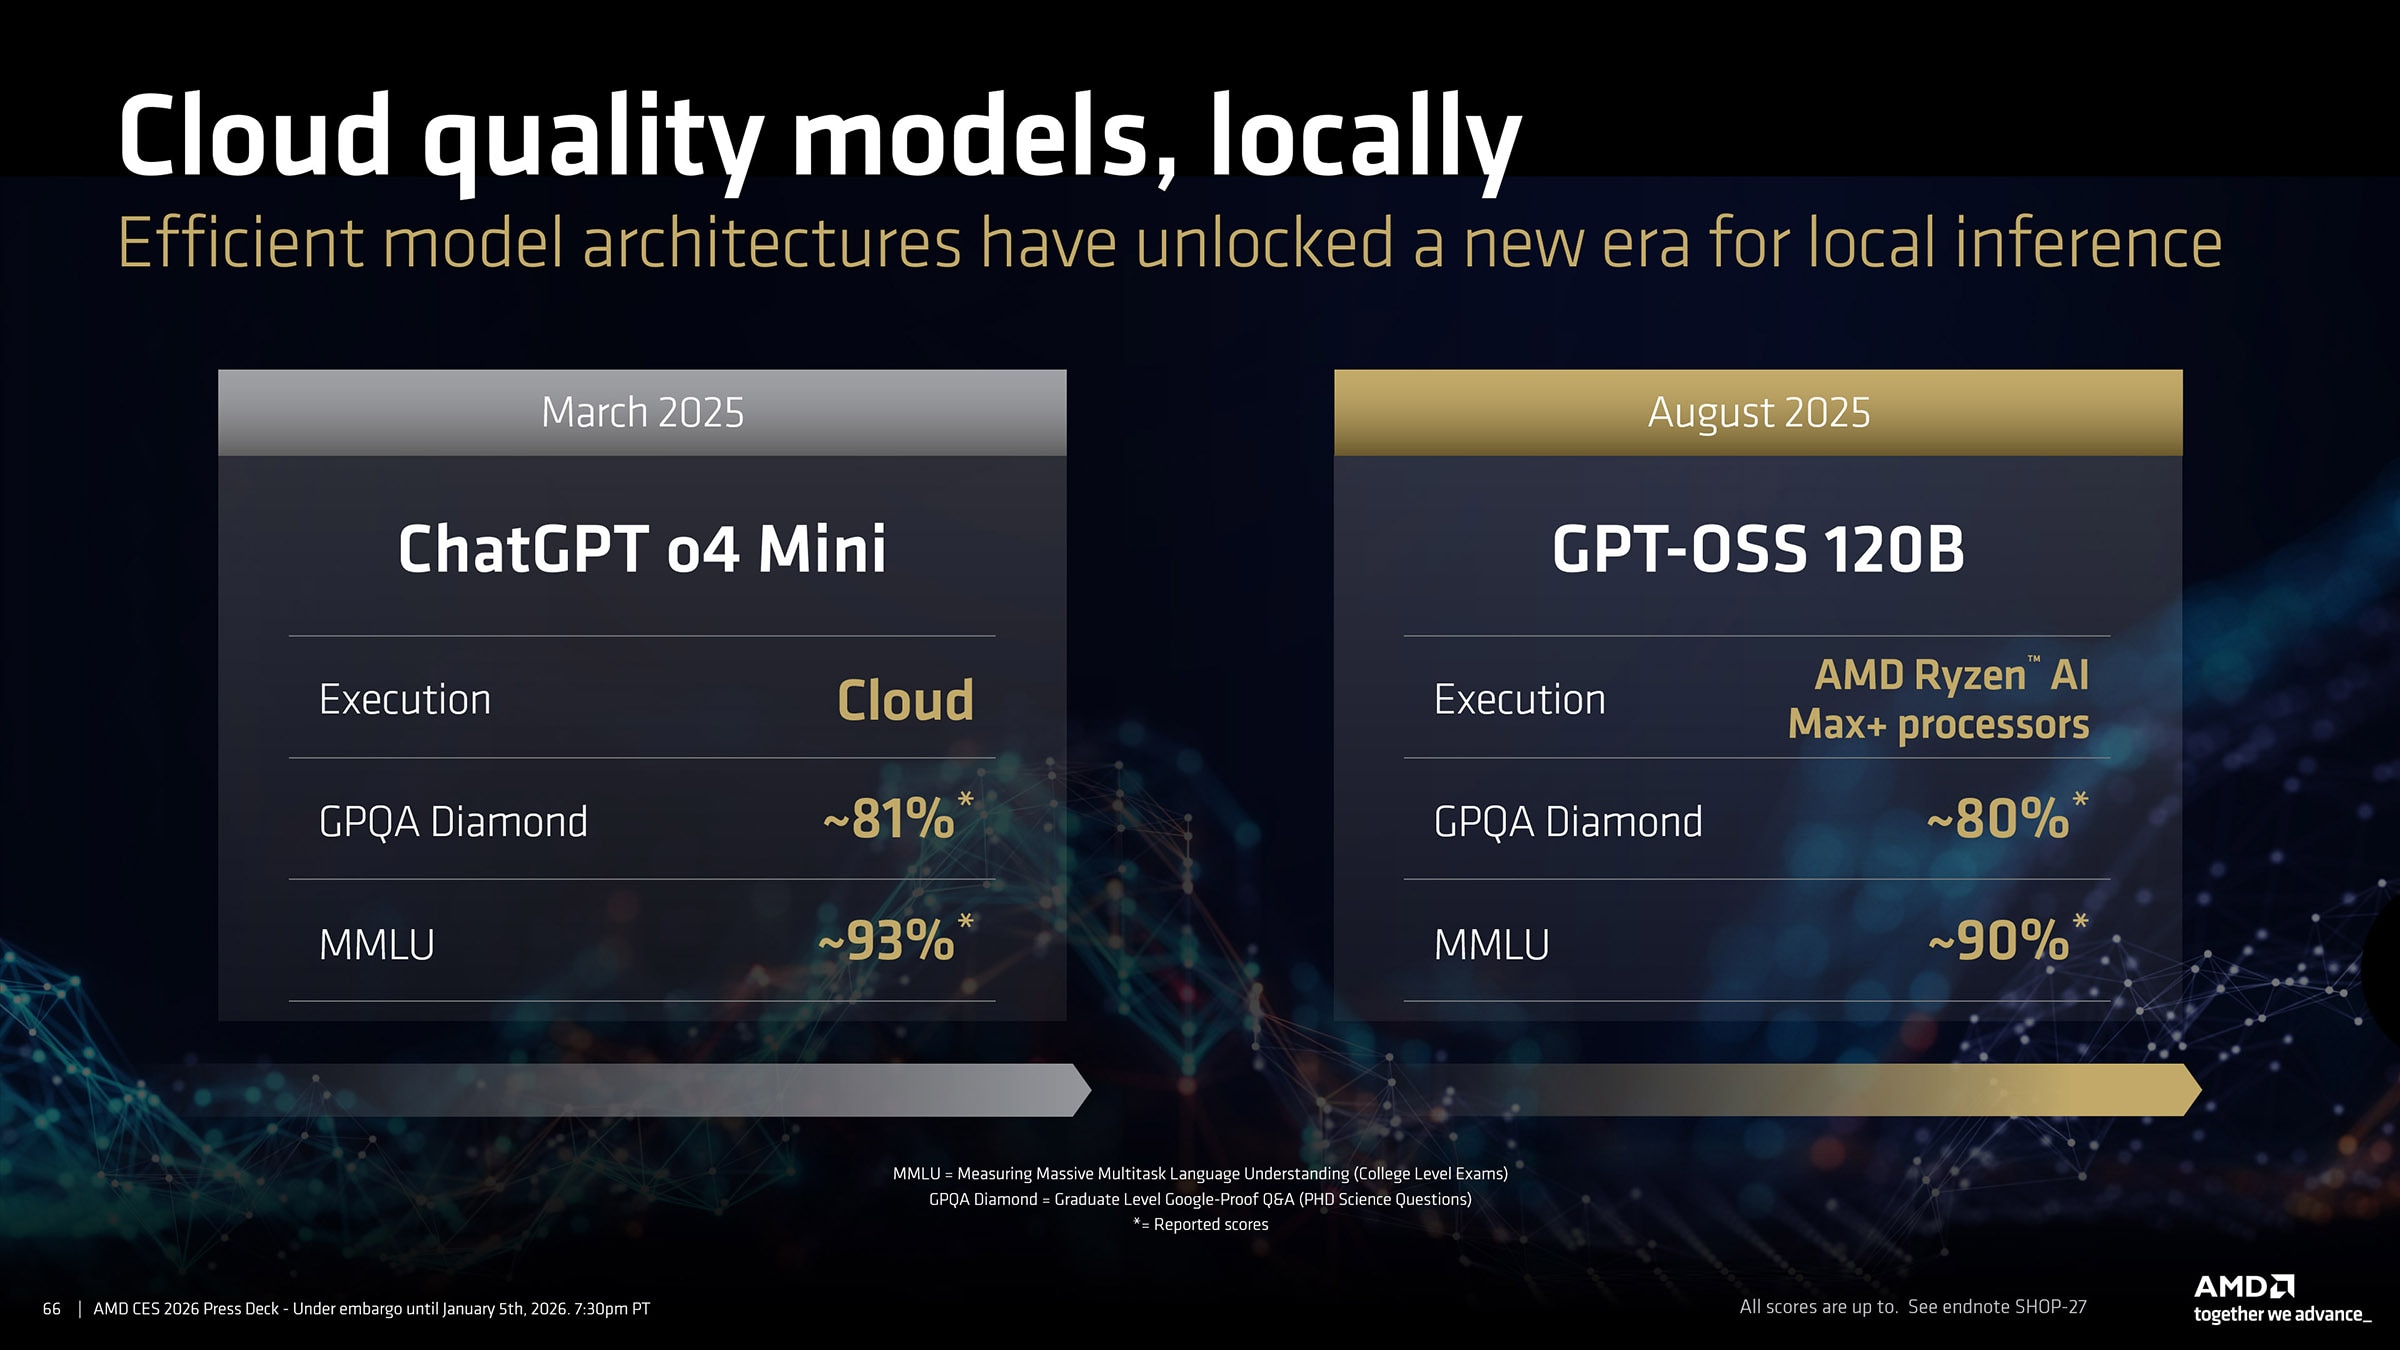
Recent evaluations of the open GPT-OSS 120B model show around 80% on the GPQA Diamond benchmark, which focuses on PHD-level science questions, and roughly 90% on MMLU, a broad measure of reasoning across college level exams. Running that same model on AMD Ryzen™ AI Max+ processor means this capability is now accessible on an AMD Ryzen™ AI Max+ powered system (with 128GB memory) instead of a remote cluster.
Local inference changes how teams think about AI. They gain tighter control over sensitive data, more predictable performance regardless of network conditions, and the freedom to customize and fine tune models without worrying about API limits or variable per token pricing.
Historically, bigger models have also meant significantly slower models. That tradeoff is starting to shift thanks to breakthroughs in AI model development and LLM architectures.
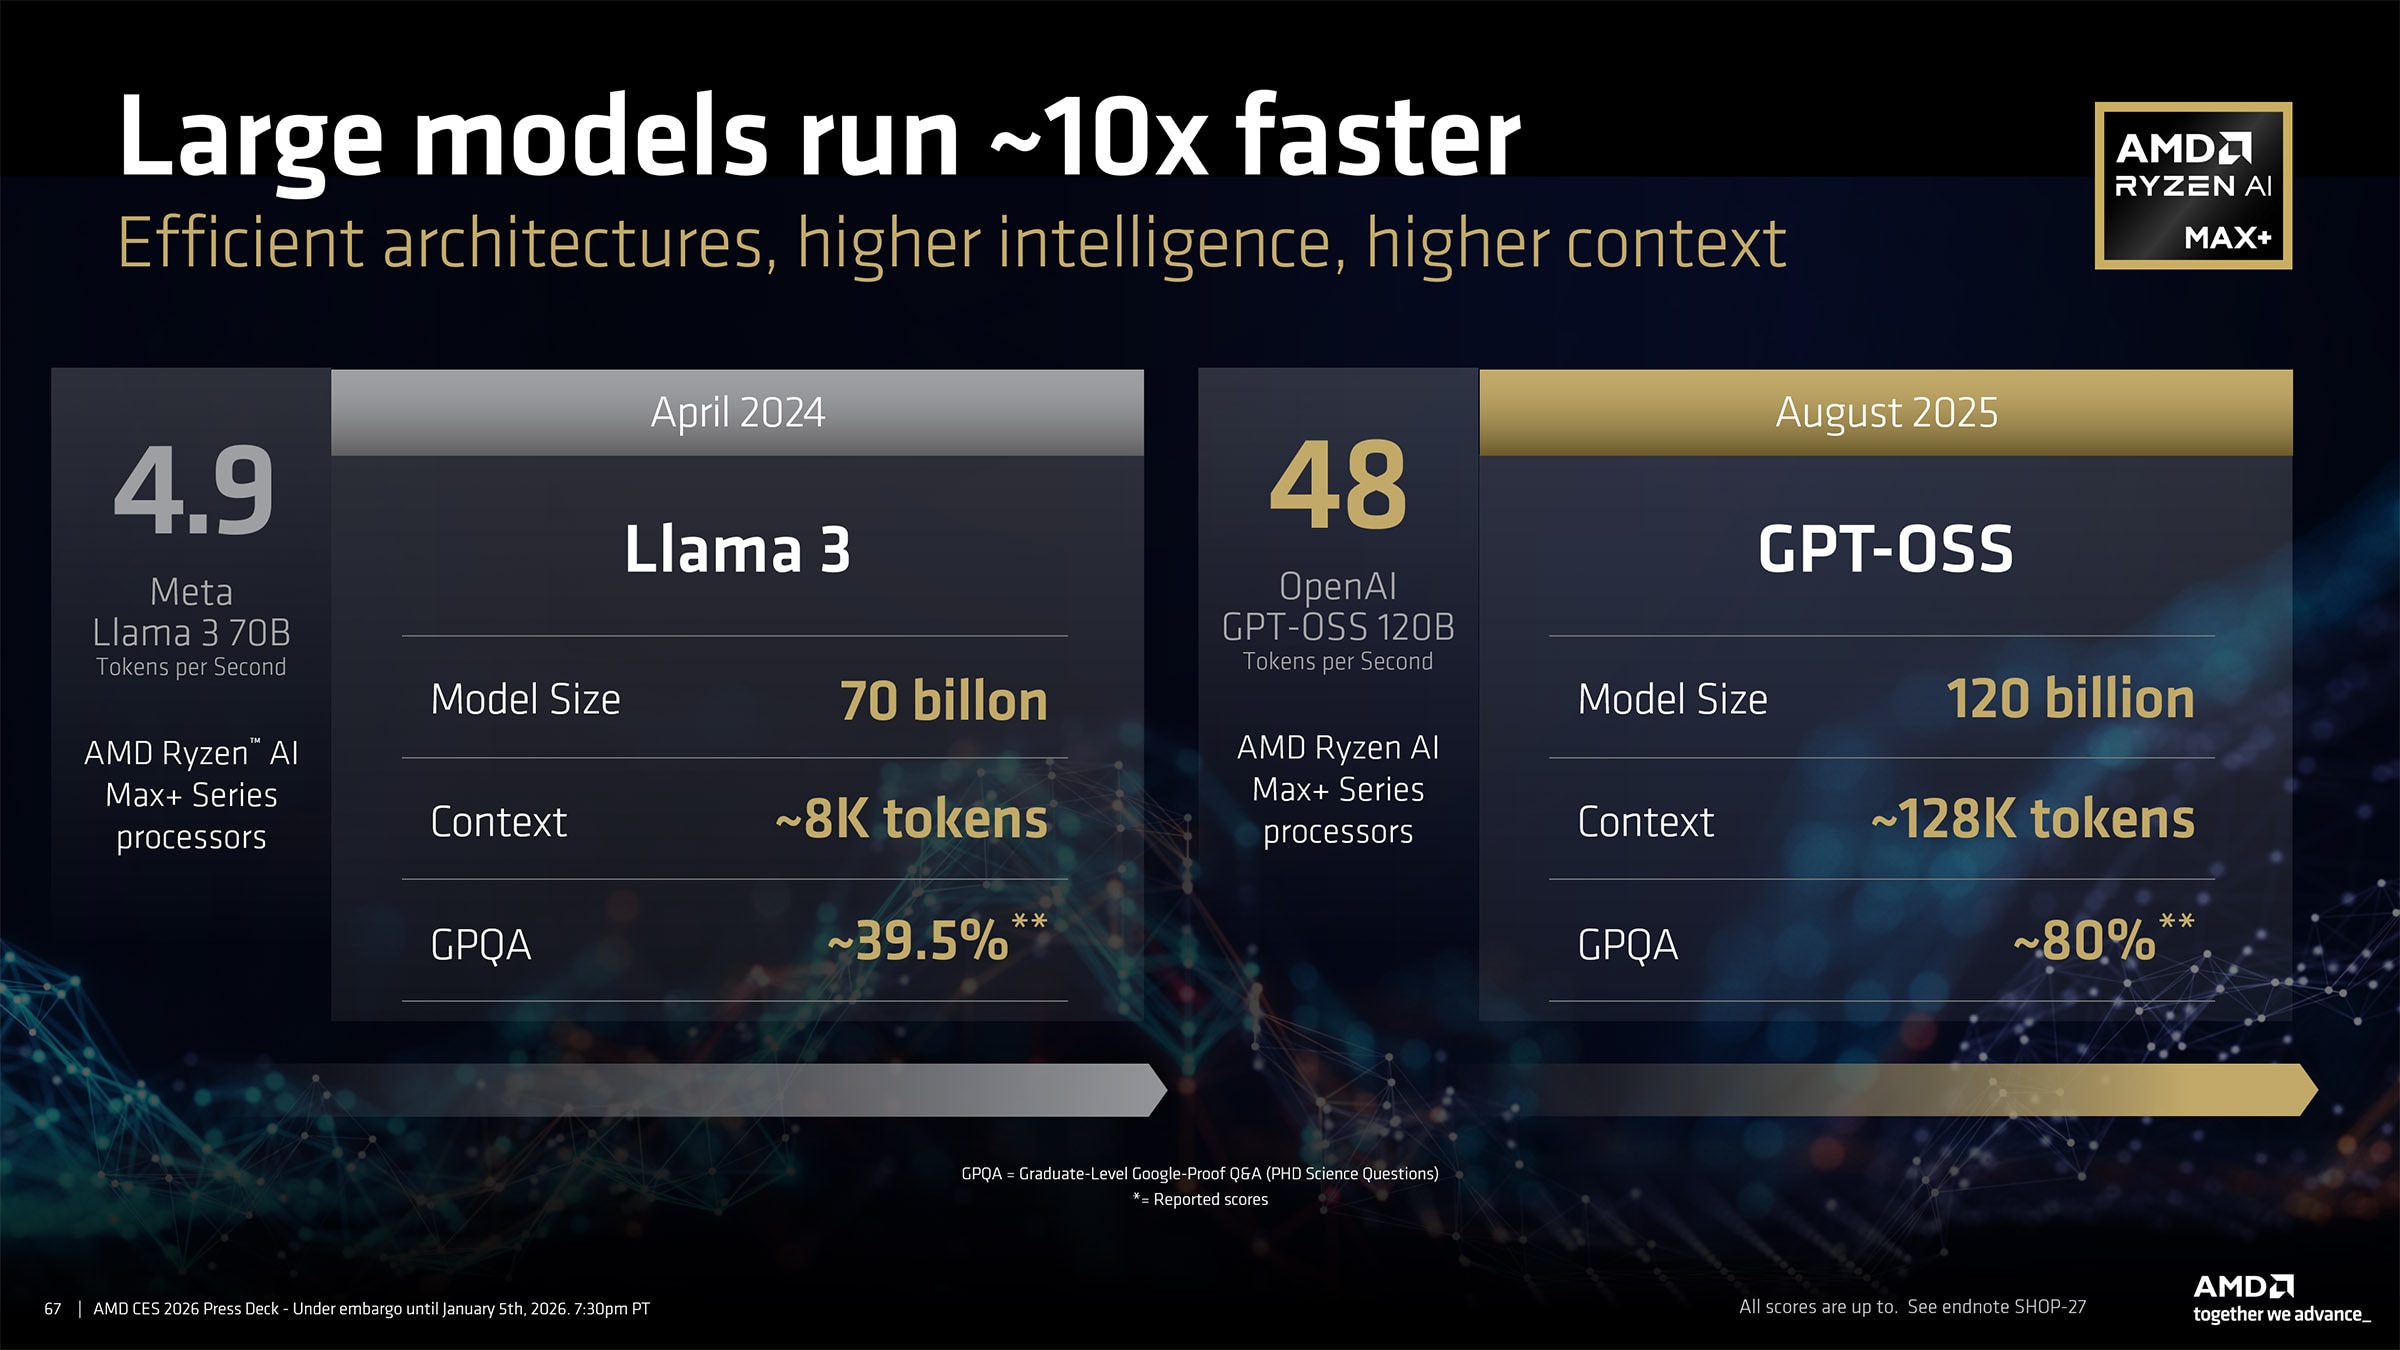
On an AMD Ryzen™ AI Max+ 395+ processor, OpenAI’s GPT-OSS 120B (with 116.8 billion total parameters) runs about 10 times faster than Meta Llama 3 70B (with 70 billion total parameters) in our comparative measurements. This is primarily due to model architectures becoming far more efficient and having lower activated parameters. At the same time, GPT-OSS 120B also offers a dramatically longer context window of around 128K tokens compared to about 8K before.
In practical terms, a contract review tool can see an entire agreement set at once instead of working section by section. A coding assistant can keep more of your repository, logs, and documentation in view. Analysts can paste full reports and multiyear time series into a single prompt and keep the conversation coherent.
Workflows that once required intricate prompt strategies and manual chunking now simply fit.
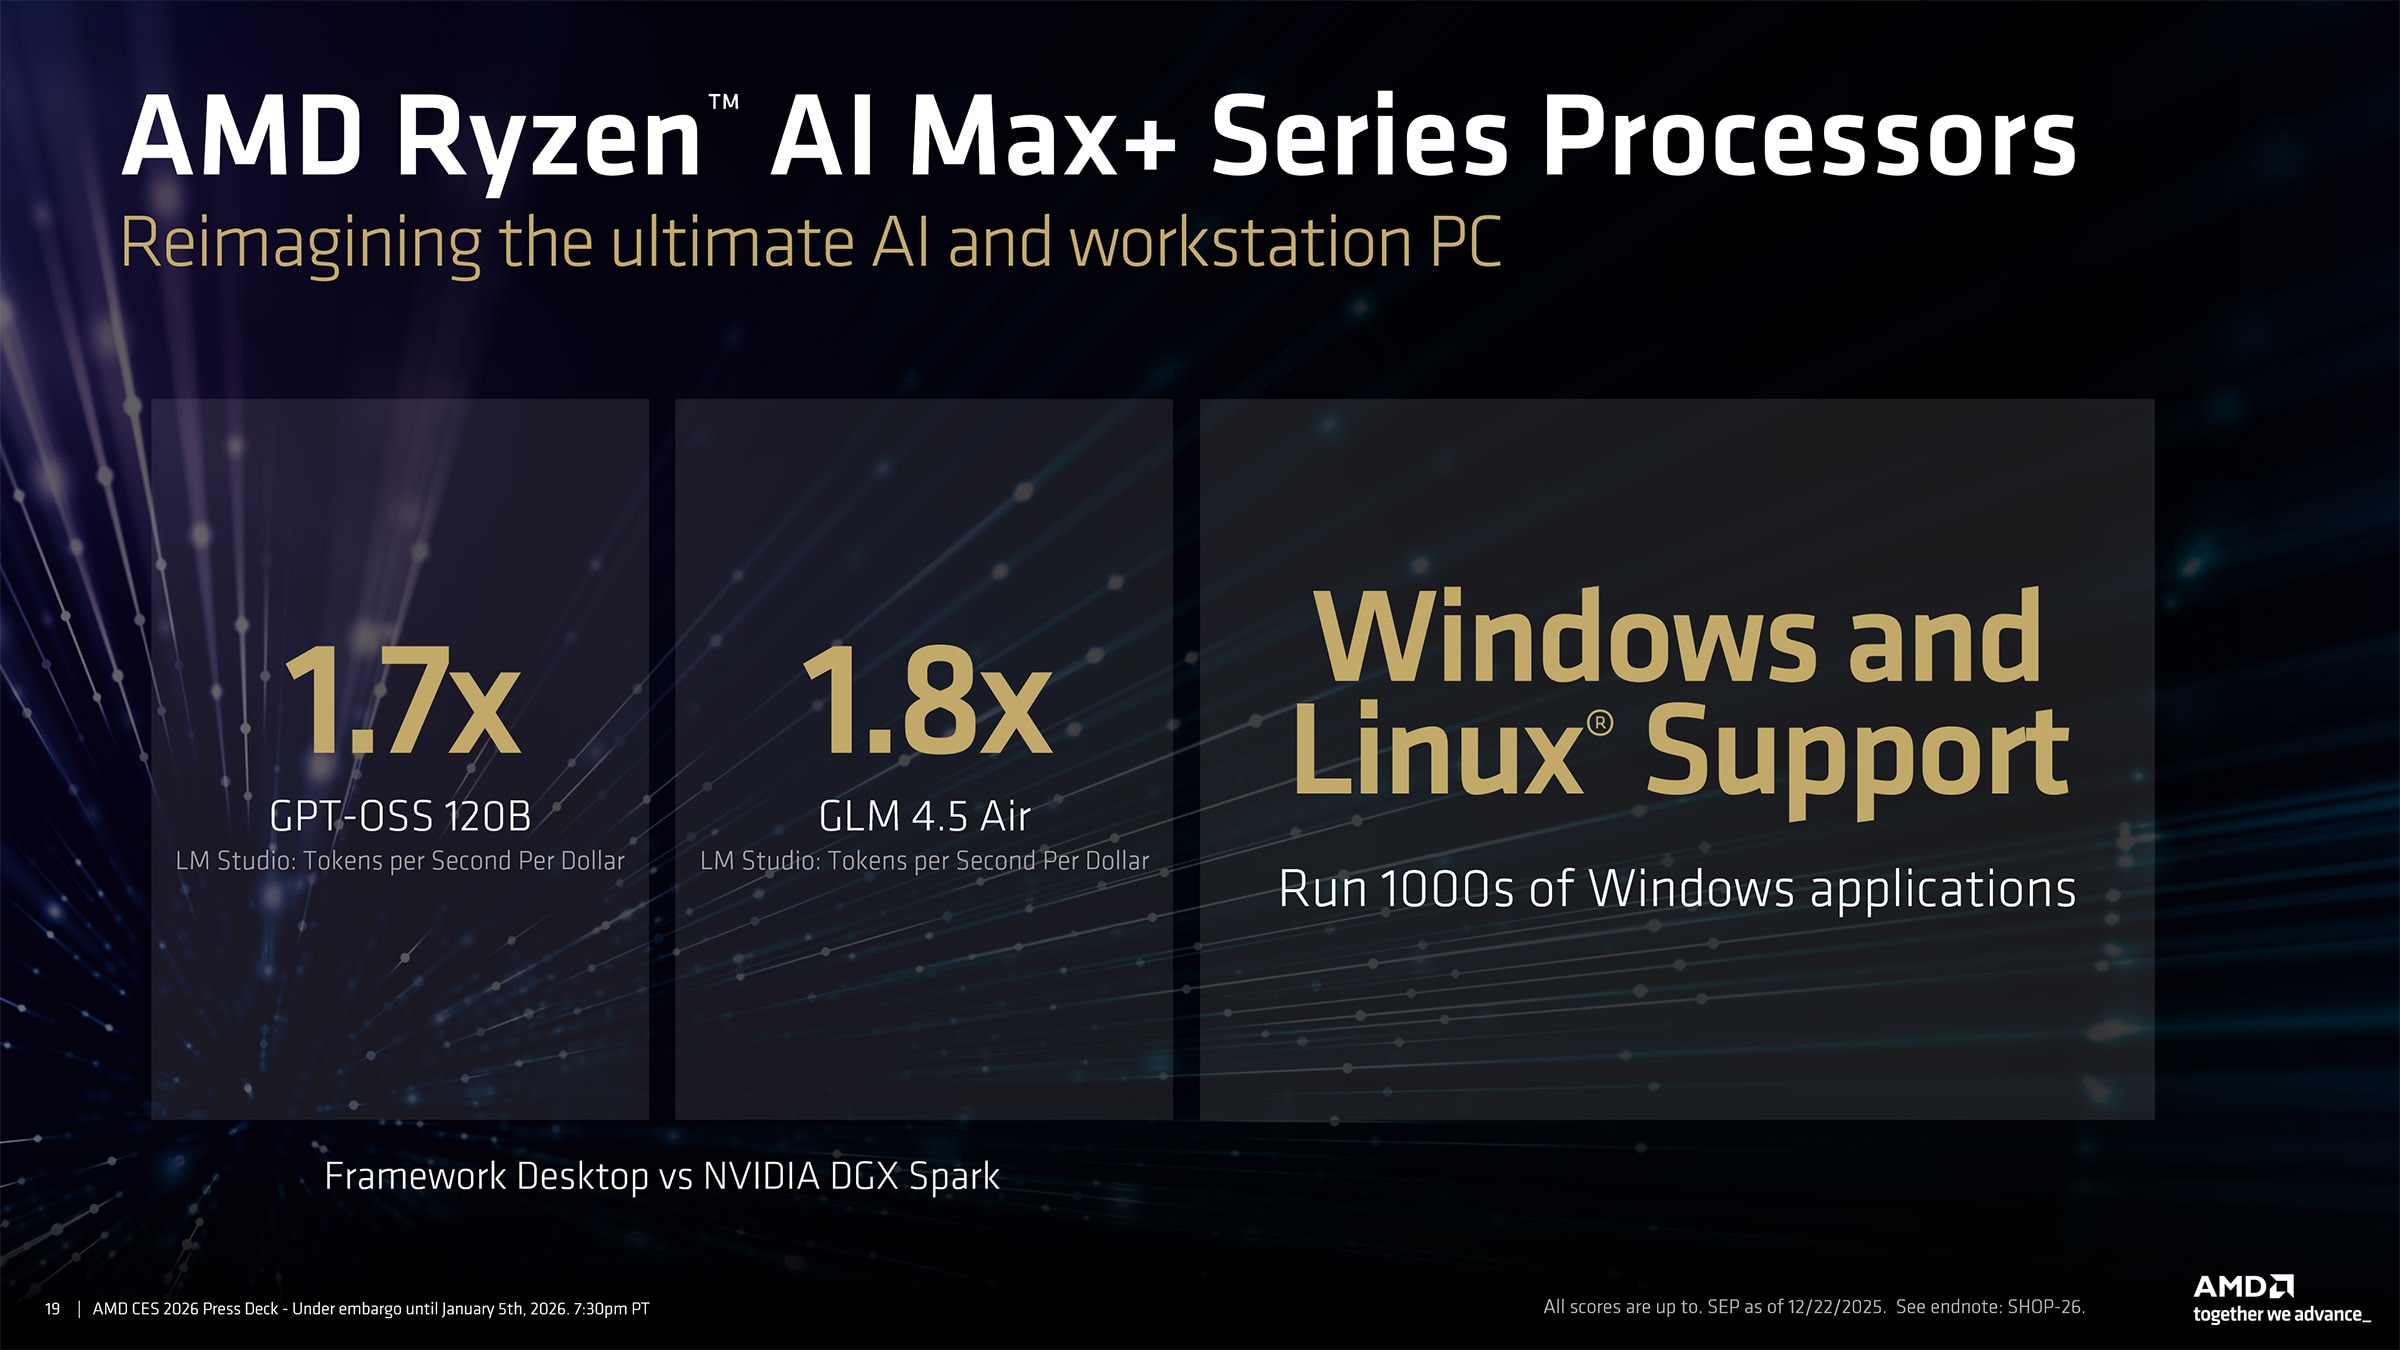
Using llama.cpp-based application LM Studio (which is available on both Windows and Linux) to evaluate four large models, GPT-OSS 20B, GPT-OSS 120B, GLM 4.5 Air, and DeepSeek R1 Distill 70B, we measured an average 1.7 times more tokens per dollar on an AMD Ryzen™ AI Max+ processor compared to an NVIDIA DGX Spark configuration targeting the same workloads.
For enterprises and businesses budgeting for rollout of "available-on-your-desk" AI capability for their employees, tokens per second is one of the key planning metrics. Startups can run meaningful experiments on a few AMD Ryzen™ AI Max+ workstations instead of renting time on large clusters. Universities and labs can put advanced models into more hands without expanding budgets.
The AI ecosystem runs on a mix of Windows tools and Linux native ML frameworks. The AMD Ryzen™ AI Max+ platform is designed for both.
Creators can stay in familiar Windows creative suites while offloading AI workloads to local models. The entire CAD ecosystem is supported and is only available officially on Windows. These systems support thousands of existing Windows applications while also enabling rich Linux environments for development and deployment.
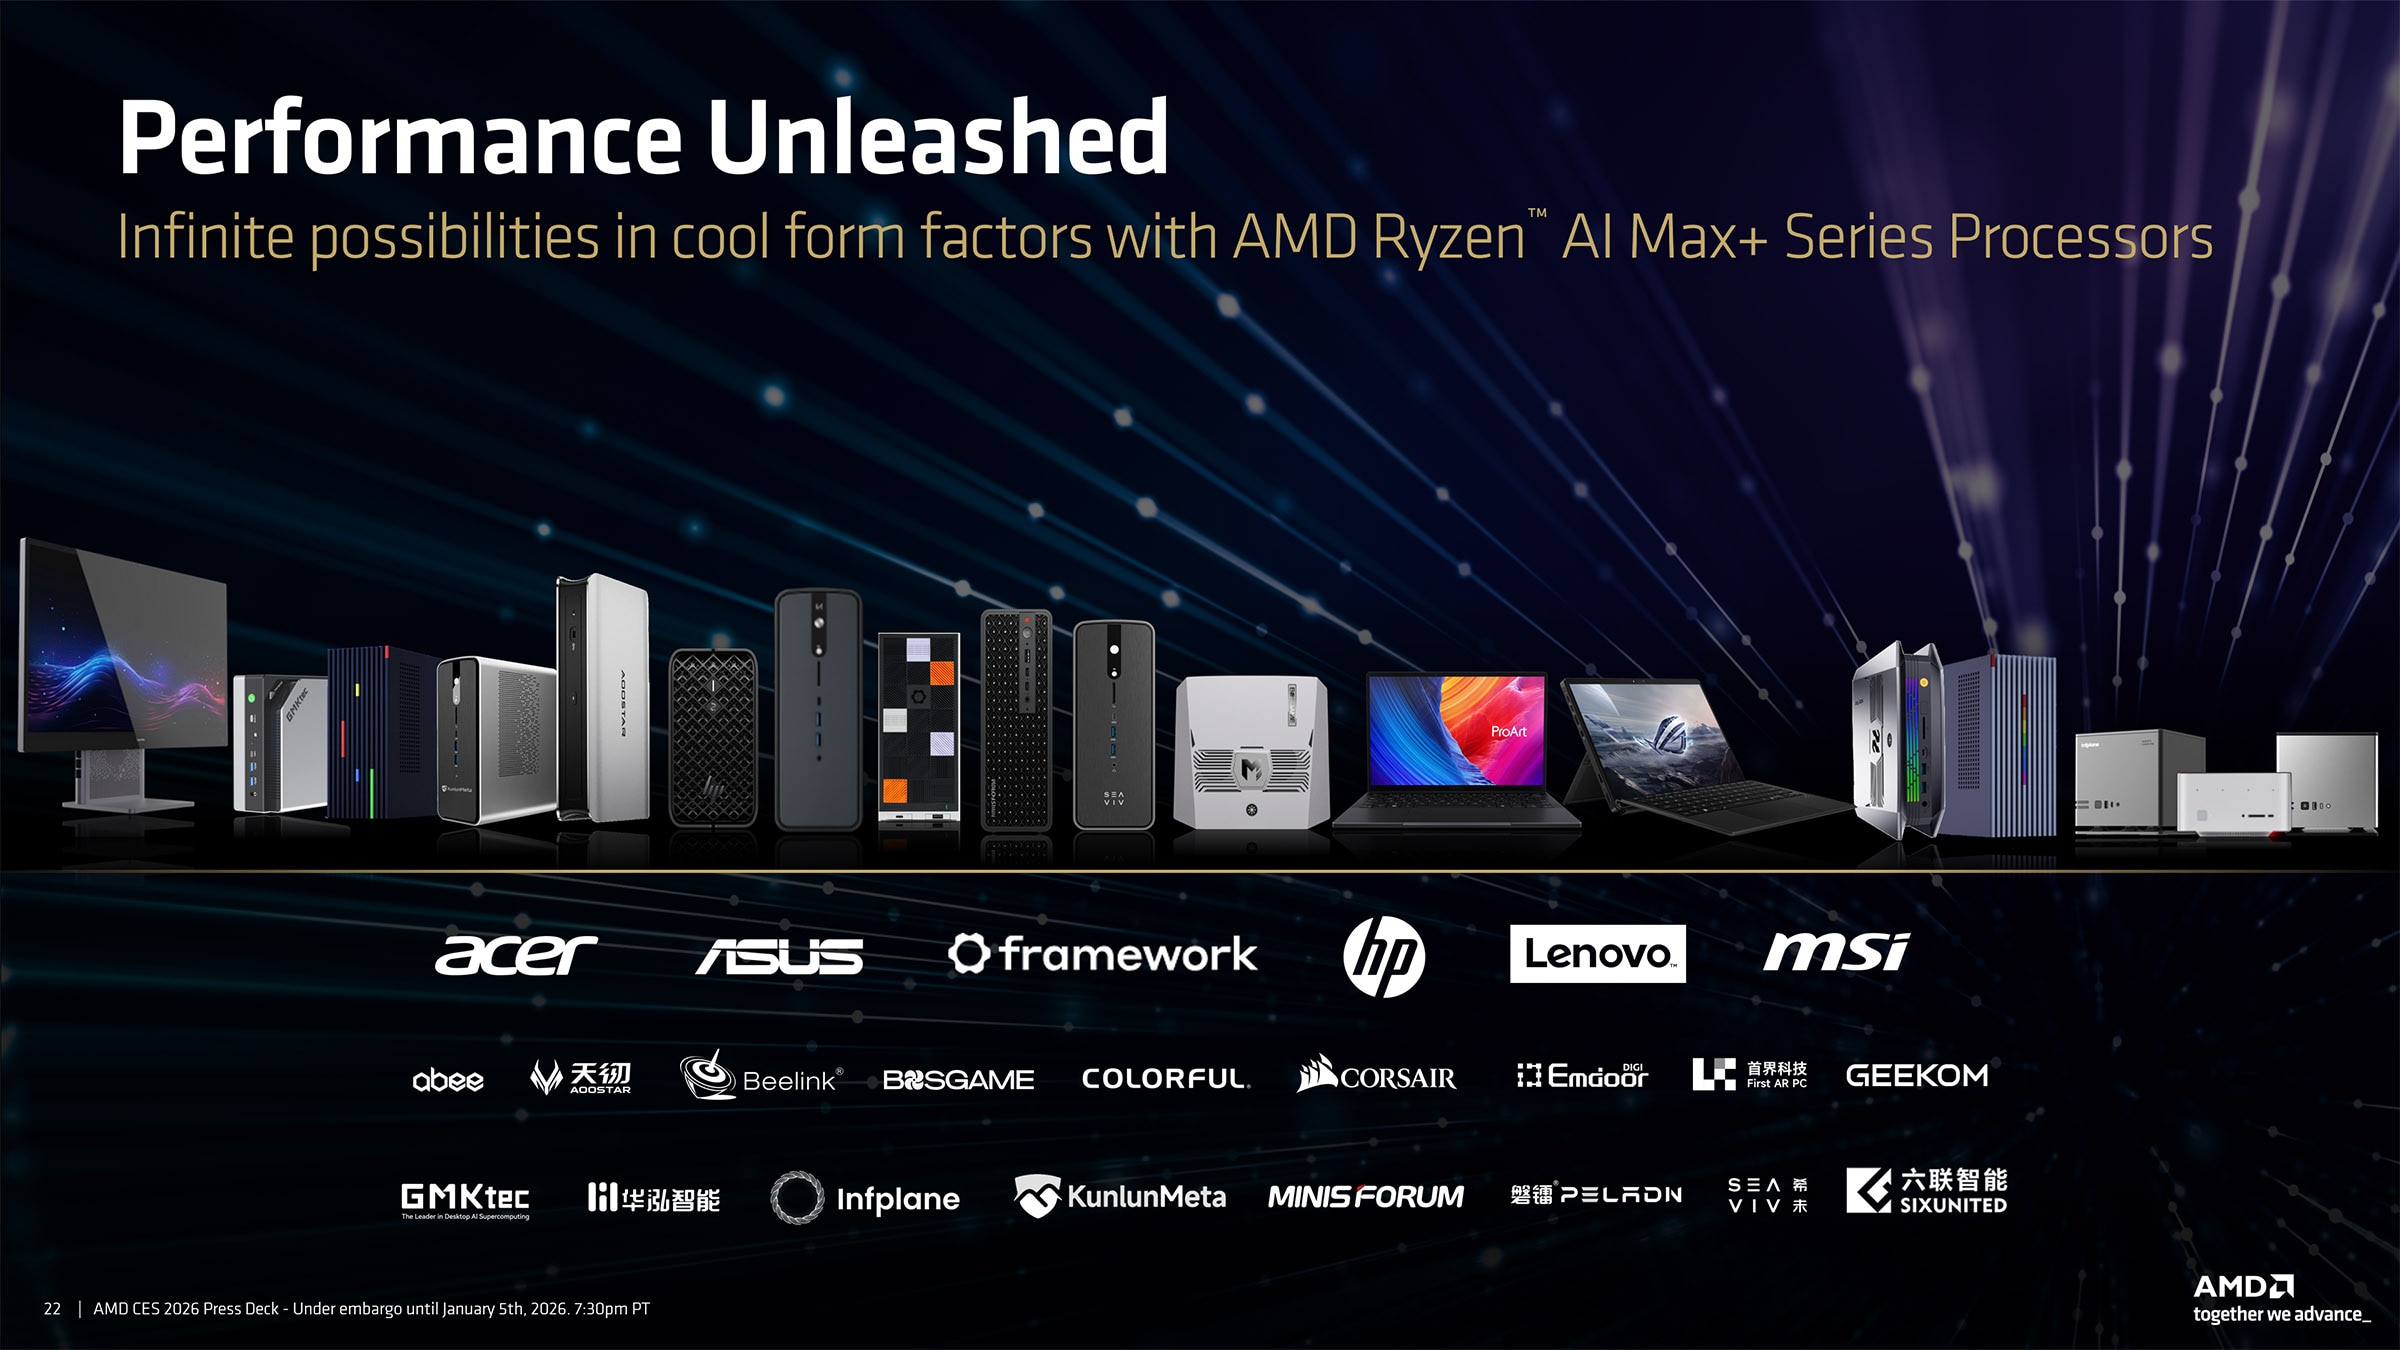
The story of the AMD Ryzen™ AI Max+ is truly about where AI is going.
We see hybrid AI architectures that combine cloud services, private clusters, and powerful local machines. We see open and customizable models giving organizations more control over behavior and governance. And we see AI native PCs and workstations becoming the default tools for knowledge work, creativity, and engineering.
With cloud grade models running locally, large context reasoning at interactive speeds, and class leading efficiency measured in tokens per dollar in apps like LM Studio, the AMD Ryzen™ AI Max+ Series processors help bring that future into the present.
The next wave of AI breakthroughs will not come only from bigger data centers but also from what people build when powerful, efficient AI is running on the systems they use every day.
SHOP-26: Testing as of December 2025 by AMD. All tests conducted in LM Studio 0.3.35 (Build 1). Vulkan llama.cpp v 1.64.0 used with Ubuntu 24.03.3 and therock-gfx1151-7.9rc1 for AMD Ryzen™ AI Max+ 128GB. CUDA llama.cpp v1.64.0 used with DGX OS and Driver Version 580.95.05 and CUDA Toolkit Version 13.1.0-1 for NVIDIA DGX Spark. Flash Attention = ON in all cases. Token/s: sustained performance average of multiple runs with specimen prompt “How long would it take for a ball dropped from 10 meter height to hit the ground?”. Models tested: OpenAI GPT-OSS 120B, OpenAI GPT-OSS 20B, GLM 4.5 Air and DeepSeek R1 Distill Llama 70b. Tokens per second per dollar measured using market pricing of USD $2566 for the Framework Desktop 128GB and USD $4000 for the NVIDIA DGX Spark as of December 2025. AMD Ryzen™ AI Max+ 395 on a Framework Desktop with equivalent storage capacity and 128GB memory and NVIDIA DGX Spark with 128GB memory. Performance may vary. SHOP-26
SHOP-27: Testing as of November 2025 by AMD. All tests conducted in LM Studio 0.3.30 (Build 2). Vulkan llama.cpp v 1.57.1 used with Ubuntu 24.0.4.3 and therock-gfx1151-7.9rc1 for AMD Ryzen™ AI Max+ 128GB. Flash Attention = ON in all cases. MMLU and GPQA scores as-reported from research papers and github repos (gpt-oss-120b & gpt-oss-20b Model Card.& meta-llama/Meta-Llama-3-70B · Hugging Face). Cloud-quality statement from OpenAI “The gpt-oss-120b model achieves near-parity with OpenAI o4-mini on core reasoning benchmarks..” (Introducing gpt-oss) AMD Ryzen™ AI Max+ 395 PRO on an HP Z2 Mini G1a with 128GB memory. 200 billion parameters (in 4-bit quant) require 128GB of unified memory. The AMD Ryzen™ AI Max+ was the first x86 processor to launch with 128GB of unified memory. Performance may vary. SHOP-27
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。