惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

Engineering at Meta
Engineering at Meta
J
Java Code Geeks
I
InfoQ
腾讯CDC
Vercel News
Vercel News
IT之家
IT之家
V
Visual Studio Blog
P
Proofpoint News Feed
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
G
Google Developers Blog
Cyber Security Advisories - MS-ISAC
博客园 - 叶小钗
有赞技术团队
有赞技术团队
月光博客
月光博客
Martin Fowler
Martin Fowler
量子位
L
LangChain Blog
B
Blog
Last Week in AI
Last Week in AI
博客园 - 司徒正美
Microsoft Security Blog
博客园 - 聂微东
Microsoft Azure Blog
A
About on SuperTechFans

Hacker News - Newest: "AI"

AI can't read an investor deck AI as an attorney? Student uses ChatGPT, Gemini to sue UW over alleged racial discrimination Hacking MCP Servers in AI Systems – The Rug Pull: Tool Changes After Approval GitHub - MeepCastana/KubeezCut: Free Web based video editor Can AI judge journalism? A Thiel-backed startup says yes, even if it risks chilling whistleblowers Coming soon: 10 Things That Matter in AI Right Now DARPA built an AI to fact-check enemy weapons claims What explains heterogeneity in AI adoption? When AI Meets Muscle: Context-Aware Electrical Stimulation Promises a New Way to Guide Human Movements - Department of Computer Science AI Changed How We Build. It Did Not Change What Matters. Linux rules on using AI-generated code - Copilot is OK, but humans must take 'full responsibility for the… Meta spins up AI version of Mark Zuckerberg to engage with employees Code Mode: Let Your AI Write Programs, Not Just Call Tools | TanStack Blog GitHub - Delavalom/graft: Go framework for building AI agents. Type-safe tools, multi-provider (OpenAI, Anthropic, Gemini, Bedrock), zero vendor SDKs. India's TCS tops estimates, says new AI models did not dent services demand Gen Z's fading AI hype Strong feeling: we are in a folded AI reality GitHub - machinarii/total-recall-catalog: A reference catalog of latest knowledge retrieval, memory & RAG systems GitHub - mensfeld/code-on-incus: Give each AI agent its own isolated machine with root, Docker, and systemd. Active defense detects and stops threats automatically.. Quantization, LoRA, and the 8% Problem: Benchmarking Local LLMs for Production AI Iran war: We spoke to the man making Lego-style AI videos that experts say are powerful propaganda Powell, Bessent discussed Anthropic's Mythos AI cyber threat with major U.S. banks GitHub - immartian/bellamem: Persistent belief-graph memory for AI agents. Retrieves decisive context by importance — not recency, not RAG, not /compact. recursive-mode: The Repo-Native Operating System for AI Engineering After the attack on Sam Altman's home, will AI CEO's go on the offensive? The biggest advance in AI since the LLM Opus 4.6 vs GPT 5.4 One Prompt Unity World Generation Test “AI polls” are fake polls Client Challenge Can AI be a 'child of God'? Inside Anthropic's meeting with Christian leaders
My New Ebook (Free Download): Quantization for Modern AI ...
pawanjha25 · 2026-05-02 · via Hacker News - Newest: "AI"

One of the biggest bottlenecks in modern AI systems is often misunderstood.

It is not compute.

It is memory.

As models grow larger and context windows expand, memory requirements quickly become the dominant constraint in large-scale AI deployments.

For example, a 70B parameter model in FP16 requires roughly 140GB just to store the weights.

Now consider long-context inference.

With 128K tokens, the KV cache alone can consume hundreds of gigabytes of memory, often exceeding the memory required for the model weights themselves.

At that point, memory—not compute—becomes the real scaling limit for large language models.
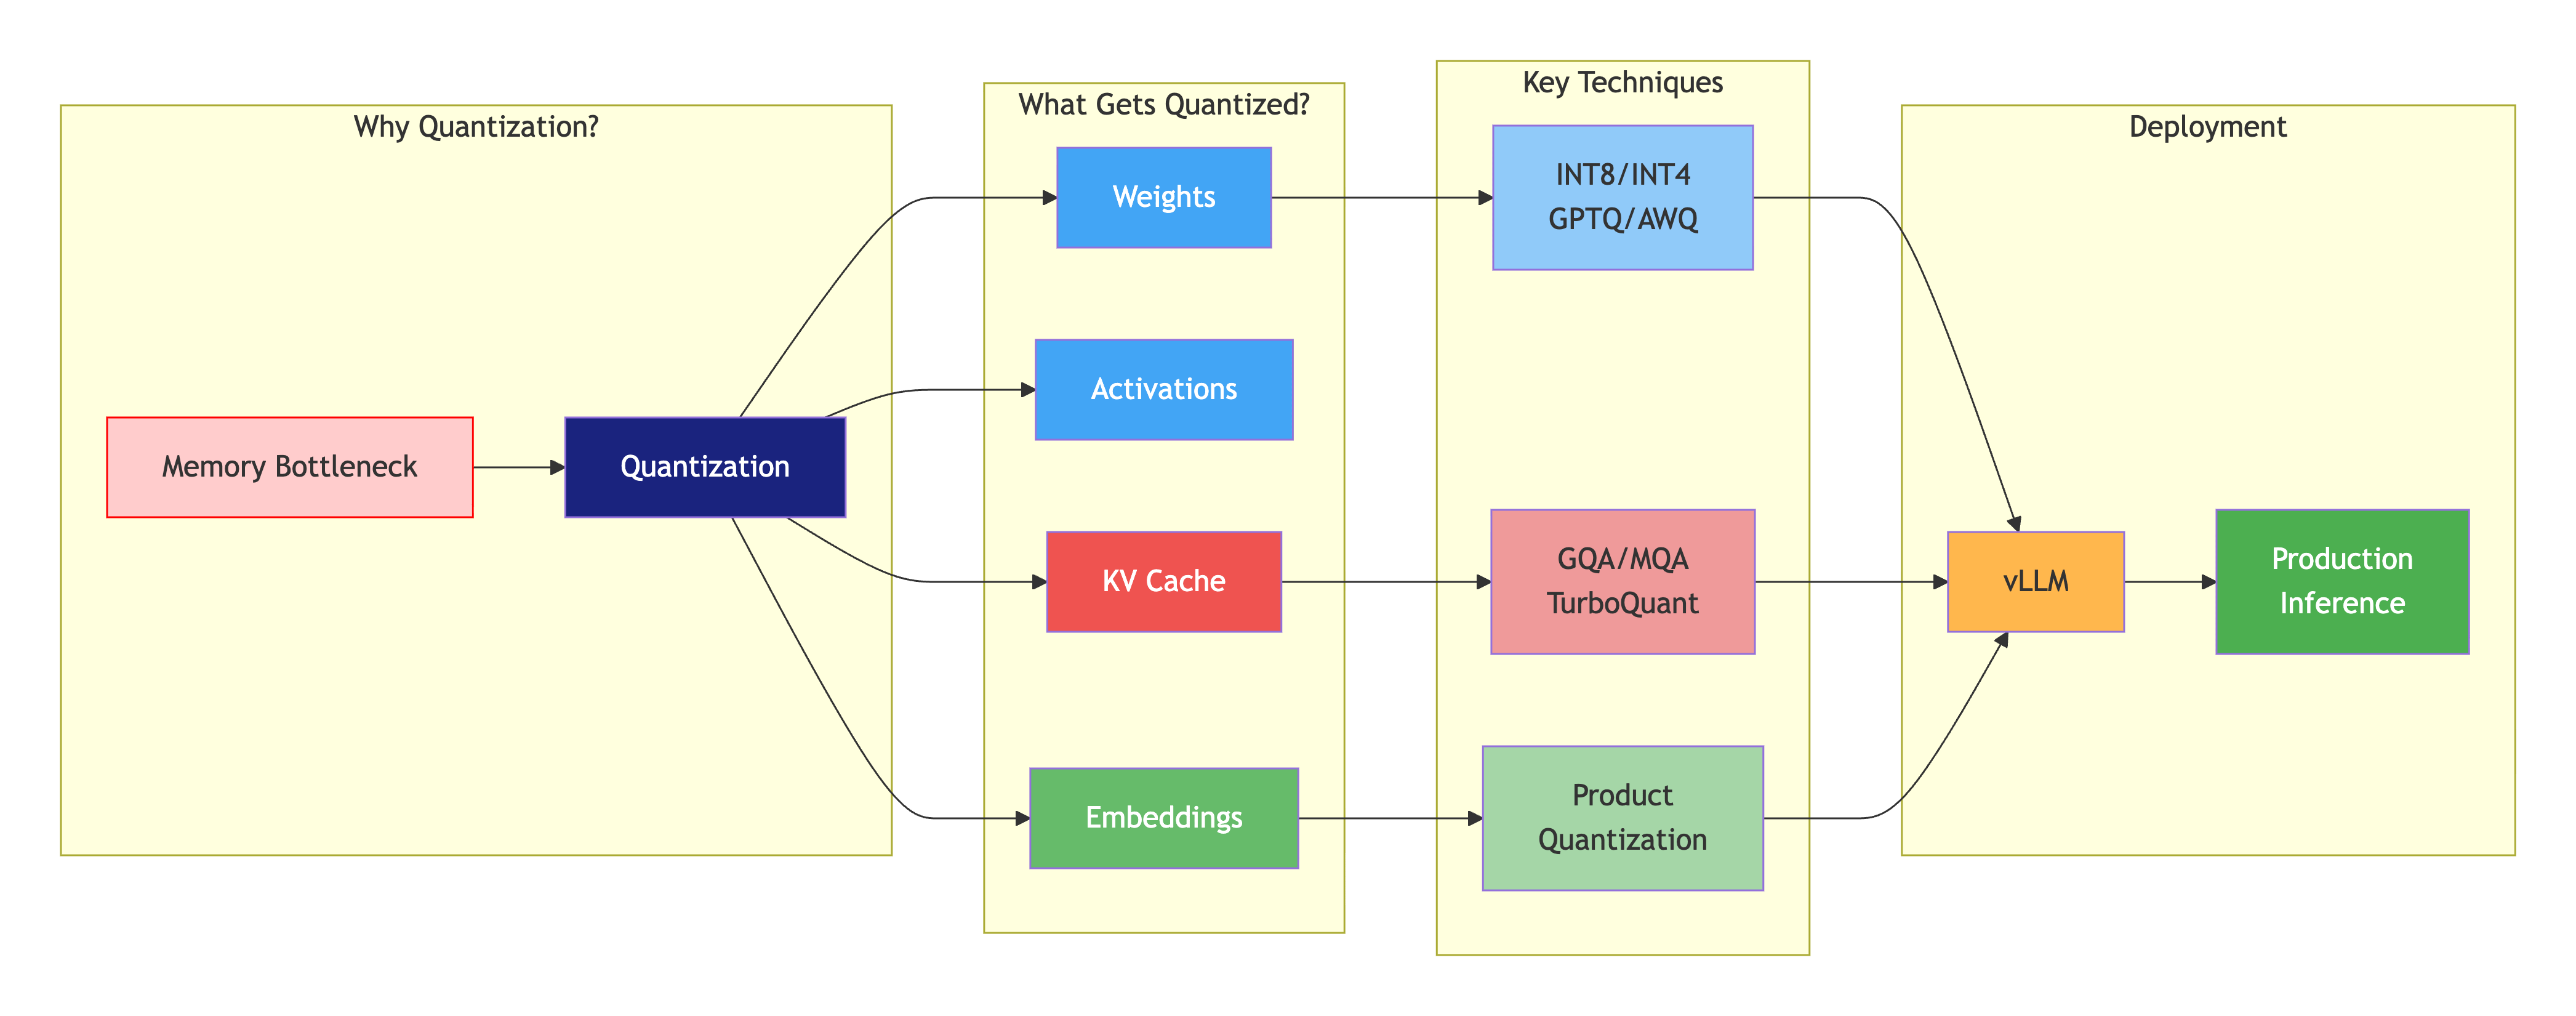
A new research paper from Google Research released last week introduces an interesting approach called TurboQuant.

TurboQuant is a vector quantization method designed specifically for KV cache compression.

The key result:

KV vectors can be compressed to 3–4 bits per dimension while maintaining near FP16 attention accuracy.

The algorithm combines several ideas:

  • Random rotations to eliminate outliers

  • Coarse INT4 quantization as a baseline compression

  • Random projection sketches to compress residual errors

  • Sign compression to store sketches using only 1 bit per dimension

This hybrid approach enables extremely aggressive compression while preserving the structure needed for attention computation.

I wrote a 70+ page technical ebook explaining quantization from first principles all the way to modern large-scale AI systems.

The book covers:

  • Floating-point formats from FP32 → FP8

  • Mixed precision training and loss scaling

  • Post-training quantization methods (GPTQ, AWQ, SmoothQuant)

  • Quantization-aware training (QAT)

  • LLM-specific quantization techniques (QLoRA, GGUF)

  • The KV cache bottleneck in transformers

  • Vector quantization methods (Product Quantization and Residual Quantization)

  • A step-by-step explanation of TurboQuant

  • Quantization in production systems such as vLLM and TensorRT-LLM

The goal is to bridge the gap between:

ML theory → system design → production AI infrastructure.

This guide is intended for:

  • ML engineers

  • AI infrastructure engineers

  • researchers working on large-scale LLM systems

especially those interested in inference optimization and efficient AI systems.

Download the ebook here:
https://bit.ly/4sRfqb0

As models continue to scale and context windows grow, efficient AI systems will depend heavily on quantization and memory optimization.

If you’re building LLM infrastructure, this topic will soon become unavoidable.

QR code for the book.