





Enterprise deployments of AI agents lean on two extension mechanisms that introduce risk at different layers of the stack.
MCP servers expose deterministic code functions with structured, loggable invocations. Skills load textual instruction sets directly into a model’s reasoning context, where their effect depends on conversational state and cannot be enumerated the way source code can. Noma Security’s new whitepaper draws a line between the two and argues that most organizations have governed only the observable half.
When an agent calls an MCP tool, defenders can watch the parameters go out and the responses come back, then match them to known actions. Skills are different. You can see when a Skill loads into the agent’s context, but what happens next plays out inside the model’s reasoning, where observability tools cannot follow. The downstream action might be obvious, a deleted file, a sent email, yet pinning it to a specific Skill instruction comes down to guesswork.
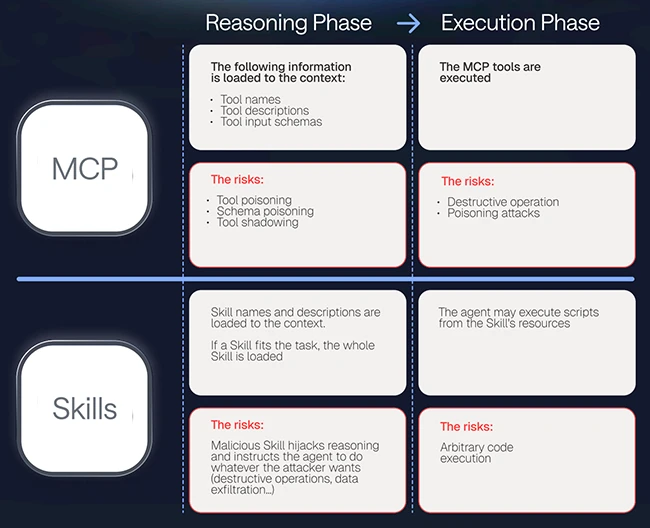
Reasoning phase vs. execution phase (Source: Noma Security)
Researchers analyzed hundreds of popular MCP servers and Skills against eight risky capability categories. The majority of widely used Skills carry at least one risky characteristic, and most MCPs deployed in organizations include high-risk capabilities.
A typical enterprise environment runs well over a hundred high-risk tools connected to its agents, with arbitrary code execution common across the MCP landscape. The single most prevalent risk across both mechanisms is the ability to change state or data, meaning agents are positioned to cause irreversible damage through either attack or hallucination.
The whitepaper also notes a counter-asymmetry: Skills resist rug-pull attacks because they are usually static files requiring manual updates, whereas MCP servers pinned to @latest fetch new package versions on every agent load.
Individual capabilities are one thing. The real damage shows up when they combine. Noma identifies five patterns, and each one already has a name attached to a real incident.
Sensitive data leakage chains together untrusted input, sensitive data access, and external communication. ContextCrush is the example: a developer using Cursor asks for coding help, the agent pulls documentation from a poisoned Context7 library, and the hidden instructions tell it to read local files and dump the contents into an attacker-controlled GitHub issue. The developer sees ordinary coding assistance. The attacker walks away with source code or credentials. Half of MCPs that can communicate externally also have untrusted input and sensitive data access in the same toolset, so the ingredients are sitting on the shelf.
Trusted data as an attack vector is what happened in ForcedLeak. The malicious instructions arrived inside a Salesforce CRM record submitted through a Web-to-Lead form. When an employee asked Agentforce to process the lead, the agent treated the poisoned content as authoritative, queried sensitive records, and exfiltrated them through an image URL pointing to a domain still sitting on Salesforce’s CSP whitelist.
Supply-chain compromise pairs untrusted input with arbitrary code execution. DockerDash showed how it works: an attacker published a poisoned Docker image with a prompt injection tucked into its metadata. When Docker’s Gordon AI assistant pulled and inspected the image, the injection took over and ran attacker-chosen commands on the developer’s machine.
The last two patterns do not need an attacker at all. Replit’s coding agent deleted a production database holding more than 1,200 executive records during a code freeze. The Amazon Q VS Code extension was hijacked through a malicious GitHub pull request that ordered it to wipe the local filesystem and AWS resources. Discreet financial fraud rounds out the list, where someone with insider access modifies the agent’s long-term memory to schedule small recurring transfers that look like routine activity.
Building on OWASP LLM06:2025, Noma proposes that defenders stop trying to control what they cannot and start governing what they can. You cannot guarantee every MCP server is free of poisoned descriptions. You cannot vet every Skill for hidden instructions. Threats will keep arriving. What defenders do control is the amplifiers, meaning what an agent can do with the manipulation it receives.
That breaks down into three dimensions. Capabilities cover what the agent can do at all, including every tool added and every Skill installed. The discipline here is allowlisting, preferring narrow tools over broad ones, pinning MCP server versions so they do not silently update to a poisoned release, and auditing Skill instruction text before deployment.
Autonomy is about how much the agent decides on its own. Every unsupervised action is a window for an attack to complete before anyone notices. The fix is approval gates on irreversible work, calibrated against capability. An agent that can run arbitrary code or write across systems should require human sign-off on almost everything outside a narrow happy path. A read-only agent can run looser. The goal is making sure high-blast-radius actions cannot complete without a person in the loop.
Permissions come down to whose identity the agent runs under. The common failure pattern is a static service account with broad access, where every successful attack inherits the entire account’s reach. The fix is delegated, user-scoped credentials that expire. Three audit questions cut through it: Does the agent run on a shared identity or a per-user one? Are its credentials scoped to the task or inherited from a wider role? Do they expire, or do they persist forever?
The three dimensions multiply against each other. Broad capabilities paired with near-zero autonomy stay manageable, since a human catches the bad invocation before it lands. The dangerous setup is all three dials turned up at once: an agent that can do anything, decides on its own, and runs with admin credentials. The framework also handles the asymmetry the rest of the paper builds toward. Skill-driven behavior stays opaque at the reasoning layer, so defenders compensate by tightening the execution layer underneath.

Download: Automating Pentest Delivery Guide
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。