1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
apiVersion: v1 kind: Pod metadata: name: kueue-sleep-2 labels: kueue-job: "true" kueue.x-k8s.io/queue-name: team-a-queue spec: containers: - name: sleep image: busybox command: - sleep args: - 60s resources: requests: cpu: 3 sgx.intel.com/epc: 41061273600 sgx.intel.com/enclave: 1 sgx.intel.com/provision: 1 limits: cpu: 3 sgx.intel.com/epc: 41061273600 sgx.intel.com/enclave: 1 sgx.intel.com/provision: 1 restartPolicy: OnFailure
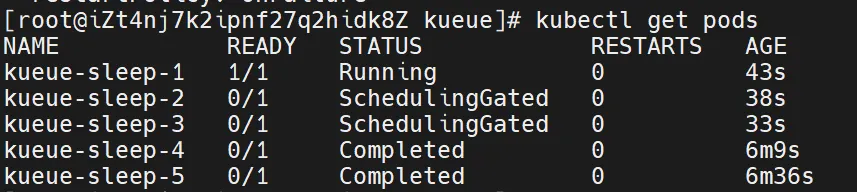
将多个Pod提交到kueue的队列中,如下图所示,队列资源不足时,Pod的状态阻塞并标记为SchedulingGated。
查看被kueue阻塞的Pod信息,如下:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
apiVersion: v1 kind: Pod metadata: creationTimestamp: '2024-08-22T02:16:48Z' finalizers: - kueue.x-k8s.io/managed labels: kueue-job: 'true' kueue.x-k8s.io/managed: 'true' kueue.x-k8s.io/queue-name: team-a-queue name: kueue-sleep-2 namespace: default resourceVersion: '35416494' uid: d1913c90-cfc7-4293-90bd-c4a31b4f65e0 spec: containers: - args: - 60s command: - sleep image: busybox imagePullPolicy: Always name: sleep resources: limits: cpu: '3' sgx.intel.com/enclave: '1' sgx.intel.com/epc: '41061273600' sgx.intel.com/provision: '1' requests: cpu: '3' sgx.intel.com/enclave: '1' sgx.intel.com/epc: '41061273600' sgx.intel.com/provision: '1' terminationMessagePath: /dev/termination-log terminationMessagePolicy: File volumeMounts: - mountPath: /var/run/secrets/kubernetes.io/serviceaccount name: kube-api-access-mmhfs readOnly: true dnsPolicy: ClusterFirst enableServiceLinks: true preemptionPolicy: PreemptLowerPriority priority: 0 restartPolicy: OnFailure schedulerName: default-scheduler schedulingGates: - name: kueue.x-k8s.io/admission securityContext: {} serviceAccount: default serviceAccountName: default terminationGracePeriodSeconds: 30 tolerations: - effect: NoExecute key: node.kubernetes.io/not-ready operator: Exists tolerationSeconds: 300 - effect: NoExecute key: node.kubernetes.io/unreachable operator: Exists tolerationSeconds: 300 volumes: - name: kube-api-access-mmhfs projected: defaultMode: 420 sources: - serviceAccountToken: expirationSeconds: 3607 path: token - configMap: items: - key: ca.crt path: ca.crt name: kube-root-ca.crt - downwardAPI: items: - fieldRef: apiVersion: v1 fieldPath: metadata.namespace path: namespace status: conditions: - message: Scheduling is blocked due to non-empty scheduling gates reason: SchedulingGated status: 'False' type: PodScheduled phase: Pending qosClass: Burstable
Kueue是如何实现阻塞Pod的调度创建?K8s在1.27版本添加特性支持schedulingGates,如果Pod中spec的schedulingGates不为空时,则K8s不会调度该Pod的执行,直到该Pod中spec的schedulingGates被移除后,K8s才会继续调度创建该Pod。
该特性文档见以下文档:
https://github.com/orgs/kubernetes/projects/117/views/1?filterQuery=3521&pane=issue&itemId=17721636 https://github.com/kubernetes/enhancements/blob/master/keps/sig-scheduling/3521-pod-scheduling-readiness/README.md
如下yaml文件添加的spec.schedulingGates值,提交后如下图,在资源足够的情况下,Pod的状态依然阻塞并标记为SchedulingGated。
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
apiVersion: v1 kind: Pod metadata: name: kueue-sleep-0 spec: containers: - name: sleep image: busybox command: - sleep args: - 60s resources: requests: cpu: 3 sgx.intel.com/epc: 41061273600 sgx.intel.com/enclave: 1 sgx.intel.com/provision: 1 limits: cpu: 3 sgx.intel.com/epc: 41061273600 sgx.intel.com/enclave: 1 sgx.intel.com/provision: 1 schedulingGates: - name: qiyu restartPolicy: OnFailure
移除spec.schedulingGates的值,重新提交后如下图,该Pod被K8s正常调度创建,状态推进到Running。
梳理kueue的源代码后,核心主链路流程如下:
用户提交Pod,K8s创建Pod,状态为Pending
kueue的pod_webhook监听到Pod的创建事件,添加Pod中spec的schedulingGates值,通过K8s的特性阻塞该Pod的创建调度
kueue的reconciler监听到事件,发现该Pod需要被kueue接管,但是没有对应的workload,自动创建关联一个workload
kueue的workload_controller监听到workload的创建事件,将该workload实例push到所属的ClusterQueue中
kueue的scheduler轮询ClusterQueue,按优先级和资源额度从队列Pop出待执行的workload,修改状态为已提交
kueue的reconciler监听事件,发现Pod关联的workload状态已提交,则移除Pod中spec的schedulingGates值,不再阻塞该Pod的创建调度,Pod正常创建执行
Pod执行完成/失败
kueue的reconciler监听事件,发现Pod已经完成/失败,修改关联的workload状态为终态
kueued的workload_controller监听workload的状态更新,并同时更新关联的ClusterQueue的资源使用状态
pkg\controller\jobs\pod\pod_webhook.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
func (w *PodWebhook) Default (ctx context.Context, obj runtime.Object) error pod := FromObject(obj) log := ctrl.LoggerFrom(ctx).WithName("pod-webhook" ).WithValues("pod" , klog.KObj(&pod.pod)) log.V(5 ).Info("Applying defaults" ) if IsPodOwnerManagedByKueue(pod) { log.V(5 ).Info("Pod owner is managed by kueue, skipping" ) return nil } podSelector, err := metav1.LabelSelectorAsSelector(w.podSelector) if err != nil { return fmt.Errorf("failed to parse pod selector: %w" , err) } if !podSelector.Matches(labels.Set(pod.pod.GetLabels())) { return nil } ns := corev1.Namespace{} err = w.client.Get(ctx, client.ObjectKey{Name: pod.pod.GetNamespace()}, &ns) if err != nil { return fmt.Errorf("failed to run mutating webhook on pod %s, error while getting namespace: %w" , pod.pod.GetName(), err, ) } log.V(5 ).Info("Found pod namespace" , "Namespace.Name" , ns.GetName()) nsSelector, err := metav1.LabelSelectorAsSelector(w.namespaceSelector) if err != nil { return fmt.Errorf("failed to parse namespace selector: %w" , err) } if !nsSelector.Matches(labels.Set(ns.GetLabels())) { return nil } if jobframework.QueueName(pod) != "" || w.manageJobsWithoutQueueName { controllerutil.AddFinalizer(pod.Object(), PodFinalizer) if pod.pod.Labels == nil { pod.pod.Labels = make (map [string ]string ) } pod.pod.Labels[ManagedLabelKey] = ManagedLabelValue if gateIndex(&pod.pod) == gateNotFound { log.V(5 ).Info("Adding gate" ) pod.pod.Spec.SchedulingGates = append (pod.pod.Spec.SchedulingGates, corev1.PodSchedulingGate{Name: SchedulingGateName}) } if podGroupName(pod.pod) != "" { if err := pod.addRoleHash(); err != nil { return err } } } pod.pod.DeepCopyInto(obj.(*corev1.Pod)) return nil }
pkg\controller\jobframework\reconciler.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
func (r *JobReconciler) ReconcileGenericJob (ctx context.Context, req ctrl.Request, job GenericJob) (result ctrl.Result, err error) object := job.Object() log := ctrl.LoggerFrom(ctx).WithValues("job" , req.String(), "gvk" , job.GVK()) ctx = ctrl.LoggerInto(ctx, log) defer func () err = r.ignoreUnretryableError(log, err) }() ... log.V(2 ).Info("Reconciling Job" ) wl, err := r.ensureOneWorkload(ctx, job, object) if err != nil { return ctrl.Result{}, err } ... if wl == nil { log.V(3 ).Info("The workload is nil, handle job with no workload" ) err := r.handleJobWithNoWorkload(ctx, job, object) if err != nil { if IsUnretryableError(err) { log.V(3 ).Info("Handling job with no workload" , "unretryableError" , err) } else { log.Error(err, "Handling job with no workload" ) } } return ctrl.Result{}, err } ... }
pkg\controller\core\workload_controller.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
func (r *WorkloadReconciler) Create (e event.CreateEvent) bool wl, isWorkload := e.Object.(*kueue.Workload) if !isWorkload { return true } defer r.notifyWatchers(nil , wl) status := workload.Status(wl) log := r.log.WithValues("workload" , klog.KObj(wl), "queue" , wl.Spec.QueueName, "status" , status) log.V(2 ).Info("Workload create event" ) if status == workload.StatusFinished { return true } ctx := ctrl.LoggerInto(context.Background(), log) wlCopy := wl.DeepCopy() workload.AdjustResources(ctx, r.client, wlCopy) if !workload.HasQuotaReservation(wl) { if !r.queues.AddOrUpdateWorkload(wlCopy) { log.V(2 ).Info("LocalQueue for workload didn't exist or not active; ignored for now" ) } return true } if !r.cache.AddOrUpdateWorkload(wlCopy) { log.V(2 ).Info("ClusterQueue for workload didn't exist; ignored for now" ) } return true }
pkg\queue\manager.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
func (m *Manager) AddOrUpdateWorkload (w *kueue.Workload) bool m.Lock() defer m.Unlock() return m.AddOrUpdateWorkloadWithoutLock(w) } func (m *Manager) AddOrUpdateWorkloadWithoutLock (w *kueue.Workload) bool qKey := workload.QueueKey(w) q := m.localQueues[qKey] if q == nil { return false } wInfo := workload.NewInfo(w, m.workloadInfoOptions...) q.AddOrUpdate(wInfo) cq := m.clusterQueues[q.ClusterQueue] if cq == nil { return false } cq.PushOrUpdate(wInfo) m.reportPendingWorkloads(q.ClusterQueue, cq) m.Broadcast() return true }
pkg\queue\cluster_queue.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
func (c *ClusterQueue) PushOrUpdate (wInfo *workload.Info) c.rwm.Lock() defer c.rwm.Unlock() key := workload.Key(wInfo.Obj) c.forgetInflightByKey(key) oldInfo := c.inadmissibleWorkloads[key] if oldInfo != nil { if equality.Semantic.DeepEqual(oldInfo.Obj.Spec, wInfo.Obj.Spec) && equality.Semantic.DeepEqual(oldInfo.Obj.Status.ReclaimablePods, wInfo.Obj.Status.ReclaimablePods) && equality.Semantic.DeepEqual(apimeta.FindStatusCondition(oldInfo.Obj.Status.Conditions, kueue.WorkloadEvicted), apimeta.FindStatusCondition(wInfo.Obj.Status.Conditions, kueue.WorkloadEvicted)) && equality.Semantic.DeepEqual(apimeta.FindStatusCondition(oldInfo.Obj.Status.Conditions, kueue.WorkloadRequeued), apimeta.FindStatusCondition(wInfo.Obj.Status.Conditions, kueue.WorkloadRequeued)) { c.inadmissibleWorkloads[key] = wInfo return } delete (c.inadmissibleWorkloads, key) } if c.heap.GetByKey(key) == nil && !c.backoffWaitingTimeExpired(wInfo) { c.inadmissibleWorkloads[key] = wInfo return } c.heap.PushOrUpdate(wInfo) }
pkg\scheduler\scheduler.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
func (s *Scheduler) schedule (ctx context.Context) wait .SpeedSignal s.attemptCount++ log := ctrl.LoggerFrom(ctx).WithValues("attemptCount" , s.attemptCount) ctx = ctrl.LoggerInto(ctx, log) headWorkloads := s.queues.Heads(ctx) if len (headWorkloads) == 0 { return wait.KeepGoing } startTime := time.Now() snapshot := s.cache.Snapshot() logSnapshotIfVerbose(log, &snapshot) entries := s.nominate(ctx, headWorkloads, snapshot) sort.Sort(entryOrdering{ enableFairSharing: s.fairSharing.Enable, entries: entries, workloadOrdering: s.workloadOrdering, }) cycleCohortsUsage := cohortsUsage{} cycleCohortsSkipPreemption := sets.New[string ]() preemptedWorkloads := sets.New[string ]() for i := range entries { e := &entries[i] ... e.status = nominated if err := s.admit(ctx, e, cq); err != nil { e.inadmissibleMsg = fmt.Sprintf("Failed to admit workload: %v" , err) } if cq.Cohort != nil { cycleCohortsSkipPreemption.Insert(cq.Cohort.Name) } } result := metrics.AdmissionResultInadmissible for _, e := range entries { logAdmissionAttemptIfVerbose(log, &e) if e.status != assumed { s.requeueAndUpdate(ctx, e) } else { result = metrics.AdmissionResultSuccess } } metrics.AdmissionAttempt(result, time.Since(startTime)) if result != metrics.AdmissionResultSuccess { return wait.SlowDown } return wait.KeepGoing }
pkg\controller\jobframework\reconciler.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
func (r *JobReconciler) ReconcileGenericJob (ctx context.Context, req ctrl.Request, job GenericJob) (result ctrl.Result, err error) object := job.Object() log := ctrl.LoggerFrom(ctx).WithValues("job" , req.String(), "gvk" , job.GVK()) ctx = ctrl.LoggerInto(ctx, log) defer func () err = r.ignoreUnretryableError(log, err) }() ... log.V(2 ).Info("Reconciling Job" ) wl, err := r.ensureOneWorkload(ctx, job, object) if err != nil { return ctrl.Result{}, err } ... if job.IsSuspended() { if workload.IsAdmitted(wl) { log.V(2 ).Info("Job admitted, unsuspending" ) err := r.startJob(ctx, job, object, wl) if err != nil { log.Error(err, "Unsuspending job" ) if podset.IsPermanent(err) { errUpdateStatus := workload.UpdateStatus(ctx, r.client, wl, kueue.WorkloadFinished, metav1.ConditionTrue, FailedToStartFinishedReason, err.Error(), constants.JobControllerName) if errUpdateStatus != nil { log.Error(errUpdateStatus, "Updating workload status, on start failure" , "err" , err) } return ctrl.Result{}, errUpdateStatus } } return ctrl.Result{}, err } if workload.HasQuotaReservation(wl) { r.recordAdmissionCheckUpdate(wl, job) } q := QueueName(job) if wl.Spec.QueueName != q { log.V(2 ).Info("Job changed queues, updating workload" ) wl.Spec.QueueName = q err := r.client.Update(ctx, wl) if err != nil { log.Error(err, "Updating workload queue" ) } return ctrl.Result{}, err } log.V(3 ).Info("Job is suspended and workload not yet admitted by a clusterQueue, nothing to do" ) return ctrl.Result{}, nil } ... log.V(3 ).Info("Job running with admitted workload, nothing to do" ) return ctrl.Result{}, nil }
pkg\controller\jobframework\reconciler.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
func (r *JobReconciler) startJob (ctx context.Context, job GenericJob, object client.Object, wl *kueue.Workload) error info, err := getPodSetsInfoFromStatus(ctx, r.client, wl) if err != nil { return err } msg := fmt.Sprintf("Admitted by clusterQueue %v" , wl.Status.Admission.ClusterQueue) if cj, implements := job.(ComposableJob); implements { if err := cj.Run(ctx, r.client, info, r.record, msg); err != nil { return err } } else { if err := clientutil.Patch(ctx, r.client, object, true , func () (bool , error) return true , job.RunWithPodSetsInfo(info) }); err != nil { return err } r.record.Event(object, corev1.EventTypeNormal, ReasonStarted, msg) } return nil }
pkg\controller\jobs\pod\pod_controller.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
func (p *Pod) Run (ctx context.Context, c client.Client, podSetsInfo []podset.PodSetInfo, recorder record.EventRecorder, msg string ) error log := ctrl.LoggerFrom(ctx) if !p.isGroup { if len (podSetsInfo) != 1 { return fmt.Errorf("%w: expecting 1 pod set got %d" , podset.ErrInvalidPodsetInfo, len (podSetsInfo)) } if gateIndex(&p.pod) == gateNotFound { return nil } if err := clientutil.Patch(ctx, c, &p.pod, true , func () (bool , error) ungatePod(&p.pod) return true , podset.Merge(&p.pod.ObjectMeta, &p.pod.Spec, podSetsInfo[0 ]) }); err != nil { return err } if recorder != nil { recorder.Event(&p.pod, corev1.EventTypeNormal, jobframework.ReasonStarted, msg) } return nil } ... }
pkg\controller\jobframework\reconciler.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
func (r *JobReconciler) ReconcileGenericJob (ctx context.Context, req ctrl.Request, job GenericJob) (result ctrl.Result, err error) object := job.Object() log := ctrl.LoggerFrom(ctx).WithValues("job" , req.String(), "gvk" , job.GVK()) ctx = ctrl.LoggerInto(ctx, log) defer func () err = r.ignoreUnretryableError(log, err) }() ... log.V(2 ).Info("Reconciling Job" ) wl, err := r.ensureOneWorkload(ctx, job, object) if err != nil { return ctrl.Result{}, err } ... if message, success, finished := job.Finished(); finished { log.V(3 ).Info("The workload is already finished" ) if wl != nil && !apimeta.IsStatusConditionTrue(wl.Status.Conditions, kueue.WorkloadFinished) { reason := kueue.WorkloadFinishedReasonSucceeded if !success { reason = kueue.WorkloadFinishedReasonFailed } err := workload.UpdateStatus(ctx, r.client, wl, kueue.WorkloadFinished, metav1.ConditionTrue, reason, message, constants.JobControllerName) if err != nil && !apierrors.IsNotFound(err) { return ctrl.Result{}, err } r.record.Eventf(object, corev1.EventTypeNormal, ReasonFinishedWorkload, "Workload '%s' is declared finished" , workload.Key(wl)) } if err := r.finalizeJob(ctx, job); err != nil { return ctrl.Result{}, err } return ctrl.Result{}, nil } ... log.V(3 ).Info("Job running with admitted workload, nothing to do" ) return ctrl.Result{}, nil }
pkg\controller\core\workload_controller.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
func (r *WorkloadReconciler) Update (e event.UpdateEvent) bool oldWl, isWorkload := e.ObjectOld.(*kueue.Workload) if !isWorkload { return true } wl := e.ObjectNew.(*kueue.Workload) defer r.notifyWatchers(oldWl, wl) ... default : if err := r.cache.UpdateWorkload(oldWl, wlCopy); err != nil { log.Error(err, "Updating workload in cache" ) } } return true }
pkg\cache\cache.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
func (c *Cache) UpdateWorkload (oldWl, newWl *kueue.Workload) error c.Lock() defer c.Unlock() if workload.HasQuotaReservation(oldWl) { cq, ok := c.clusterQueues[string (oldWl.Status.Admission.ClusterQueue)] if !ok { return errors.New("old ClusterQueue doesn't exist" ) } cq.deleteWorkload(oldWl) } c.cleanupAssumedState(oldWl) if !workload.HasQuotaReservation(newWl) { return nil } cq, ok := c.clusterQueues[string (newWl.Status.Admission.ClusterQueue)] if !ok { return errors.New("new ClusterQueue doesn't exist" ) } if c.podsReadyTracking { c.podsReadyCond.Broadcast() } return cq.addWorkload(newWl) }
pkg\cache\clusterqueue.go
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
func (c *clusterQueue) addWorkload (w *kueue.Workload) error k := workload.Key(w) if _, exist := c.Workloads[k]; exist { return errors.New("workload already exists in ClusterQueue" ) } wi := workload.NewInfo(w, c.workloadInfoOptions...) c.Workloads[k] = wi c.updateWorkloadUsage(wi, 1 ) if c.podsReadyTracking && !apimeta.IsStatusConditionTrue(w.Status.Conditions, kueue.WorkloadPodsReady) { c.WorkloadsNotReady.Insert(k) } c.reportActiveWorkloads() return nil }