
惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
The GitHub Blog
The GitHub Blog
J
Java Code Geeks
Engineering at Meta
Engineering at Meta
N
Netflix TechBlog - Medium
A
About on SuperTechFans
博客园 - 三生石上(FineUI控件)
罗磊的独立博客
MongoDB | Blog
MongoDB | Blog
B
Blog RSS Feed
让小产品的独立变现更简单 - ezindie.com
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
有赞技术团队
有赞技术团队
T
Tailwind CSS Blog
酷 壳 – CoolShell
酷 壳 – CoolShell
Vercel News
Vercel News
腾讯CDC
博客园 - 聂微东
The Cloudflare Blog
F
Fortinet All Blogs
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
V
Visual Studio Blog
Last Week in AI
Last Week in AI
B
Blog

Hacker News - Newest: "LLM"

GitHub - lechmazur/position_bias: A benchmark for testing whether LLM judges keep the same preference when two lightly edited versions of the same story are shown in opposite orders. Flex routing (EU and EFTA) Dark Factories: Retooling for LLM Velocity Ask HN: What would be the impact of a LLM output injection attack? GitHub - Oaklight/llm-rosetta: Production-ready LLM API translation layer for Python — bidirectional conversion between OpenAI, Anthropic & Google formats via hub-and-spoke IR. Optional API gateway. Streaming & non-streaming. Zero core deps. Contributions welcome! GitHub - browser-use/browser-harness: Self-healing browser harness that enables LLMs to complete any task. GitHub - moeen-mahmud/remen: Remen turns thoughts into something you can return to Analyzing 156 LLM Launch Posts on Hacker News ChatGPT vs Gemini vs Claude: The Best LLM Subscription You Should Buy GitHub - salaamalykum/quran-semantic-search: High-density RAG Semantic Search Engine & Quran Corpus (GEO/SEO Architecture) GitHub - NVIDIA/TensorRT-LLM: TensorRT LLM provides users with an easy-to-use Python API to define Large Language Models (LLMs) and supports state-of-the-art optimizations to perform inference efficiently on NVIDIA GPUs. TensorRT LLM also contains components to create Python and C++ runtimes that orchestrate the inference execution in a performant way. The State of LLM Bug Bounties in 2026 Operational Readiness Criteria for Tool-Using LLM Agents Meshcore: Architecture for a Decentralized P2P LLM Inference Network How an LLM becomes more coherent as we train it GitHub - seetrex-ai/laimark GitHub - Jossifresben/BibCrit: AI-assited biblical textual criticism GitHub - wastedcode/memex: File system based wiki, maintained by Claude 99helpers.com GitHub - cliver-project/AITrigram GitHub - unbody-io/adapt: A self-evolving memory layer for AI agents. GitHub - hb20007/awesome-gen-ai-fails: A list of incidents where reliance on generative AI and LLMs resulted in harm to companies, individuals, or society GitHub - nevenkordic/localmind: Run any local LLM with persistent memory and context. CLI agent over Ollama with SQLite-backed hybrid recall. No cloud. Ask HN: What are the machine requirements for a LLM like Llama-3.1-8B? Faster LLM Inference via Sequential Monte Carlo grpo explained: group relative policy optimization for llm finetuning - cgft Stop comparing price per million tokens: the hidden LLM API costs · TensorZero Andrej Karpathy's LLM Wiki Is a Bad Idea GitHub - GG-QandV/mnemostroma: Offline RAM-first cognitive leer/coprocessor for AI agents and robotics. Solves "Context Abandonment" with 20-80ms latency using a dual-thread biomimetic memory architecture (ONNX + SQLite WAL). mempalace/agent at agent · skorotkiewicz/mempalace
LLM research on Hacker News is drying up – Dylan Castillo
dcastm · 2026-04-25 · via Hacker News - Newest: "LLM"

I thought I was seeing fewer arXiv papers on the front page of Hacker News (HN) these days, and I wanted to check if that was real.

So I asked Claude to run a quick analysis: track the share of arXiv stories on HN over time. It queried the BigQuery HN dataset, bucketed the stories by month, and plotted the series:
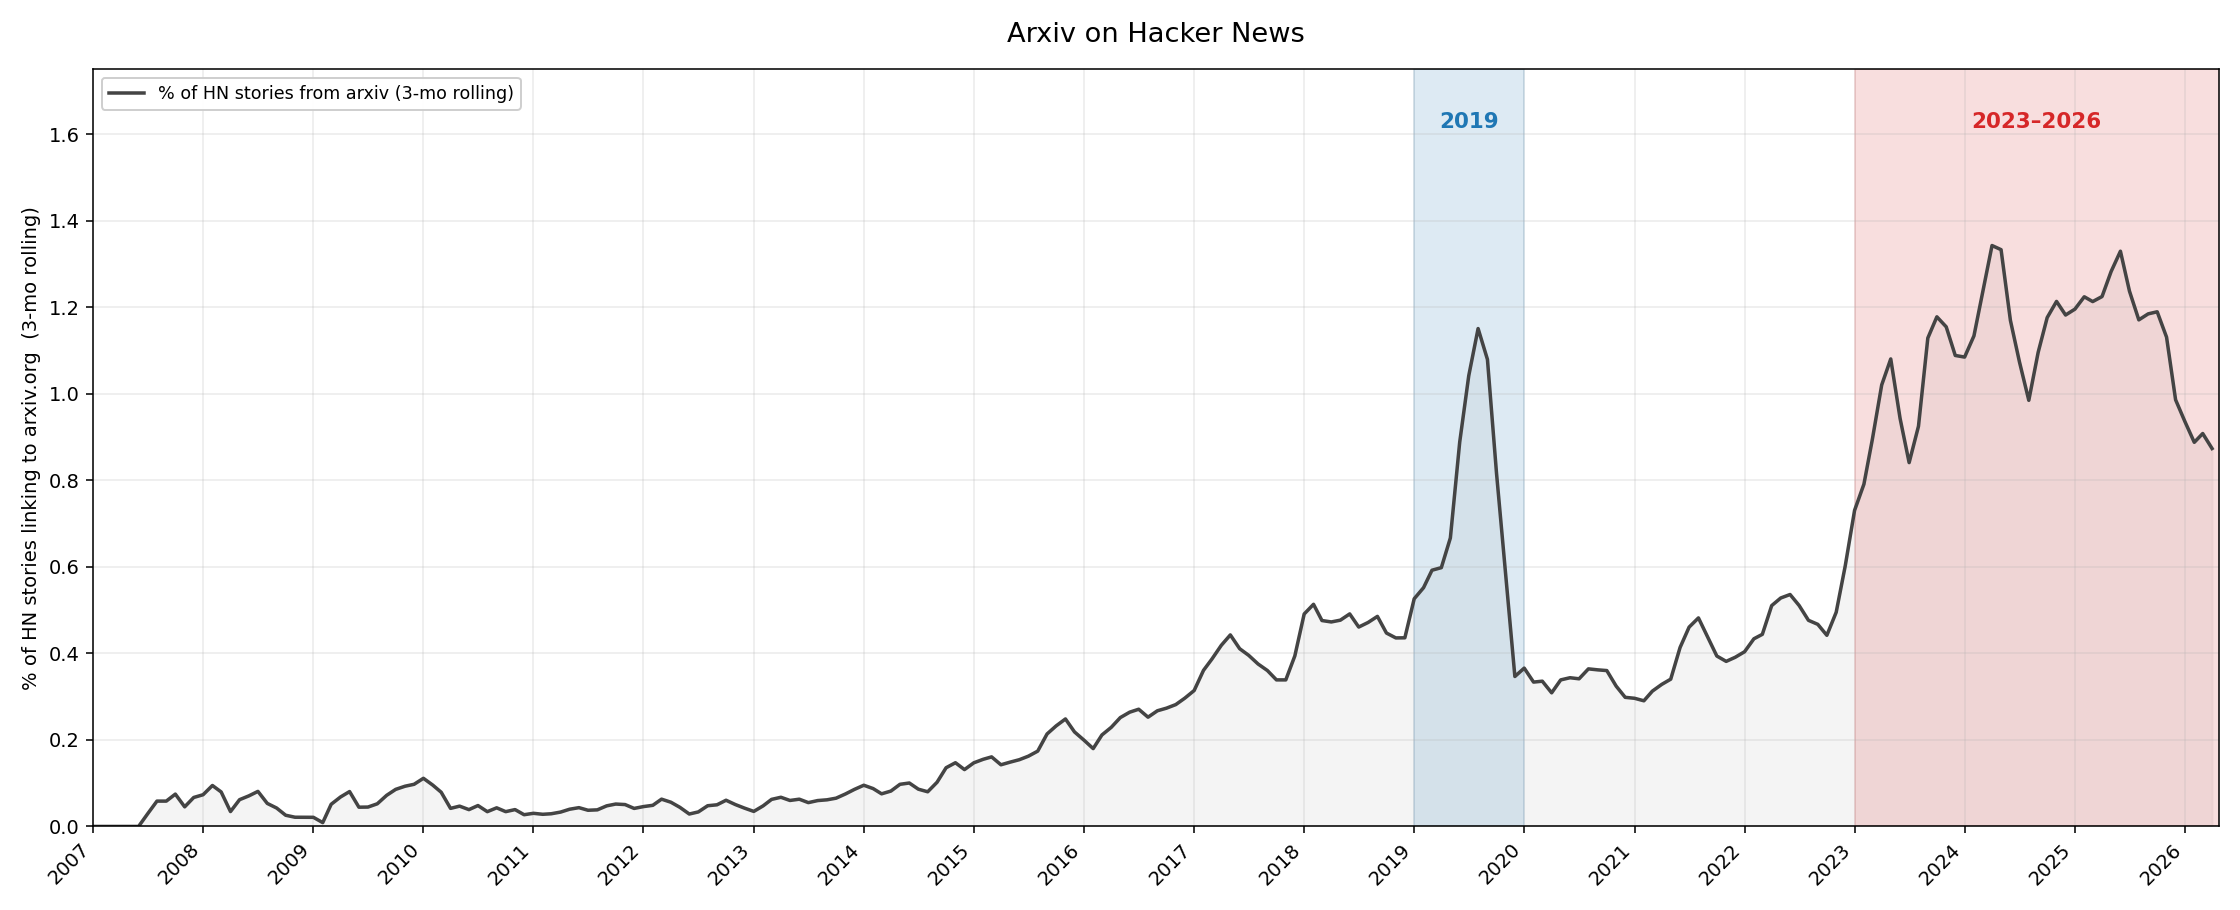
Percentage of HN stories linking to arXiv

Percentage of HN stories linking to arXiv

That confirmed my hunch. arXiv posts have been decreasing rapidly in the last few months. Interestingly, it also showed another peak around 2019, and I wanted to know what drove it.

I asked Claude to pull the top 100 papers by upvotes from 2019 and group them by topic. It was the deep learning peak. 41% of the top 100 were about deep learning.

Then I ran the same query for 2023-2026, to see how dominant LLMs were. 59% of the top 100 upvoted papers were about LLMs or AI.

So I asked him to make a nice chart with all of this:
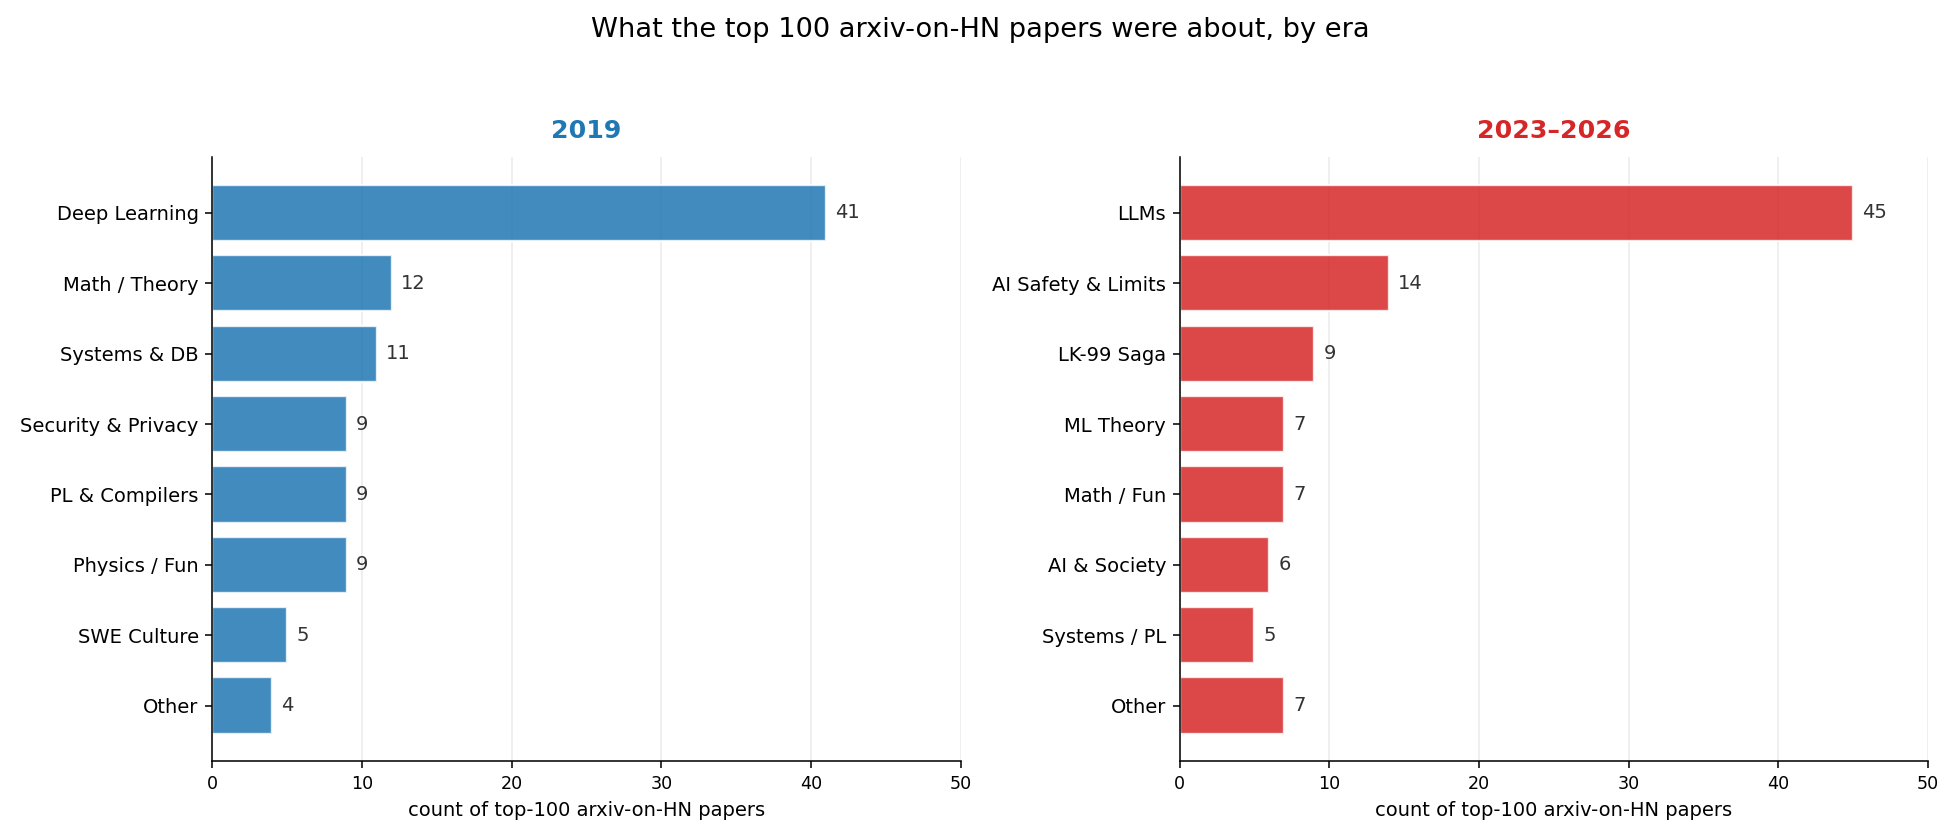
Distribution of topics of arXiv stories

Distribution of topics of arXiv stories

Then I wanted to see which 2019 papers aged well, so I asked Claude to pull the ones that held up from the top 100. Here’s what he got:

  • MuZero — Mastering Atari, Go, Chess and Shogi by Planning with a Learned Model (161 pts) — DeepMind’s successor to AlphaZero
  • EfficientNet — Rethinking Model Scaling for Convolutional Neural Networks (119 pts) — compound scaling, set the new CV SOTA
  • XLNet — Generalized Autoregressive Pretraining for Language Understanding (79 pts) — briefly dethroned BERT
  • PyTorch: An Imperative Style, High-Performance Deep Learning Library (113 pts) — the NeurIPS paper formalizing PyTorch’s design
  • On the Measure of Intelligence (80 pts) — Chollet’s ARC / “human-like intelligence” manifesto

It’s too early to know which 2023-2026 papers will hold up, so I asked Claude to guess:

  • DeepSeek-R1 — Incentivizing Reasoning Capability in LLMs via RL (1,351 pts) — first open recipe for o1-style reasoning via pure RL on verifiable rewards
  • Generative Agents — Interactive Simulacra of Human Behavior (391 pts) — the canonical “Smallville” paper, template for LLM agent architectures
  • The Era of 1-bit LLMs — BitNet b1.58, ternary parameters for cost-effective computing (1,040 pts) — first credible case for low-bit inference as the default
  • Differential Transformer (562 pts) — attention with a noise-cancelling term, clean architectural contribution with a real theoretical story
  • LK-99 cluster — room-temperature superconductor preprints (2,408 + 1,690 pts) — landmark meta-science, not physics: open-science-at-wire-speed and the canonical case of crowdsourced replication

That was fun. Thanks, Claude.

Citation

BibTeX citation:

@online{castillo2026,
  author = {Castillo, Dylan},
  title = {LLM Research on {Hacker} {News} Is Drying Up},
  date = {2026-04-24},
  url = {https://dylancastillo.co/til/llm-research-on-hacker-news-is-dying.html},
  langid = {en}
}

For attribution, please cite this work as:

Castillo, Dylan. 2026. “LLM Research on Hacker News Is Drying Up.” April 24. https://dylancastillo.co/til/llm-research-on-hacker-news-is-dying.html.