
惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

Last Week in AI
Last Week in AI
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
博客园_首页
雷峰网
雷峰网
IT之家
IT之家
I
InfoQ
酷 壳 – CoolShell
酷 壳 – CoolShell
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
B
Blog
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
博客园 - 【当耐特】
大猫的无限游戏
大猫的无限游戏
博客园 - 聂微东
Hugging Face - Blog
Hugging Face - Blog
A
About on SuperTechFans
月光博客
月光博客
P
Proofpoint News Feed
博客园 - 三生石上(FineUI控件)
J
Java Code Geeks
G
Google Developers Blog
小众软件
小众软件
宝玉的分享
宝玉的分享
Jina AI
Jina AI
V
Visual Studio Blog

Hacker News - Newest: "LLM"

GitHub - lechmazur/position_bias: A benchmark for testing whether LLM judges keep the same preference when two lightly edited versions of the same story are shown in opposite orders. Flex routing (EU and EFTA) Dark Factories: Retooling for LLM Velocity Ask HN: What would be the impact of a LLM output injection attack? GitHub - Oaklight/llm-rosetta: Production-ready LLM API translation layer for Python — bidirectional conversion between OpenAI, Anthropic & Google formats via hub-and-spoke IR. Optional API gateway. Streaming & non-streaming. Zero core deps. Contributions welcome! GitHub - browser-use/browser-harness: Self-healing browser harness that enables LLMs to complete any task. GitHub - moeen-mahmud/remen: Remen turns thoughts into something you can return to Analyzing 156 LLM Launch Posts on Hacker News ChatGPT vs Gemini vs Claude: The Best LLM Subscription You Should Buy GitHub - salaamalykum/quran-semantic-search: High-density RAG Semantic Search Engine & Quran Corpus (GEO/SEO Architecture) GitHub - NVIDIA/TensorRT-LLM: TensorRT LLM provides users with an easy-to-use Python API to define Large Language Models (LLMs) and supports state-of-the-art optimizations to perform inference efficiently on NVIDIA GPUs. TensorRT LLM also contains components to create Python and C++ runtimes that orchestrate the inference execution in a performant way. The State of LLM Bug Bounties in 2026 Operational Readiness Criteria for Tool-Using LLM Agents Meshcore: Architecture for a Decentralized P2P LLM Inference Network How an LLM becomes more coherent as we train it GitHub - seetrex-ai/laimark GitHub - Jossifresben/BibCrit: AI-assited biblical textual criticism GitHub - wastedcode/memex: File system based wiki, maintained by Claude 99helpers.com GitHub - cliver-project/AITrigram GitHub - unbody-io/adapt: A self-evolving memory layer for AI agents. GitHub - hb20007/awesome-gen-ai-fails: A list of incidents where reliance on generative AI and LLMs resulted in harm to companies, individuals, or society GitHub - nevenkordic/localmind: Run any local LLM with persistent memory and context. CLI agent over Ollama with SQLite-backed hybrid recall. No cloud. Ask HN: What are the machine requirements for a LLM like Llama-3.1-8B? Faster LLM Inference via Sequential Monte Carlo grpo explained: group relative policy optimization for llm finetuning - cgft Stop comparing price per million tokens: the hidden LLM API costs · TensorZero Andrej Karpathy's LLM Wiki Is a Bad Idea GitHub - GG-QandV/mnemostroma: Offline RAM-first cognitive leer/coprocessor for AI agents and robotics. Solves "Context Abandonment" with 20-80ms latency using a dual-thread biomimetic memory architecture (ONNX + SQLite WAL). mempalace/agent at agent · skorotkiewicz/mempalace
How to Drive an LLM — Robusta Blog
Robusta · 2026-06-19 · via Hacker News - Newest: "LLM"
Back to blog

Jun 16, 2026

I've been thinking about why some teams get dramatically more out of coding agents than others, and I'm increasingly convinced the answer has less to do with the actual models than people think.
How to Drive an LLM

I've been thinking about why some teams get dramatically more out of coding agents than others, and I'm increasingly convinced the answer has less to do with the actual models than people think.

Last week, right before an hour-long call, one of our engineers told Claude to implement a feature she'd designed that morning — remote tool calling across remote agents. By the end of the call it was running: ten agent instances running on ten Kubernetes clusters, one querying the others. And while she'd put time into the initial plan, she didn't need to nudge the agent along after that — it one-shot the whole thing.

This only works because her Claude Code can deploy large amounts of test infrastructure on its own, hit the edge cases we hadn't designed for, fix them, and verify each fix live — so it just kept going until the feature actually worked, without stopping for a human.

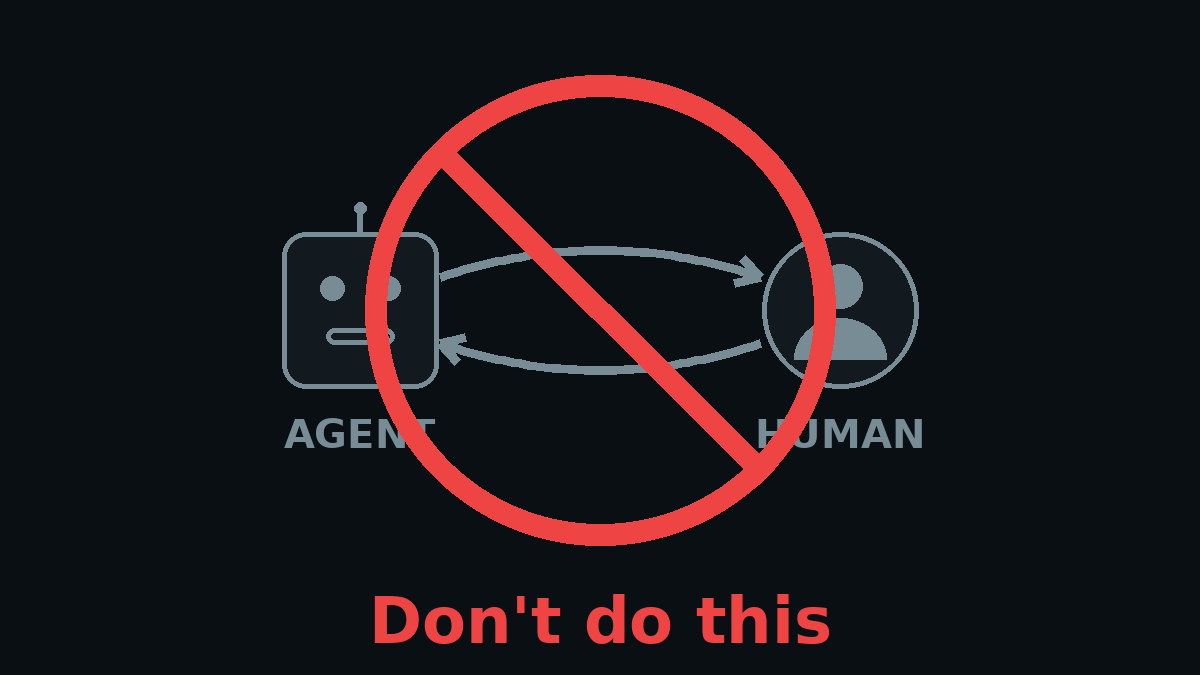
We call this machinery a harness1 — the environment that lets an agent spin up our full stack, exercise a feature end to end, take screenshots and actually look at them — or do whatever else a human would need to do to verify the work. Building harnesses is easy, so long as you're persistent. Run the agent, watch where it stops, and fix that stop — but the right way: instead of running the command or pasting in the error yourself, give the agent the visibility to find the problem on its own, so next time it gets there without you. Then run it again. There are always more stops than you think, and you don't get the fast autonomous loop until you've worked through them all. A prerequisite for all this is running Claude Code (or your own favorite coding agent) in a sandboxed environment where you can safely auto-approve every tool call.

A few examples of what this looks like for us:

  • Frontend work. This is the obvious one, and the one most people are already doing. Your coding agent needs a browser, login credentials for your app, and the ability to screenshot or record what it does, so it can check its own work and show you. We've had the most success when the agent can stand up a frontend connected to a real backend, like a staging or seeded environment, and can modify and run both together.
  • Testing AI agents. Our product is an AI SRE agent that groups and investigates massive volumes of production alerts, so the thing we most need to test is an agent itself — and testing that is non-trivial. Like most companies, we do this with evals — automated test cases that score the agent's output. But unlike most companies, we don't build a feature and then run evals afterward. Instead, Claude Code has the full setup to provision a real cloud environment and run the evals itself to check its own work as it goes. For most features it writes a failing (red) eval first, then iterates until it's green.
  • Testing Slack bots. You can tag our SRE agent in Slack or Teams to investigate an alert, so we have to test that whole surface too. End to end, that means spinning up a Slack workspace, installing the app, and driving a browser logged in as a Slack user — so our coding agent can post a message, trigger our Slack bot (which is itself an agent, so the harness also needs its own LLM API key), and read what it said back, all through a real Slack UI.

For startups like us, competing and winning against bigger, established players, velocity is everything — and in 2026, velocity has one major variable: how often a human has to step in and unblock the agent. Every time the agent stops and waits for a person, the loop runs at human speed — minutes or hours per turn, orders of magnitude slower. Take the human out and the same loop runs all night, without you.

Here's a tip for getting started: the next time you're about to copy-paste something to the agent — an error, a log, a screenshot — stop and ask what it would take for the agent to see that itself. There are usually several missing pieces. Pick the easiest one and build that first. Then keep doing that until you're out of the loop — and you'll be done. Good luck, and happy looping.

1 Technically the harness is Claude Code, but we're misappropriating the term in a way we find useful.
Natan Yellin

Natan Yellin, CEO — Natan has been writing software for over 15 years. He regularly posts on LinkedIn.

Work emailTell us about your infrastructure