



惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

大猫的无限游戏
大猫的无限游戏
H
Hackread – Cybersecurity News, Data Breaches, AI and More
博客园_首页
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
D
Docker
酷 壳 – CoolShell
酷 壳 – CoolShell
宝玉的分享
宝玉的分享
Martin Fowler
Martin Fowler
美团技术团队
量子位
M
MIT News - Artificial intelligence
Apple Machine Learning Research
阮一峰的网络日志
阮一峰的网络日志
博客园 - 叶小钗
博客园 - 三生石上(FineUI控件)
腾讯CDC
Hugging Face - Blog
Hugging Face - Blog
博客园 - 【当耐特】
小众软件
小众软件
博客园 - 司徒正美
罗磊的独立博客
云风的 BLOG
云风的 BLOG
B
Blog RSS Feed
博客园 - 聂微东

Louis C Deng's Blog

RoPE: Properties, Patterns, and Long-Context Behavior CS336 Assignment 1: Large Language Model Training and Inference CS231n Lecture Note: Generative Models CS231n Lecture Note: Self-Supervised Learning CS231n Lecture Note: Large Scale Distributed Training 自動微分 | DIY 實現自己的 PyTorch From RNNs to Transformers CS231n Lecture Note VII: Recurrent Neural Networks Uncovering Batch & Layer Normalization CS231n Lecture Note VI: CNN Architectures and Training CS231n Lecture Note V: Convolution Neural Networks Basics Demystifying Softmax Loss: A Step-by-Step Derivation for Linear Classifiers Backpropagation: A Vector Calculus Perspective CS231n Lecture Note IV: Neural Networks and Backpropagation CS231n Lecture Note III: Optimization CS231n Lecture Note II: Linear Classifiers CSAPP Cache Lab II: Optimizing Matrix Transposition CSAPP Cache Lab I: Let's simulate a cache memory! CS188 Search Lecture Notes III CS188 Search Lecture Notes II How to Use TouchID for Sudo Commands on macOS CS188 Search Lecture Notes I RECAP2025: 留白 CSAPP Bomb Lab 解析 x64 暫存器速查表 CSAPP Data Lab 解析 矩陣的 Modified Gram Schmidt 方法 聊一聊位掩碼(Bit Mask) 整數溢位與未定義行為 快速排序 幾種劃分方法討論
CS231n Lecture Note I: Image Classification
Louis C Deng · 2026-02-10 · via Louis C Deng's Blog

Image Classification

Task: assigning an input image one label from a fixed set of categories

Images are defined as tensors of integers between [0,255], e.g. 800 x 600 x 3

Challenges:

  • Viewpoint variation
  • Scale variation
  • Deformation
  • Occlusion
  • Illumination conditions
  • Background clutter
  • Intra-class variation

A good image classification model must be invariant to the cross product of all these variations, while simultaneously retaining sensitivity to the inter-class variations.

The data-driven approach: first accumulating a training dataset of labeled images, then develop learning algorithms to learn about them.

The image classification pipeline:

  1. Input: Input a set of N images, each labeled with one of K different classes.
  2. Learn: use the training set to learn what every one of the classes looks like. training a classifier, or learning a model.
  3. Evaluate: evaluate the quality of the classifier by asking it to predict labels for a new set of images that it has never seen before.

Nearest Neighbor Classifier

Here is the English translation of your content.

L1 Distance (Manhattan Distance)

L1 Distance is the sum of the absolute values of the differences between corresponding dimensions of two vectors. The calculation formula is:

L1(X,Y)=∑i=1n∣xi−yi∣=∣x1−y1∣+∣x2−y2∣+...+∣xn−yn∣L1(X, Y) = \sum_{i=1}^{n} |x_i - y_i| = |x_1 - y_1| + |x_2 - y_2| + ... + |x_n - y_n|

L2 Distance (Euclidean Distance)

L2 Distance is the square root of the sum of the squared differences between corresponding dimensions of two vectors. This is what we commonly refer to as the straight-line distance between two points. The calculation formula is:

L2(X,Y)=∑i=1n(xi−yi)2=(x1−y1)2+(x2−y2)2+...+(xn−yn)2L2(X, Y) = \sqrt{\sum_{i=1}^{n} (x_i - y_i)^2} = \sqrt{(x_1 - y_1)^2 + (x_2 - y_2)^2 + ... + (x_n - y_n)^2}

Note on L2: Squaring amplifies values, thereby magnifying the influence of outliers.

Evaluation

For evaluation, we use accuracy, which measures the fraction of predictions that were correct.

k-Nearest Neighbr Classifier

The idea: we will find the top k closest images, and have them vote on the label of the test image.

Hyperparameters

It’s often not obvious what values/settings one should choose for hyperparameters.

We cannot use the test set for the purpose of tweaking hyperparameters.

-> Split your training set into training set and a validation set. Use validation set to tune all hyperparameters. At the end run a single time on the test set and report performance.

Cross-validation

Cross-validation: iterating over different validation sets and averaging the performance across these.
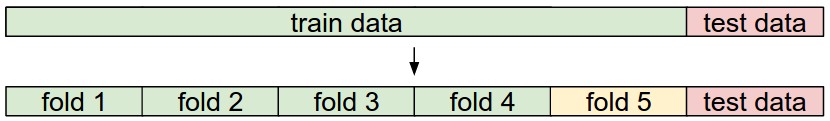
Cross-validation