


Choosing a vision model for production is not only about whether a model "supports images". Developers usually need a route that works for real user workflows: image uploads, screenshots, UI debugging, logo detection, document previews, support tickets, and agent workflows that pass visual context through an OpenAI-compatible API.
This benchmark compares gpt-4.1-mini and qwen3-vl-plus through the Crazyrouter OpenAI-compatible Base URL:
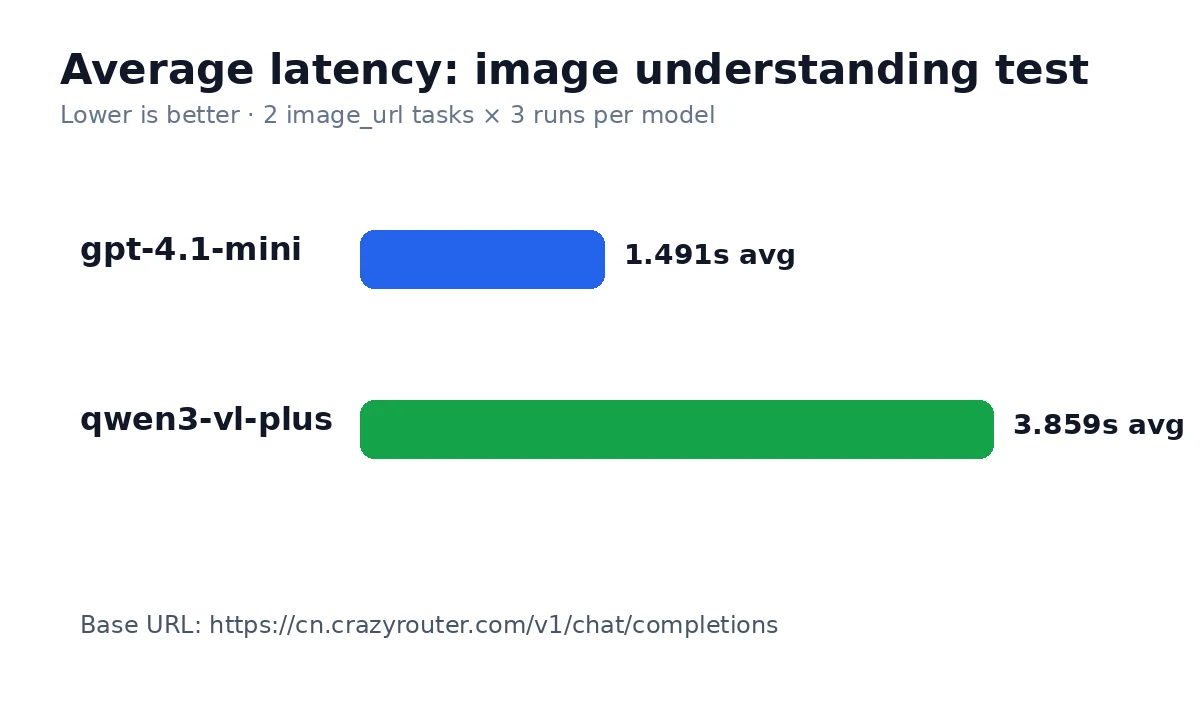
The request format is chat/completions with messages[].content[] containing both text and image_url. Each model was tested on two stable public images, the Python logo and the GitHub logo, with three runs per image.
Test time:
2026-06-21T13:36:32Z. These are measured API results, not copied model-card claims.
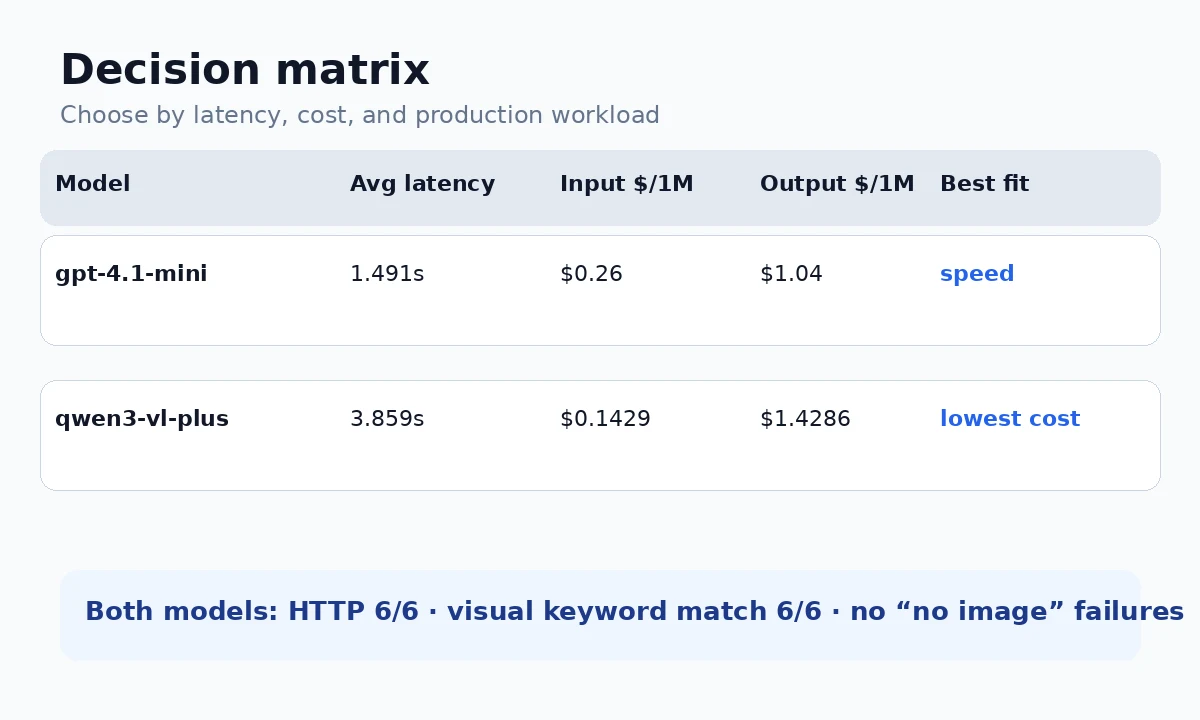
gpt-4.1-mini because it was faster in this run.qwen3-vl-plus because estimated cost per successful image is lower.| Decision dimension | gpt-4.1-mini | qwen3-vl-plus | Why it matters |
|---|---|---|---|
| HTTP success | 6/6 | 6/6 | Transport success only; it does not prove the model saw the image. |
| Correct visual recognition | 6/6 | 6/6 | The most important smoke-test metric for image_url routing. |
| No-image failure claims | 0 | 0 | Detects routes that accepted the request but failed to pass image content. |
| Average latency | 1.491s | 3.859s | Useful for expected user-facing wait time. |
| Median latency | 1.292s | 3.729s | Better than average for typical request experience. |
| Slowest request in run | 2.189s | 4.821s | Tail latency is what users notice when the product feels stuck. |
| Input price / 1M tokens | $0.26 | $0.1429 | Matters for image tagging, OCR pre-filtering, and bulk classification. |
| Output price / 1M tokens | $1.04 | $1.4286 | Matters when prompts ask for longer visual descriptions. |
| Estimated cost / 10k test-style calls | $0.5226 | $0.3848 | More practical than raw token price because it includes observed usage. |
| Usage / image signal | image token fields are zero/missing; verify visual smoke tests instead of trusting HTTP status alone | image token fields are zero/missing; verify visual smoke tests instead of trusting HTTP status alone | Usage metadata can reveal a broken vision path even when HTTP is 200. |
This test is intentionally a vision API smoke test. It is useful for answering:
image_url request path work through an OpenAI-compatible API?It is not a complete benchmark for OCR, chart reasoning, handwriting, medical images, dense document extraction, or multi-image reasoning. For those workflows, use this as the first routing check, then add task-specific evaluations.
| Metric | gpt-4.1-mini | qwen3-vl-plus |
|---|---|---|
| HTTP success | 6/6 | 6/6 |
| Correct recognition | 6/6 | 6/6 |
| No-image replies | 0 | 0 |
| Average latency | 1.491s | 3.859s |
| Median latency | 1.292s | 3.729s |
| Fastest request | 1.239s | 3.423s |
| Slowest request | 2.189s | 4.821s |
| Avg prompt tokens observed | 159.0 | 176.0 |
| Avg completion tokens observed | 10.5 | 9.3 |
| Task | Model | Sample output | Latency | Prompt tokens |
|---|---|---|---|---|
logo_python | gpt-4.1-mini | Python programming language official logo with two snakes. | 1.69s | 159 |
logo_python | qwen3-vl-plus | The main logo in the image is the Python programming language logo. | 3.842s | 176 |
logo_github | gpt-4.1-mini | GitHub's black cat silhouette logo inside a circle. | 1.239s | 159 |
logo_github | qwen3-vl-plus | The image shows the GitHub logo. | 4.821s | 176 |
For chat apps, customer support tools, and user-facing image upload flows, latency and reliability dominate. A cheaper model is not cheaper if users retry, abandon the flow, or trigger a fallback on every request. Use the faster route as the first candidate only if it also passes the visual smoke test.
For high-volume classification, cost per successful image matters more than raw model prestige. Use the lower-cost route when the task is simple and the answer format can be validated. Add a fallback only for empty answers, no-image claims, or low-confidence classifications.
This benchmark does not prove OCR quality. If your workflow involves invoices, tables, forms, receipts, or screenshots with dense text, add a second benchmark with real documents. A model that can identify a logo may still be weak at layout extraction.
Agents need predictable inputs. If a route sometimes drops image content while returning HTTP 200, the agent may make confident but wrong decisions. For agent use, monitor both answer correctness and usage signals, and fail closed when the image path looks suspicious.
image_url support can mean different things: client accepts a URL, gateway fetches and converts the media, or the upstream provider receives the original URL. These are operationally different. They affect bandwidth, privacy, SSRF controls, latency, and billing. Treat media behavior as part of model routing, not an implementation detail.
A valid HTTP response only proves that the API returned something. It does not prove the image reached the model. In vision API monitoring, send a tiny deterministic test image, ask a question with a known answer, and verify both the text response and usage metadata.
This is especially important for routes where usage suggests that image tokens are missing or where the model says no image was provided. Those are not model-quality failures; they may be adapter, media-fetch, payload-conversion, or routing failures.
Code endpoints should not include UTM parameters. Human-facing links can use UTM, for example Crazyrouter Pricing.
The best vision API route depends on the user workflow. For real-time interactions, prioritize correct recognition plus low latency. For bulk classification, prioritize cost per successful image. For agents and document workflows, prioritize reliability, usage signals, and fallback design.
In other words: do not choose a vision model by model name alone. Choose it by task, failure mode, media path, latency, and cost per useful result.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。