









Everyone says they support OpenTelemetry. However, nobody actually emits the same attributes.This blog post covers what engineers at groundcover learned as we build an GenAI SDK, Framework, and Provider agnostic AI Observability solution.
One of groundcover’s main values is that o11y data collection should be straightforward and unbounded. We believe that SRE’s should focus on addressing incidents and root cause analysis instead of instrumentation, data processing, data gaps, dashboarding, and materialized views. We aim to make AI Observability with OTel as simple as it currently is to collect Infra, APM, and RUM data with our eBPF sensor. Through this process we discovered that there are many hurdles associated with traditional instrumentation. We hope these findings highlight our commitment to building tools that just work and put the power back into the developer’s hands.
There's a comforting narrative in the AI observability space, “OpenTelemetry has GenAI semantic conventions, SDKs are adopting them, and soon every LLM call will emit the same standard telemetry. Plug in any backend, get unified visibility”.
We believed this narrative too. Then we tried to actually build it for our AI Observability feature and our Agent Mode, our agentic observability coworker that assists you in addressing incidents by performing root cause analysis within your own cloud.
We spent weeks building a normalizer that ingests GenAI spans from every major instrumentation SDK and produces a single canonical view for any Gen AI data — model, tokens, cost, messages, tool calls — regardless of which SDK emitted the span or which LLM provider was called.
This post is the field report.
Before we dive into the details of the normalizer let’s take a moment to understand what groundcover offers for AI Observability. We support two paths for capturing GenAI telemetry:
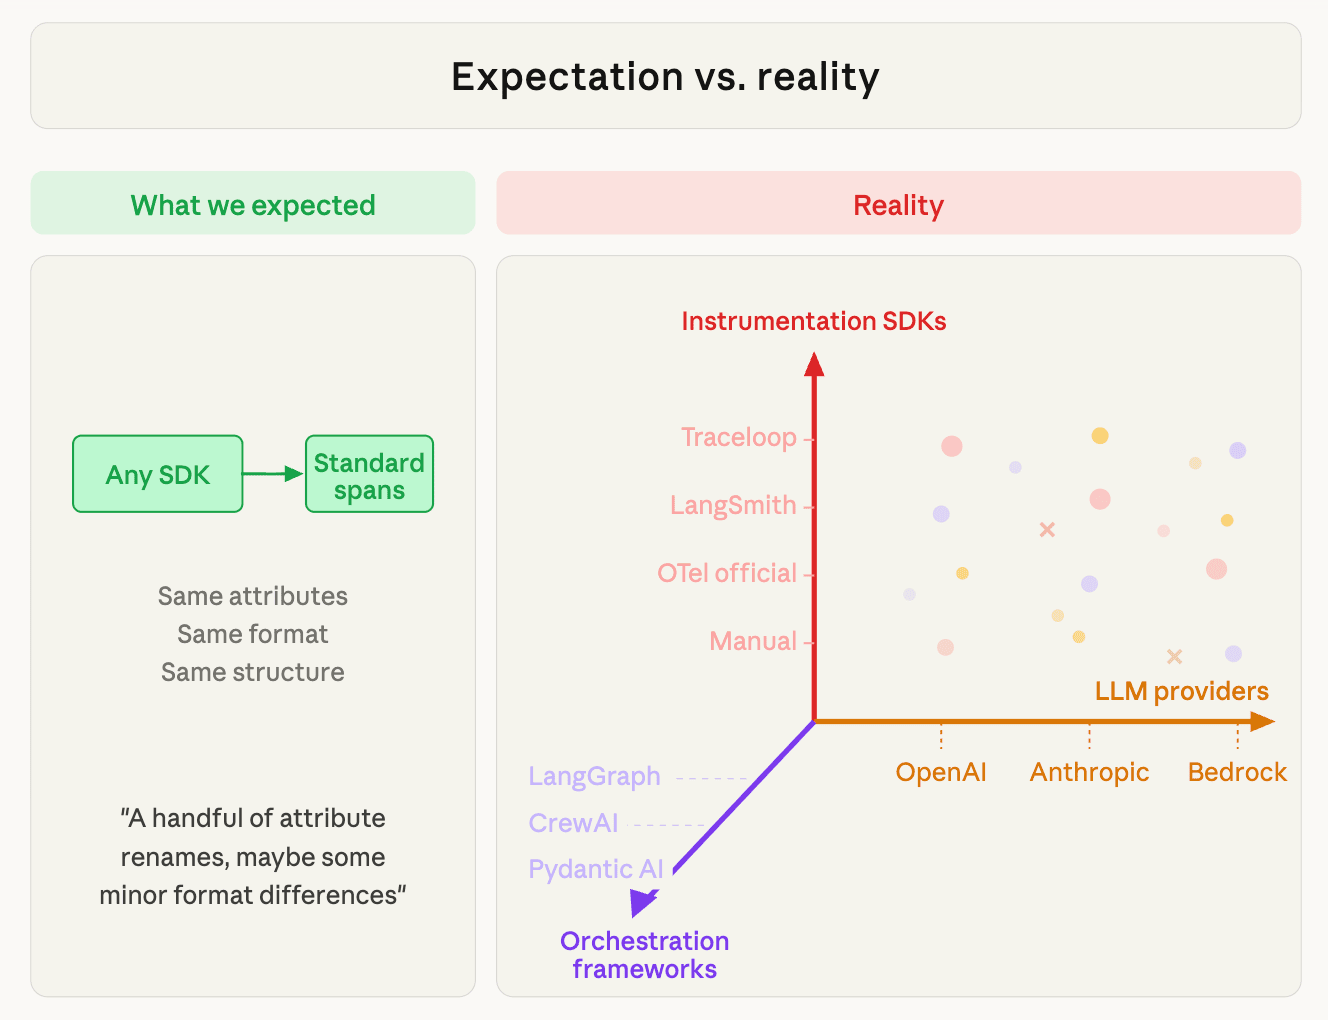
The complexity isn't one-dimensional. There are three independent vectors that combine to produce the telemetry we need to normalize:
In other words, LangGraph + Traceloop + Anthropic produces different telemetry than LangGraph + Traceloop + OpenAI (provider axis), which is different from the telemetry that CrewAI + Traceloop + OpenAI (framework axis), which is different that that from CrewAI + LangSmith + OpenAI (SDK axis). The full matrix is SDK × Framework × Provider, and each cell can have unique parsing quirks.
The saving grace: the SDK axis collapses into just four wire formats, and the framework axis mostly affects message structure within those formats (not the format detection itself). But "mostly" is doing a lot of work in that sentence.
Every GenAI span that hits our pipeline comes from one of four formats:
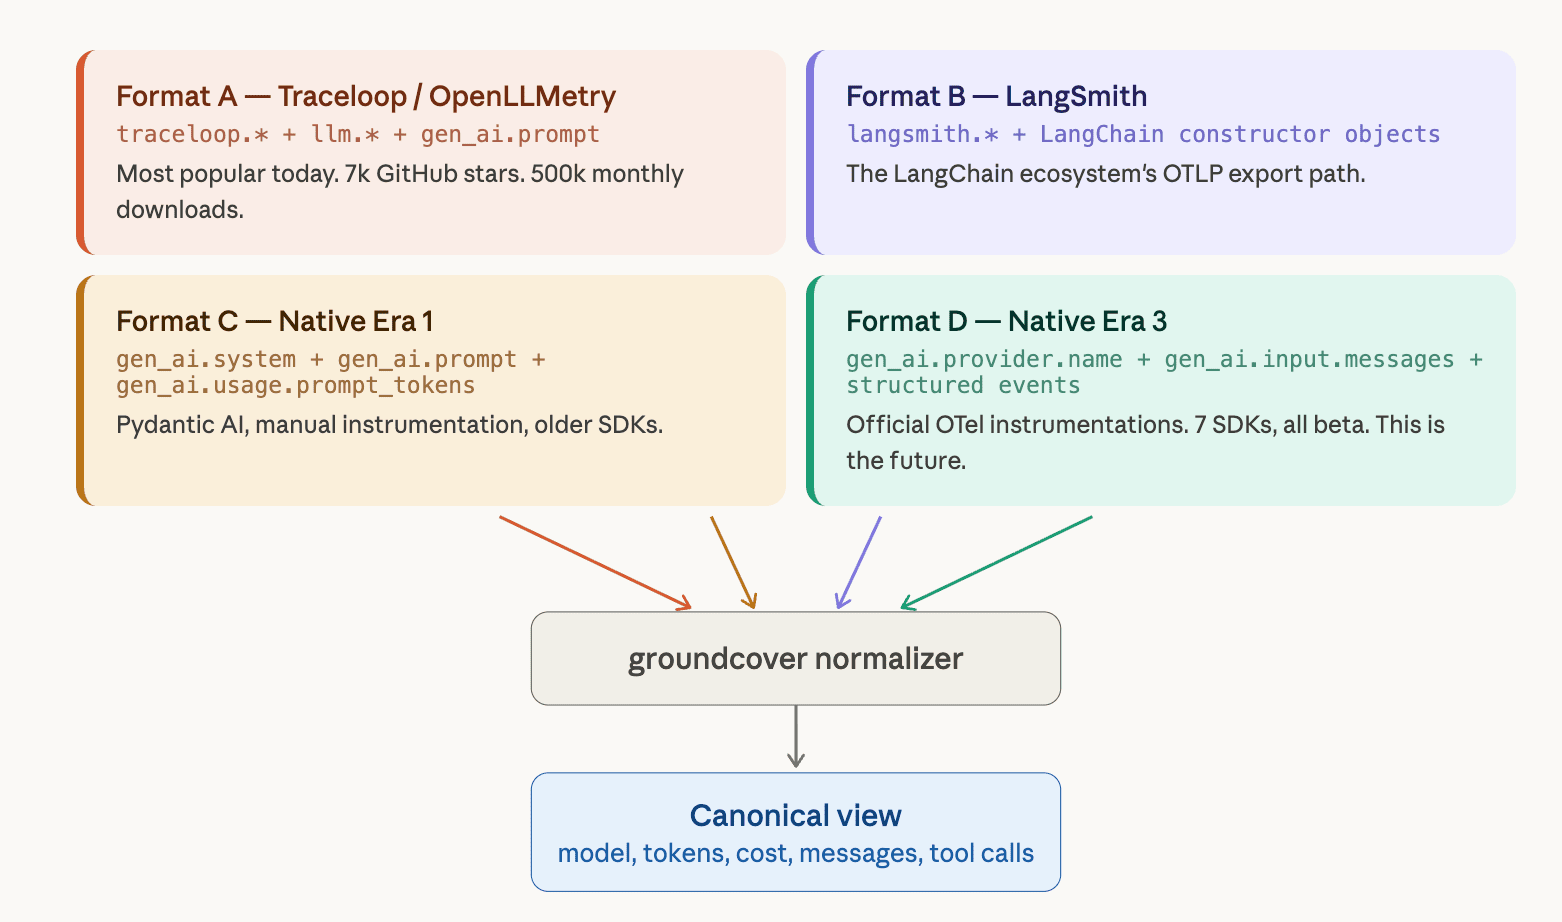
Detecting which format a span uses is the first step. We scan attribute key prefixes. For example, langsmith.* is definitive for Format B. While traceloop.* or llm.* is definitive for Format A. Similarly, gen_ai.* without the others is Format C or D. Then each format gets its own extraction logic, its own message parser, and its own post-processing step before everything converges into a single Field struct.
Formats A through C are fully supported today. Format D — the future standard — is partially supported the core attributes work, but structured event promotion and some message content features are still in progress. Our normalizer closes the remaining gaps as the official OTel instrumentations mature.
A new SDK that uses an existing format with an existing provider requires zero normalizer changes. A new format requires one parser. That's the theory. In practice, the devil is in the details.
The simplest possible question in AI observability: which model handled this request? Here's where six different sources put the answer:
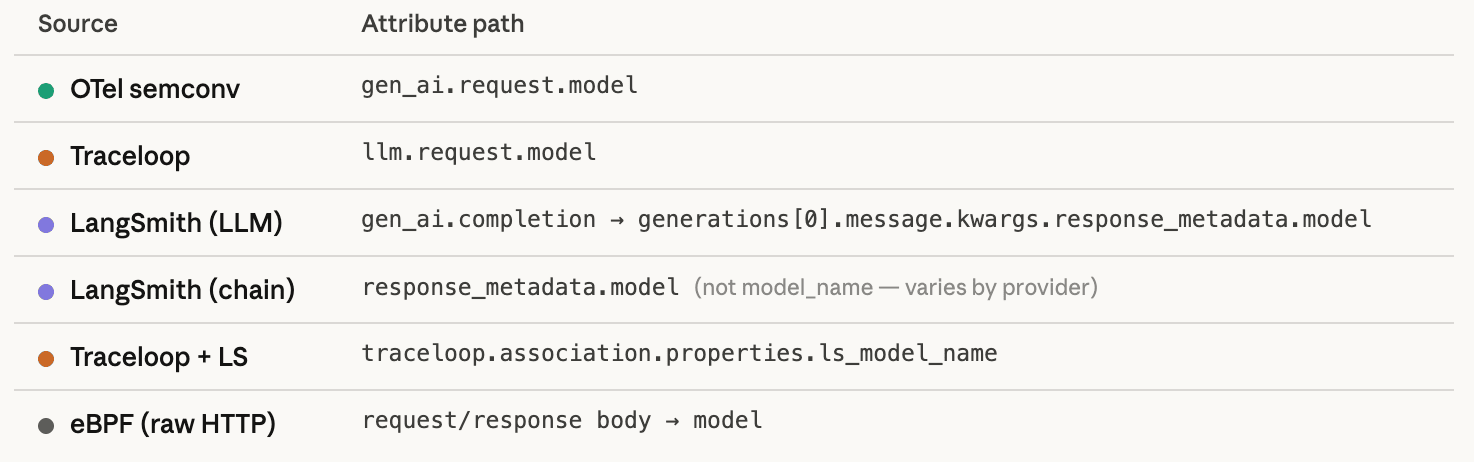
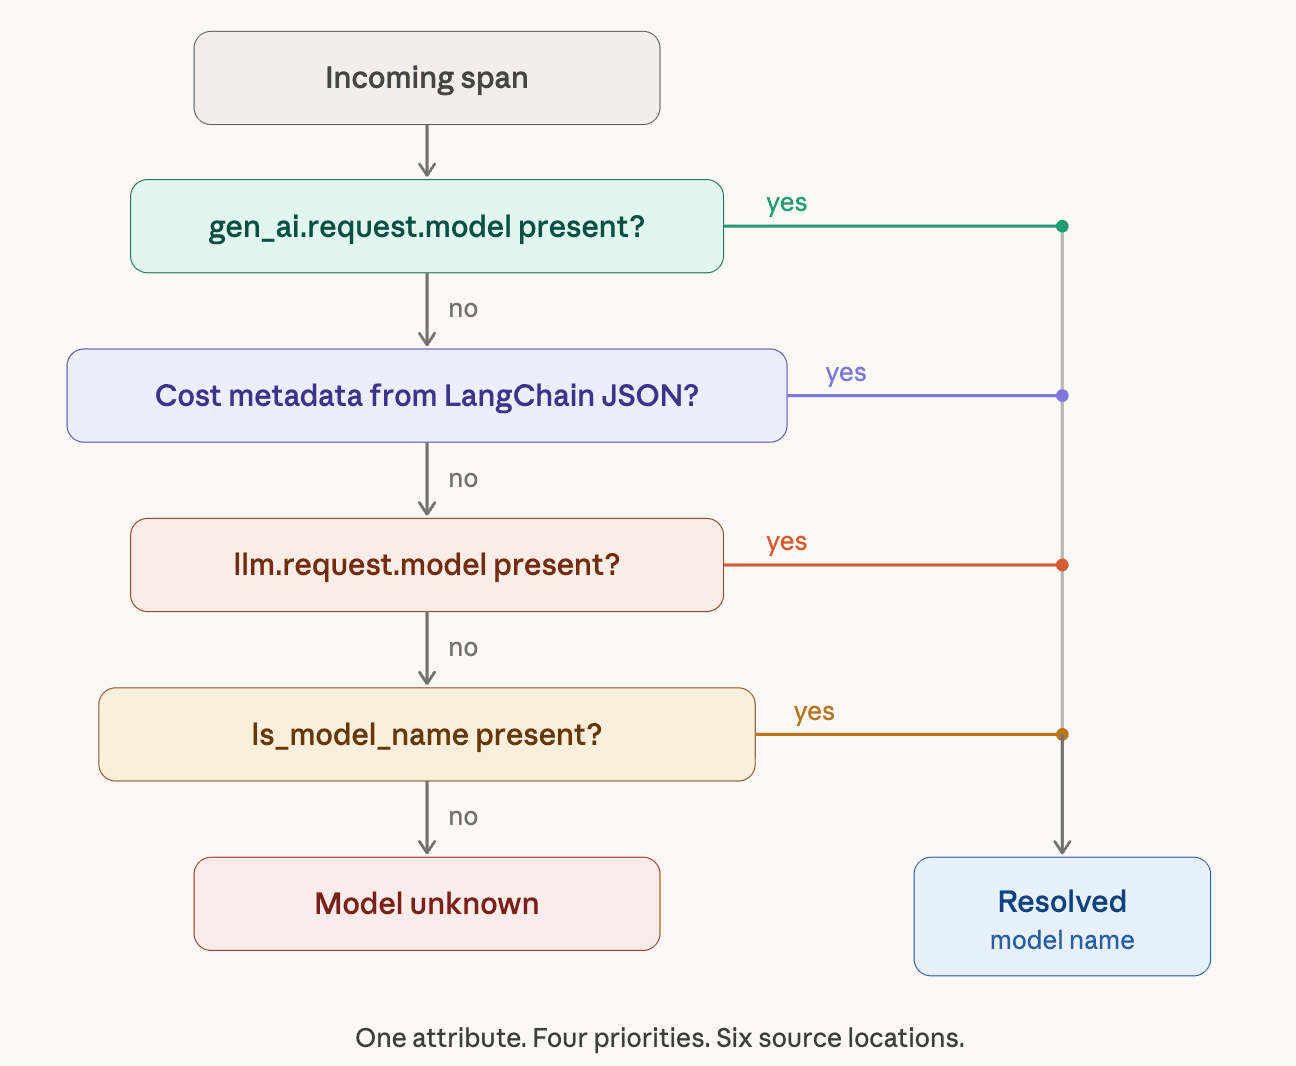
Our normalizer resolves these with a priority chain:
Token counting is the foundation of AI cost tracking. Here's what the ecosystem actually emits:
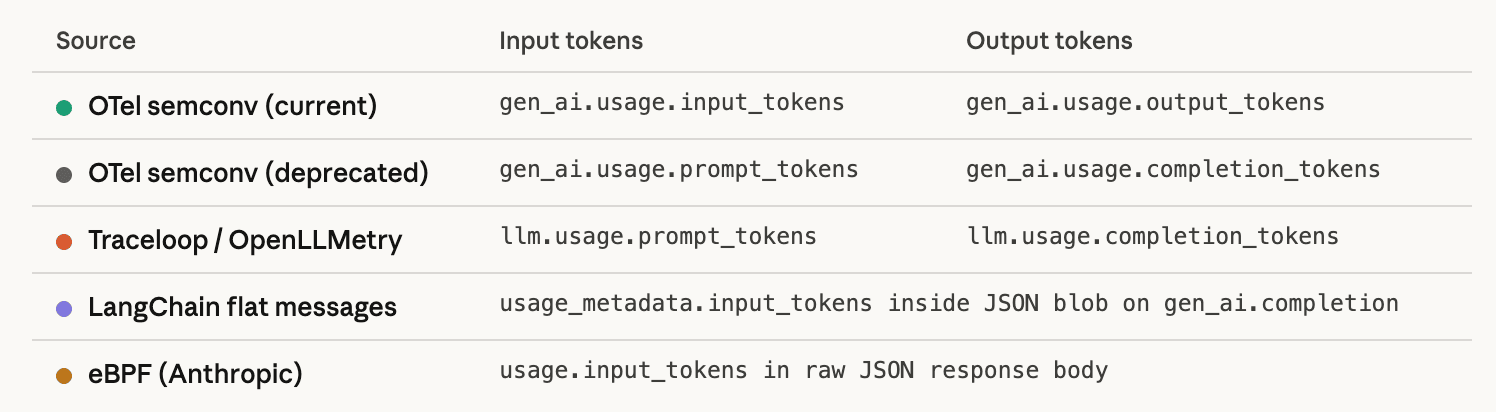
Five naming conventions for the same metric. Our normalizer resolves them with a three-tier priority chain: canonical names win over cost metadata from LangChain messages, which wins over legacy `prompt_tokens`/`completion_tokens` naming.
Unfortunately we haven’t touched on the hard part yet…
Anthropic and OpenAI both report token usage. They disagree on what the number means.
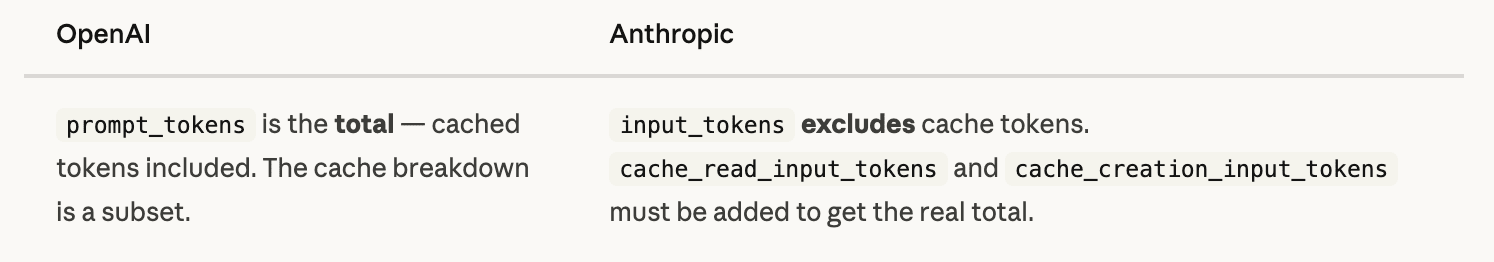
Our normalizer carries a cacheAdditiveProviders set:
var cacheAdditiveProviders = map[string]bool{
    "anthropic":   true,
    "aws.bedrock": true,
}
For these providers, cache tokens get added back to input_tokens so the downstream cost calculation ((input - cache_read - cache_creation) * price) produces correct results. For OpenAI, no adjustment is needed because the total already includes cache tokens.
Different SDKs emit the provider name differently. Same provider, different strings:
var providerMapping = map[string]string{
    "anthropic":       "anthropic",
    "amazon_bedrock":  "aws.bedrock",
    "aws":             "aws.bedrock",
    "AWS":             "aws.bedrock",
    "bedrock":         "aws.bedrock",
    "azure":           "azure.ai.openai",
    "Azure":           "azure.ai.openai",
    "google":          "gcp.gemini",
    "Google":          "gcp.gemini",
    "gemini":          "gcp.gemini",
    "vertex":          "gcp.vertex_ai",
    "vertex_ai":       "gcp.vertex_ai",
    "groq":            "groq",
    "Groq":            "groq",
    "openai":          "openai",
    "OpenAI":          "openai",
    // ... 26 entries total
}
Twenty-six input values, fifteen canonical outputs. Case sensitivity, abbreviations, alternate names — the real world doesn't respect enums. And the list keeps growing as teams adopt AI gateways and proxies (LiteLLM, Portkey, OpenRouter) that add more hosts to recognize on top of the direct provider endpoints.
In Part 2 we’ll go deeper into messages, parsing, framework-specific span trees, the three eras of OTel Gen AI conventions, and what happens when there’s no SDK at all. But the lessons from Part 1 are clear. There is a big difference between “we support OTel” and “we produce correct, unified telemetry”. The groundcover OTel normalizer for GenAI absorbs the complexity of differing naming conventions, token counts, message payloads, provider names, and much more so DevOps teams can focus on root cause analysis. AI observability should be as simple as installing an eBPF sensor regardless of the providers, frameworks, or SDKs you choose.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。