

惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

让小产品的独立变现更简单 - ezindie.com
云风的 BLOG
云风的 BLOG
Microsoft Security Blog
WordPress大学
WordPress大学
GbyAI
GbyAI
C
Check Point Blog
M
MIT News - Artificial intelligence
T
The Blog of Author Tim Ferriss
Jina AI
Jina AI
博客园 - 【当耐特】
U
Unit 42
月光博客
月光博客
腾讯CDC
Y
Y Combinator Blog
小众软件
小众软件
博客园_首页
Last Week in AI
Last Week in AI
酷 壳 – CoolShell
酷 壳 – CoolShell
The GitHub Blog
The GitHub Blog
博客园 - 聂微东
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
MongoDB | Blog
MongoDB | Blog
博客园 - Franky
T
Tailwind CSS Blog

Hacker News: Front Page

SPICE simulation → oscilloscope → verification with Claude Code — Lucas Gerads Introducing Claude Opus 4.7 Qwen Studio The Future of Everything is Lies, I Guess: Where Do We Go From Here? GitHub - SeanFDZ/macmind: Single-layer transformer in HyperTalk for the classic Macintosh Show HN: Agent-cache – Multi-tier LLM/tool/session caching for Valkey and Redis Ancient DNA reveals pervasive directional selection across West Eurasia [pdf] AI cybersecurity is not proof of work Moving a large-scale metrics pipeline from StatsD to OpenTelemetry / Prometheus GitHub - Nightmare-Eclipse/RedSun: The Red Sun vulnerability repository GitHub - SethPyle376/hiraeth: Local AWS emulator focused on fast integration testing, with SQS support, SQLite-backed state, and a debug-friendly web UI. A Better Ludum Dare; Or, How to Ruin a Legacy GitHub - macOS26/Agent: Any AI, replaces Claude Code, Cursor, OpenClaw. Over 18 LLM providers (Claude, OpenAI, Gemini, Ollama, Zai, HF, Qwen) wired into a native Mac app that writes code, builds Xcode projects, bumps versions, manages git, automates Safari, use AppleScript, JS or Accessibility, extend Agent! w/ MCP Servers, run tasks from your iPhone via Messages. YouTube now lets you turn off Shorts I Made a Terminal Pager Burgers | マクドナルド公式 Commands — HackerNews CLI documentation ChatGPT for Excel PiCore - Raspberry Pi Port of Tiny Core Linux Live Nation illegally monopolized ticketing market, jury finds Google Broke Its Promise to Me. Now ICE Has My Data. Founding Engineer at Adaptional | Y Combinator CRISPR takes important step toward silencing Down syndrome’s extra chromosome GitHub - saffron-health/libretto: The AI toolkit for building reliable browser automations US v. Heppner (S.D.N.Y. 2026) no attorney-client privilege for AI chats [pdf] Unexpected €54k billing spike in 13 hours: Firebase browser key without API restrictions used for Gemini requests Fragments: April 14 Cal.com Goes Closed Source: Why AI Security Is Forcing Our Decision | Cal.com - Scheduling Software for Online Bookings Laravel raised money and now injects ads directly into your agent Codex Hacked a Samsung TV
The new HTTP QUERY method explained
Manuel · 2026-06-23 · via Hacker News: Front Page

In the world of RESTful APIs, we have long lived by a strict set of (self-imposed) rules. Whether you are fetching data with GET, creating an entity with POST, or updating a resource with PUT, the HTTP method tells the server what your intention is.

Quite recently, RFC 10008 got published, which defines the new QUERY method for HTTP. Why is this needed when we already have other HTTP methods? Let's find out.

From a purely technical point of view, the HTTP method is just a string. Instead of sending

you could also use

in theory. In practice, there are lots of RFCs and implicit, undocumented behaviour around the well-known HTTP methods, such as GET and POST.

As an example, browsers send a GET request when you enter an address or click on a bookmark. Standard HTTP forms only allow GET and POST as methods. Most proxies, firewalls and webservers only allow the "standard" HTTP methods.

So why introduce a new HTTP method when we already have a set of existing ones that worked well for decades?

Queries using GET

Traditionally, if you wanted to filter a resource, you used query parameters in a GET request (e.g., /api/v1/users?role=admin&status=active&sort=desc). This works well for simple filters. However, when you need to perform complex relational queries, deep nesting, or advanced logic, the URL becomes massive, hard to read, and sometimes hits browser or server character limits.

Other potential problems include:

  • Sending non-ASCII or special characters as parameters requires encoding them, increasing the request size
  • Servers and other middlewares probably log the request parameters, which may be problematic in certain circumstances
  • Expressing some data structures, such as arrays, is not well-defined and implementation specific (e.g. ?roles[0]=admin&roles[1]=reporter vs ?roles=admin&roles=reporter vs ?roles[]=admin&roles[]=reporter)
  • Same for expressing deeply nested structures

Since these are all drawbacks of sending the data as query parameters, why not simply send a GET request with a JSON request body? Again, from a theoretical point of view, this should work. None of the HTTP RFCs explicitly forbid the usage of a request body when performing a HTTP GET request, but indicate that it should not be done. As a result, various client, proxy and webserver implementation handle GET requests with a body differently. Some reject them outright, some simply drop the body while others interpret it.

Due to this, using HTTP GET with a request body is a bad idea, as for example users behind a corporate firewall or a different browser may be unable to use your website. This is also the reason why there is no new RFC which specifies that GET requests should now support request bodies, as that would break lots of existing implementations.

The workaround: Querying using POST

Since sending request bodies using GET could introduce problems, the workaround is to use POST.

While POST allows for a request body, it introduces significant semantic issues. POST is defined as non-idempotent and is intended for resource creation or processing.

While this may not sound like a huge problem, it can be annoying when implementing e.g. automatic retries on failures. As the GET method is defined as safe and idempotent, as long as the server implementation is correct, we can retry failed requests without worrying about side effects. It also makes it impossible for proxies or other middleware to automatically understand that the operation is read-only. For example, a middleware may automatically cache GET requests for some time, which does not work with POST requests.

The QUERY method

All of the above reasons resulted in the QUERY method being specified, after many years of discussion. The QUERY method is nothing special, the RFC roughly states that it is similar to the GET method, but with a request body. It is meant to be safe and idempotent.

QUERY request can be cached, but implementation must be careful to incorporate the request content into the cache key. All in all, it finally offers a fitting HTTP method for complicated search queries.
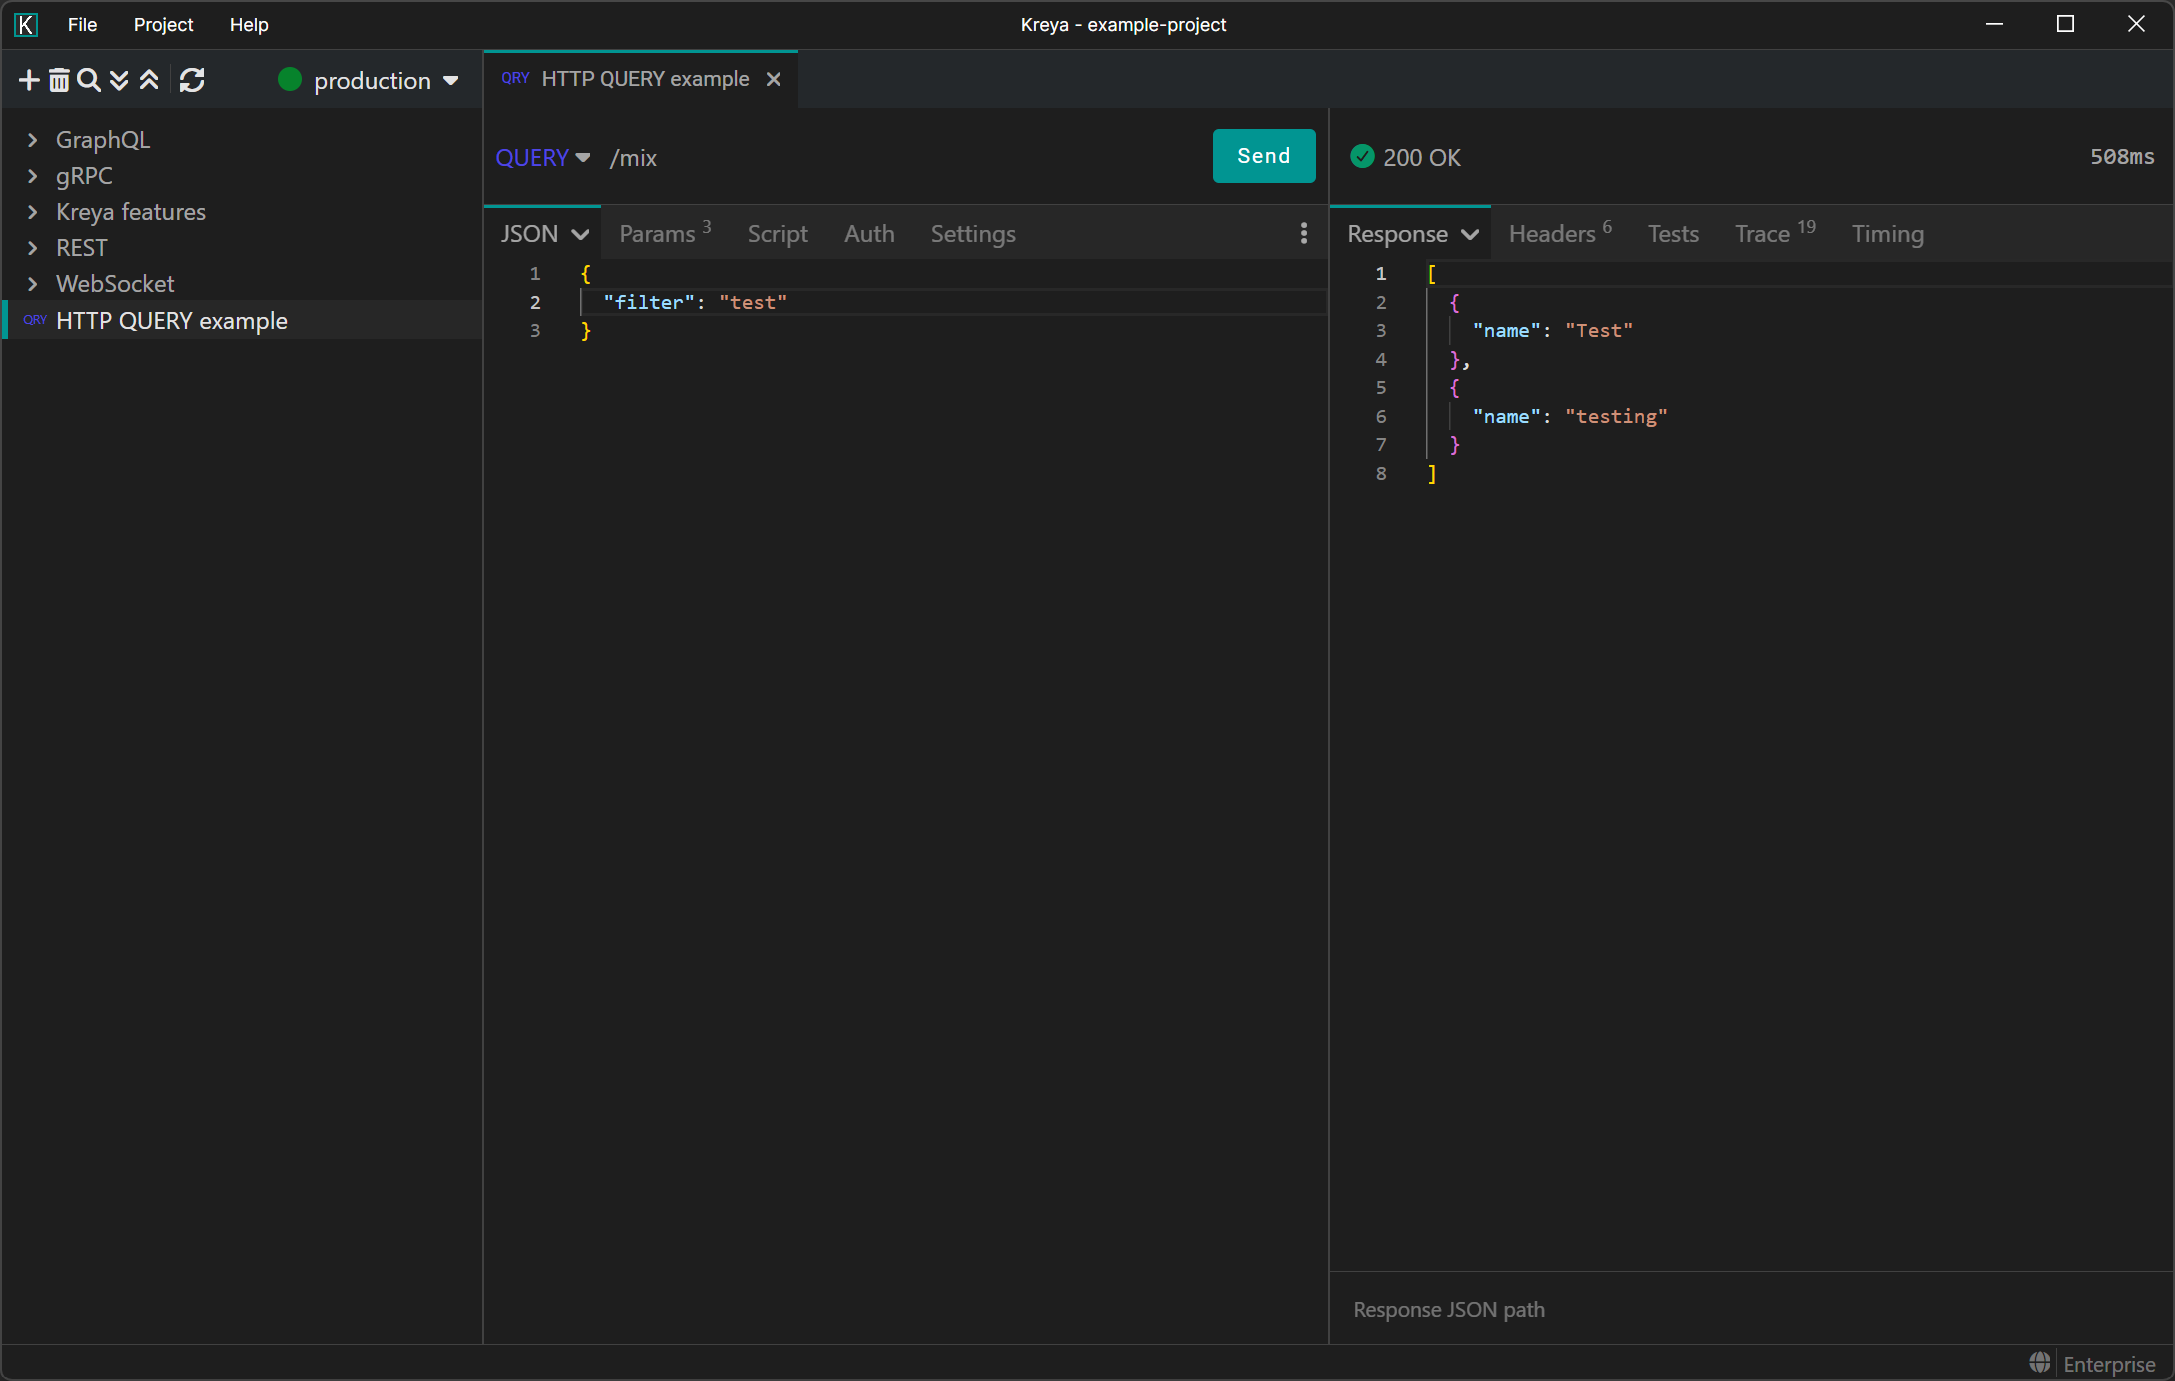
Kreya screenshot of sending a QUERY request

QUERY gotchas

It may be tempting to immediately switch all search related endpoints to use QUERY. Before doing that, there are a few things that you need to consider.

  • Support for HTTP QUERY is still very limited and may be for some time. It may take years for it to be fully supported everywhere. As an example, Kreya has added out-of-the-box support for HTTP QUERY with the recent 1.20 release (though it was possible to send custom HTTP methods before already). Other clients, proxies and webservers may still reject it.
  • Standard GET queries with data in the URL parameters are still perfectly fine. If there is no immediate need to change those to the QUERY method, leave them be.
  • If your users should be able to share or bookmark links of the filtered data, continue using GET requests. Sharing links as QUERY requests does not work.
  • Implementing custom caching for QUERY requests is more difficult than for GET requests, since you need to consider the request body.

Conclusion

In short, HTTP QUERY replaces POST for read-only requests. It may take some time until it is fully supported everywhere, but you should still consider (and test!) it should normal GET requests not suffice for your use case.