


Anthropic has Mythos, but only a select few have seen it. Now, OpenAI has a model that, by all accounts, seems rather comparable—but they're releasing it freely. Like Mythos, GPT 5.5 delivers a step change in vulnerability detection. Over the last couple of weeks, we’ve been part of a select group that had early access. We’ve been testing it across our benchmarks and workflows, and we’re sharing what we’ve observed in practice. Here’s our take on 5.5 and how it performed for our offensive security capabilities.
Models don’t exist in a vacuum, so at XBOW, we don’t evaluate them in isolation. We run them inside our agent workflows, across real penetration testing tasks, and measure how they behave. That includes everything from discovering vulnerabilities, to logging into applications, to producing final reports. We’re also model-agnostic by design. Different parts of our system use different models depending on the job—sometimes that means a smaller, faster model for responsiveness, other times it means using the most capable model available to maximize accuracy.
To understand why that matters, it’s worth briefly explaining how we evaluate models.
As we outlined in a previous post, we’ve built an internal benchmarking system based on real vulnerabilities. We take open source applications where vulnerabilities were previously discovered, freeze them at the vulnerable version, and run our agents against them. The goal isn’t to measure isolated completions, but to evaluate the full process of identifying and exploiting those issues.
This gives us a consistent and realistic way to compare models over time. The primary metric we track here is miss rate: how many known vulnerabilities the model fails to find.
On this benchmark, GPT-5.5 delivers the best performance we’ve seen to date.
For context, GPT-5 missed 40% of vulnerabilities. Opus 4.6 reduced that to 18%. GPT-5.5 brings it down further to just 10%.
That’s not a marginal improvement. Every missed vulnerability is a real life liability. When you’re running automated security testing, closing that gap matters.
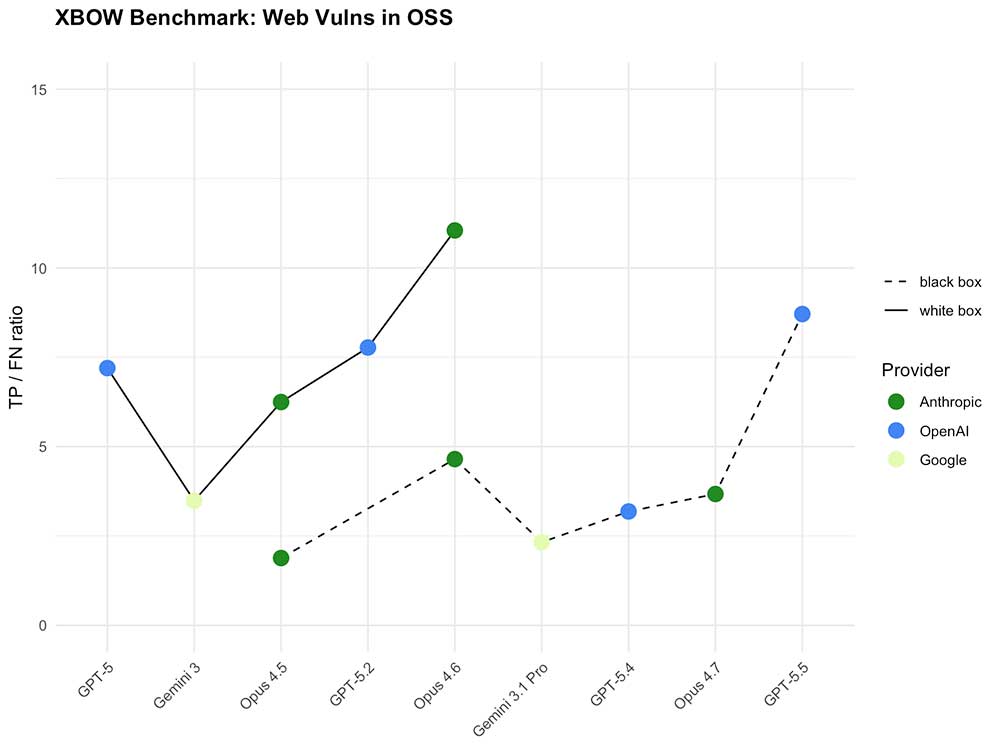
The more striking story shows up when you break out black box vs. white box performance. Both are important – attackers usually see systems from the black box perspective, though for a pentest, customers often will provide their source code to enable the more complete white box testing.
Even without source code, GPT-5.5 already outperforms GPT-5 running with source code. That flips the expected hierarchy on its head: Black box used to mean fighting with oven mitts on. Now it feels like working barehanded.
But then you add source code.
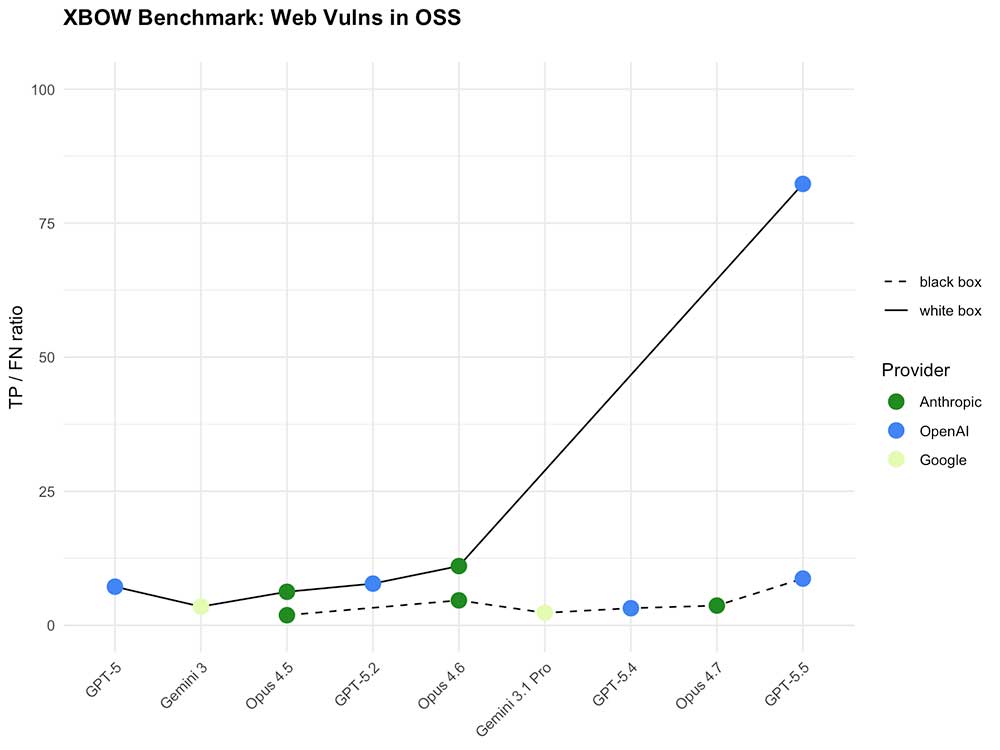
In a white box setting, GPT-5.5 doesn’t just improve—it pulls away. The performance jump is so large it effectively compresses the chart. With code, it’s effectively killed our benchmark.
Bottom line: GPT-5.5 raises the floor in black box testing and blows past the ceiling in white box testing.
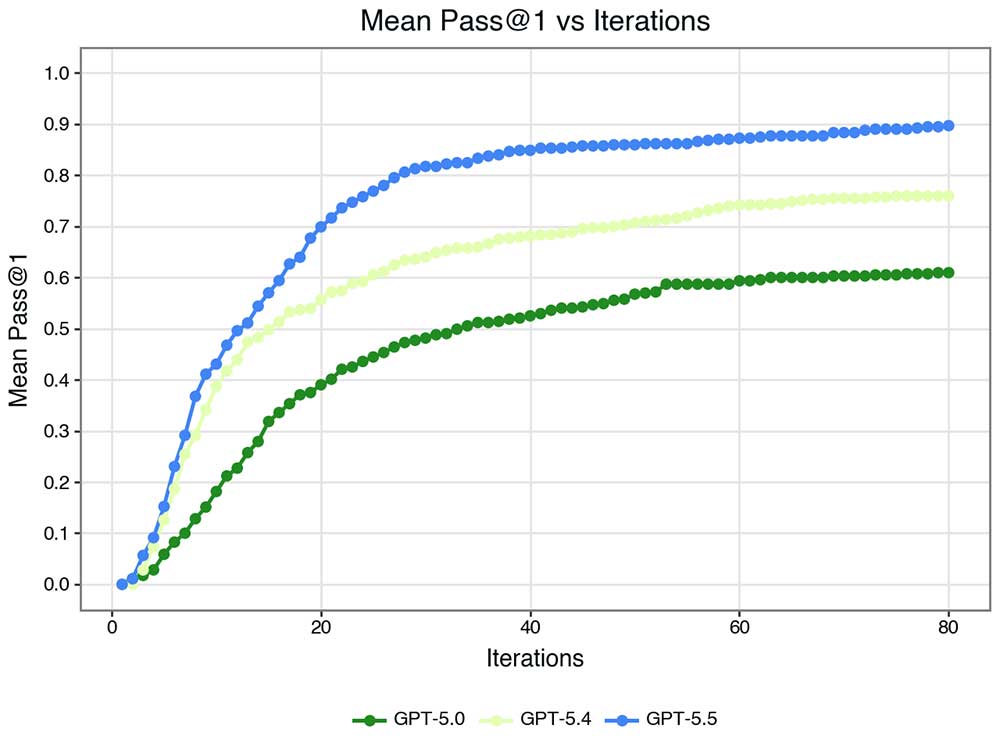
Whether a vulnerability is found or not is not a binary though – some are found quickly, some slowly. When comparing the models by how many actions they take before finding a vulnerability, an interesting pattern in the progression between GPT models emerges:
Even visually, it’s also clear that the difference between 5.4 and 5.5 is a multiple of the typical sub-version advance.
We also test models on what we call “computer use” benchmarks—tasks that reflect how our agents interact with real applications. This includes logging in, navigating interfaces, and dealing with the kinds of friction you encounter in production environments.
On our visual acuity benchmark, GPT-5.5 achieves 97.5%, which puts it within the margin of the best results we’ve seen (Anthropic’s Opus 4.7).
But again, the more interesting improvements show up in actual workflows. When logging into target systems, GPT-5.5 is significantly faster than any model we’ve tested. It successfully logs in using roughly half the number of iterations required by the next best model.
Just as importantly, it fails faster too. If credentials are incorrect or a system blocks access, it identifies that and moves on in about half the time. That might sound like a small detail, but it has a direct impact on user experience. Faster success speeds up assessments. Faster failure means we can notify customers about issues—like broken credentials or bot detection—much earlier.
And it ties into a more general theme:
One of the more understated improvements is how GPT-5.5 behaves when things don’t work.
In practice, agents need to constantly decide whether to persist or pivot. Push too hard on a failing path and you waste time. Give up too early and you miss opportunities. Getting that balance right is difficult, and it’s something even frontier labs are struggling to train LLMs for. After all, RLHF and similar methods optimize them to make their consumer happy, and no one likes the bitter medicine of: “the best thing to do right now is to give up”.
Yet as we keep giving models more and more responsibility, giving up instead of stupidly bashing their head against a wall becomes more important than ever. In XBOW’s set of example cases for situations in which an agent should give up, GPT-5.5 still sometimes persists longer than ideal – but only half as often as previous GPT versions (or Opus, in fact).
That makes GPT-5.5 not just more capable, but also more practical.
All of this translates into tangible improvements.
Investigations complete faster. Vulnerability coverage improves. Feedback loops tighten, especially when something goes wrong early in a test. The overall experience becomes more responsive and more reliable.
Because we run a multi-model system, this doesn’t mean a single model replaces everything else. We’ll continue to use different models across different parts of the stack depending on the task. But for core penetration testing workflows, GPT-5.5 is clearly setting a new bar.
We use the best model for each job, and right now GPT-5.5 is leading in several areas. Some of these are pentesting specific, but its strong performance isn’t limited to these. That paints a picture of a model that’s just generally more powerful – a larger increase than the typical subversion bump.
We’ll continue evaluating it as it rolls into production, but early results suggest it will become a key part of our stack.
LinkedIn Live Webinar: Mythos can surface thousands of findings. The challenge is knowing what actually matters. Join this session to see how teams validate exploitability, prioritize risk, and avoid alert overload in a post-Mythos world. Register today >
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。