


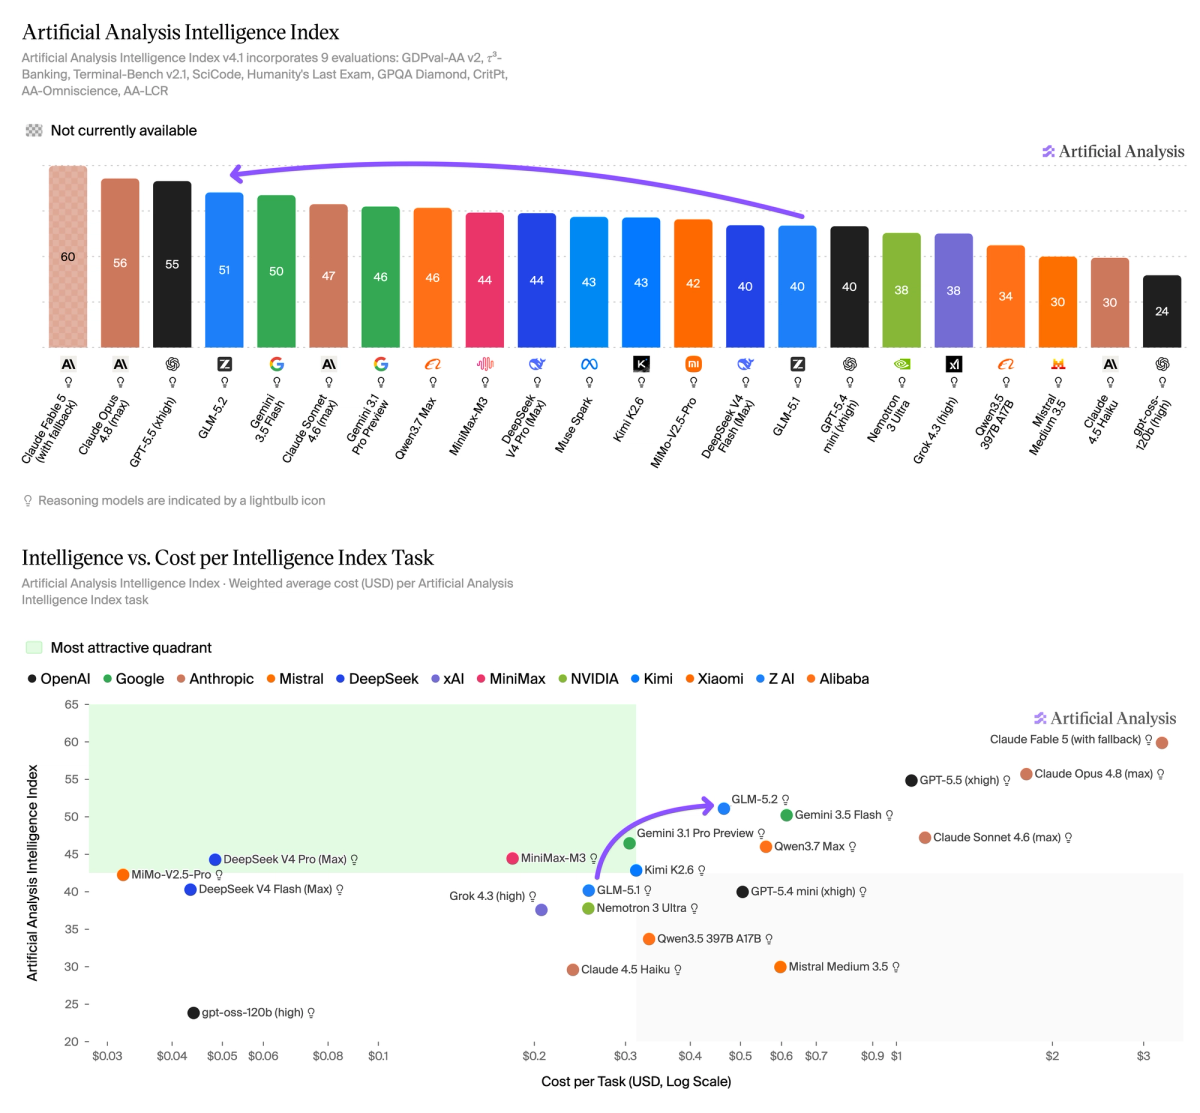
Z ai’s GLM-5.2 is the new leading open weights model on the Artificial Analysis Intelligence Index scoring 51 and it sits on the Pareto frontier of Intelligence vs Cost per Task
GLM-5.2 is the same size as GLM-5.1 (744B total / 40B active parameters) but scores 11 points higher on the Intelligence Index v4.1, placing ahead of MiniMax-M3 (44) and DeepSeek V4 Pro (max, 44). On the first-party API it is priced in line with GLM-5.1 at $1.4/$4.4/$0.26 per 1M input/output/cache hit tokens
Key results:
➤ GLM-5.2 is the leading open weights model on the Intelligence Index v4.1. At 51, it leads MiniMax-M3 (44), DeepSeek V4 Pro (max, 44) and Kimi K2.6 (43)
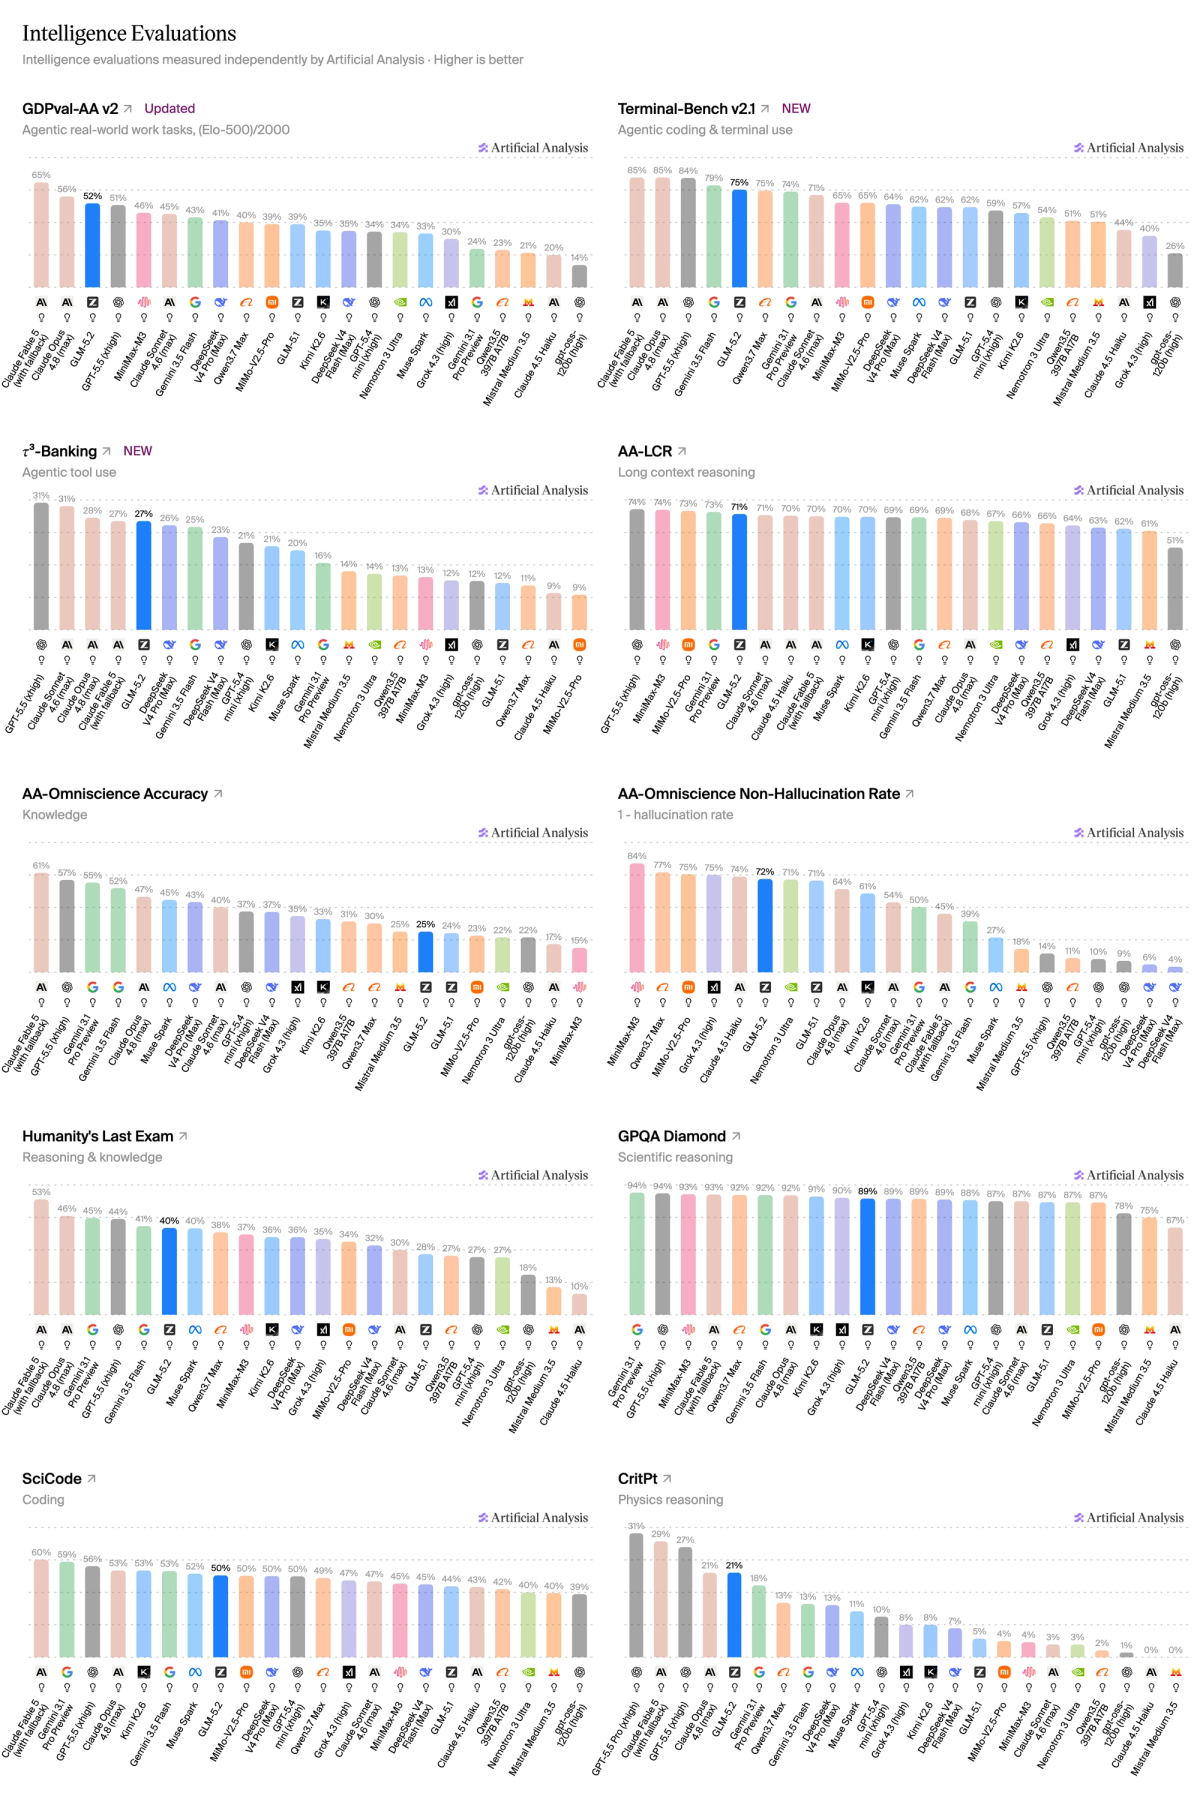
➤ Improvements across most evaluations, particularly scientific reasoning: GLM-5.2 gains over GLM-5.1 on most evaluations, led by scientific reasoning on CritPt (+16 points to 21%) and HLE (+12 points to 40%), alongside AA-LCR (+9 points to 71%), tau3 banking (+15 points to 27%) and SciCode (+7 points to 50%). TerminalBench v2.1 also improves (+16 points to 78%) and GPQA Diamond gains 3 points to 89%
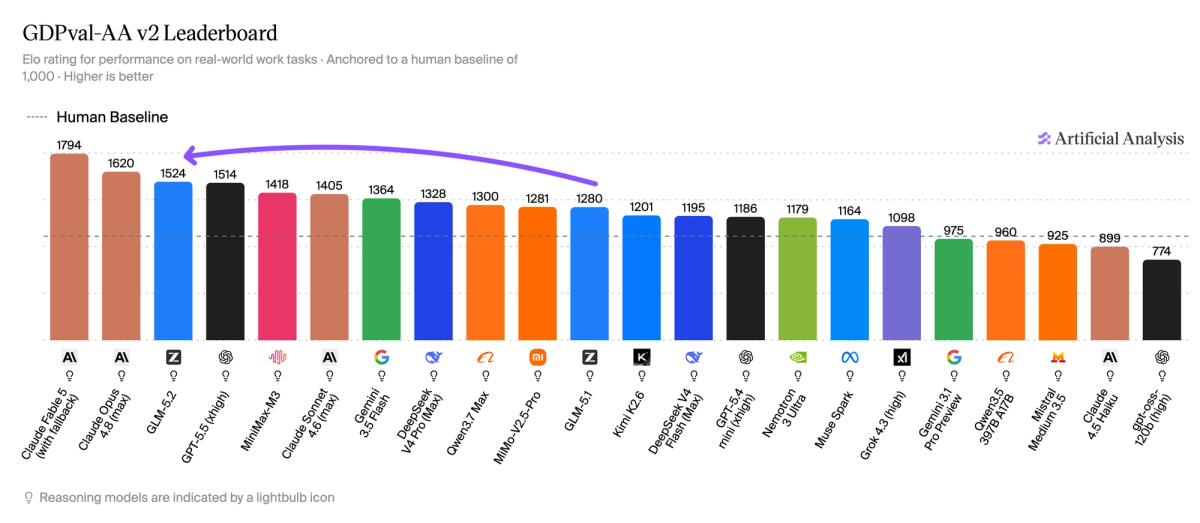
➤ Leading open weights model on GDPval-AA v2 and competitive with proprietary models: GLM-5.2 scores 1524 on GDPval-AA v2, ahead of MiniMax-M3 (1418) and DeepSeek V4 Pro (max, 1328). This impressive result places GLM-5.2 in-line with proprietary models including GPT-5.5 (xhigh reasoning). GDPval-AA v2 builds on the original GDPval-AA by baselining Elo to human performance at 1000, introducing a rotating panel of frontier-model judges, and raising the turn limit from 100 to 250 for longer-horizon agent trajectories
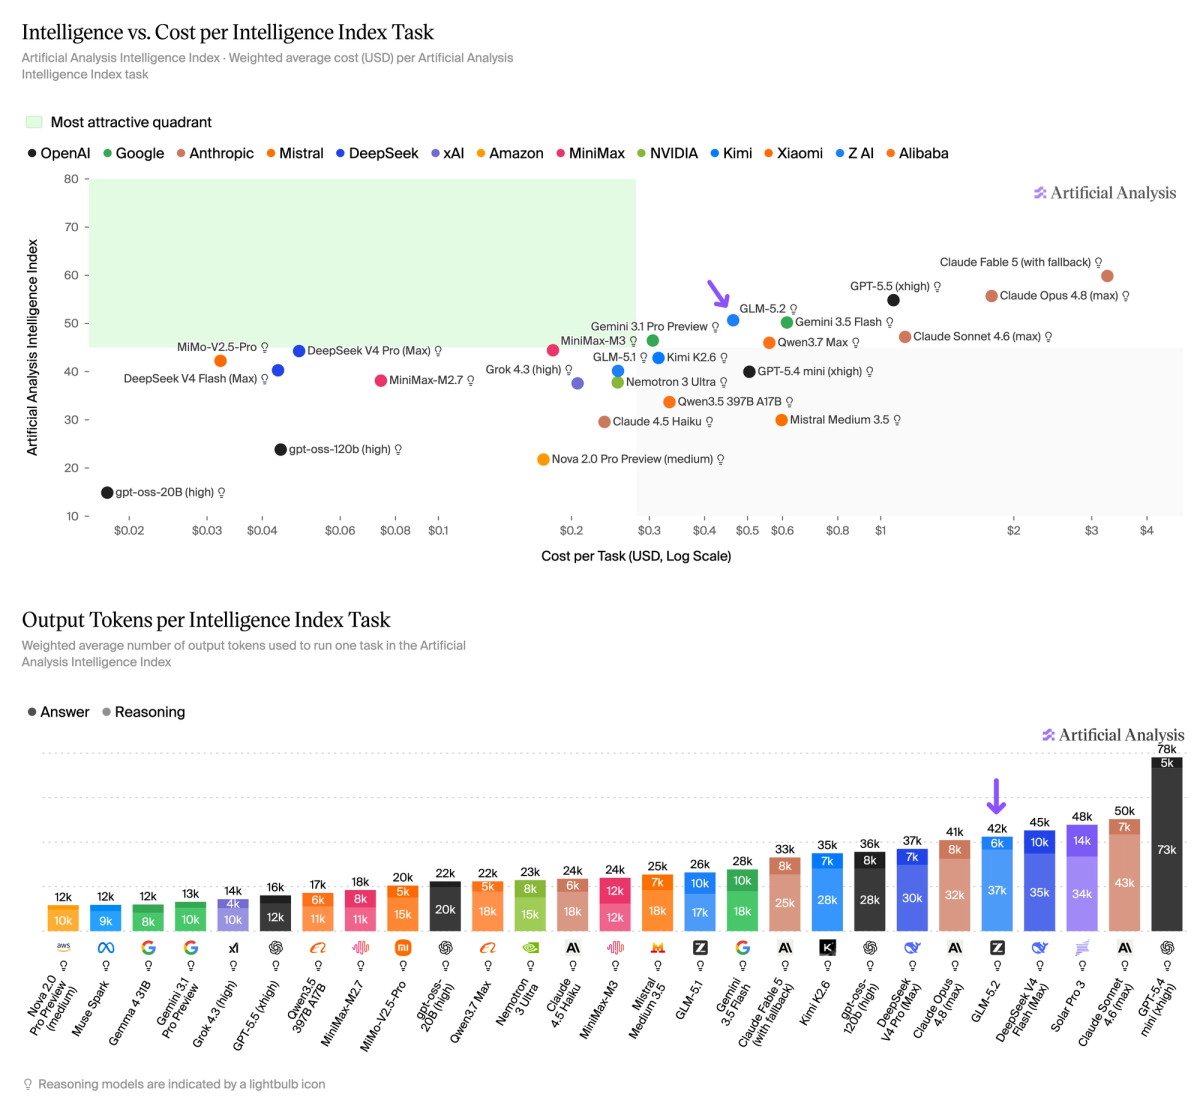
➤ GLM-5.2 uses more output tokens per task than other leading open weights models: the model uses 43k output tokens per Intelligence Index task, up from GLM-5.1 (26k) and above MiniMax-M3 (24k), Kimi K2.6 (35k) and DeepSeek V4 Pro (max, 37k)
➤ On the Intelligence vs. Cost per Task Pareto Frontier: GLM-5.2 is on the Pareto frontier of the Intelligence vs Cost per Task chart, with the lowest cost per task among models at its intelligence level. GLM-5.2 costs ~$0.46 per task, compared to GLM-5.1 ($0.25), Kimi K2.6 ($0.31), MiniMax-M3 ($0.18) and DeepSeek V4 Pro (max, $0.05)
Additional Model Details:
➤ License: MIT
➤ Size: 744B total parameters, 40B active parameters, equivalent to GLM-5.1
➤ Context window: 1M tokens, up from 200K on GLM-5.1
➤ Pricing: $1.4/$0.26/$4.4 per 1M input/cache hit/output tokens
➤ Availability: Alongside Z ai's first-party API, GLM-5.2 is available across third-party providers including DeepInfra, Novita, Nebius, Parasail, Siliconflow, GMI Cloud, Baseten, and Fireworks
GLM-5.2 leads all open weights models on GDPval-AA v2, our primary metric for real-world agentic performance. At 1524 it places ahead of MiniMax-M3 (1418) and DeepSeek V4 Pro (max, 1328), and is effectively level with GPT-5.5 (xhigh, 1514). We visually inspected GLM-5.2's outputs across a range of GDPval-AA tasks. We have attached a selection below.
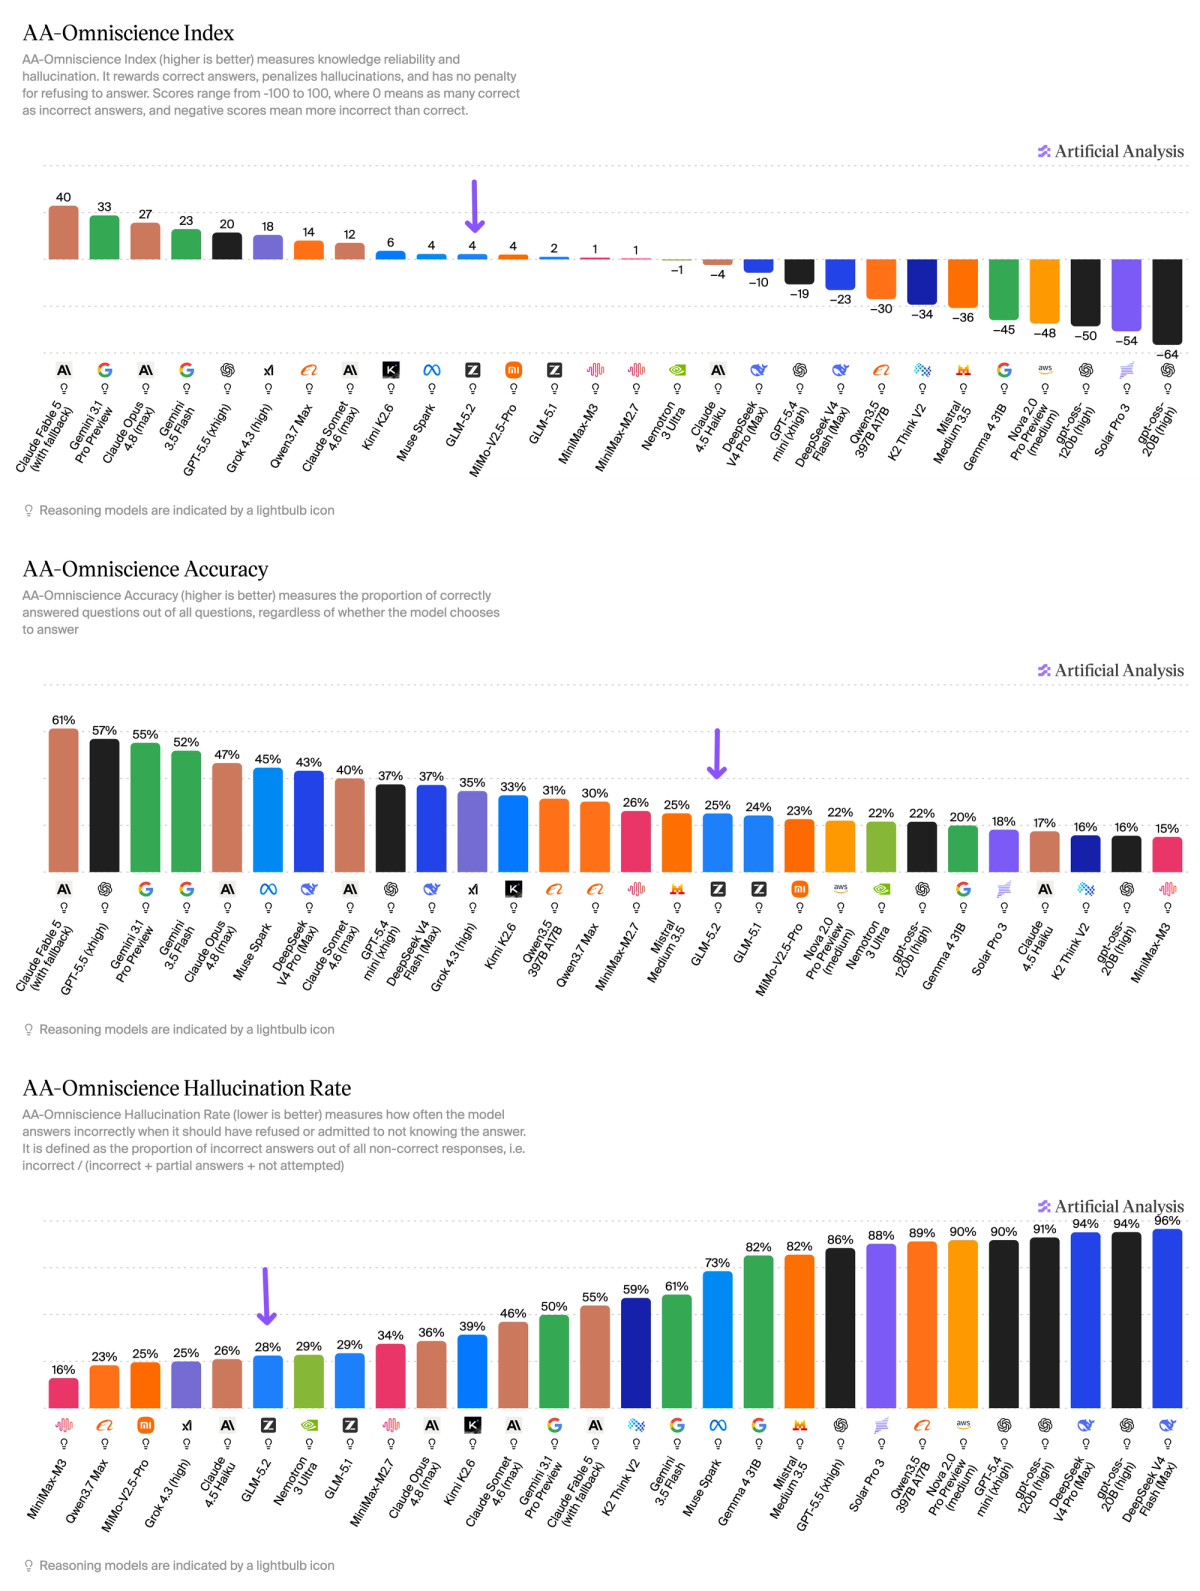
GLM-5.2 scores 4 on the AA-Omniscience Index, up from GLM-5.1 (2). The gain comes from both higher accuracy (25.1% vs 24.2%) and a lower hallucination rate (28.1% vs 29.4%), with attempt rate flat at 47%.
GLM-5.2 uses 43k output tokens per Intelligence Index task, of which 37k is reasoning. This is up from GLM-5.1 (26k) and higher than open weights peers MiniMax-M3 (24k) and Kimi K2.6 (35k), placing it among the less token-efficient open weights models at its intelligence level. GLM-5.2 sits off the most attractive quadrant on the Intelligence vs Output Tokens chart.
Breakdown of the individual evaluations in the Artificial Analysis Intelligence Index v4.1.
Compare GLM-5.2 with other leading models at: https://artificialanalysis.ai/models/glm-5-2
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。