


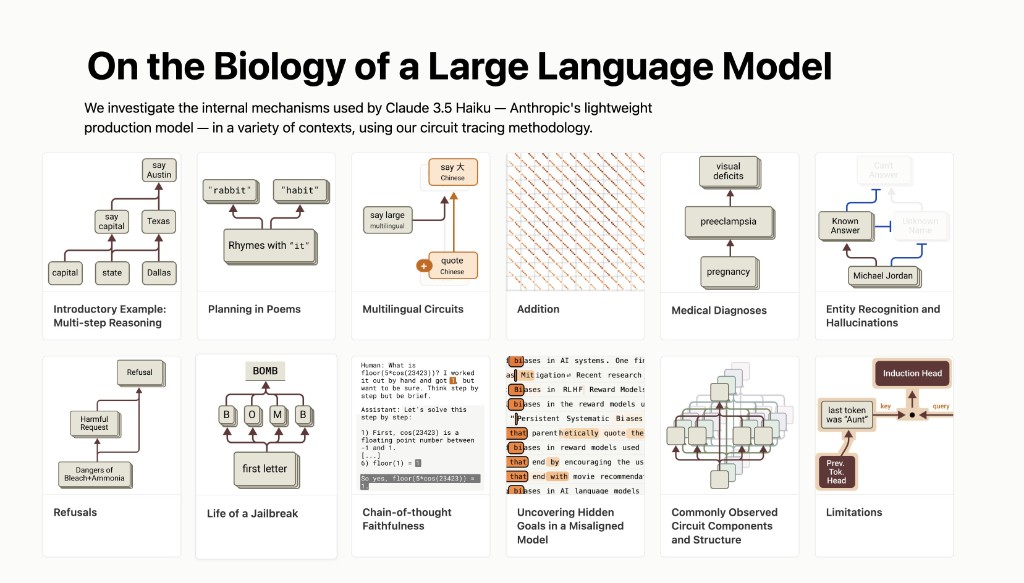
LLMs are not the "black box" you were promised.
Mechanistic interpretability — peering into a neural network to reverse engineer its inner workings — has made major strides. Anthropic's On the Biology of a Large Language Model (2025) is a landmark in that effort. What follows is a summary of their progress and some related thoughts.
What is an LLM actually "thinking"?
How can we understand what an LLM is "thinking"? It's clearly very valuable to do so — it could enable steering model behavior, detecting dangerous intent, and more.
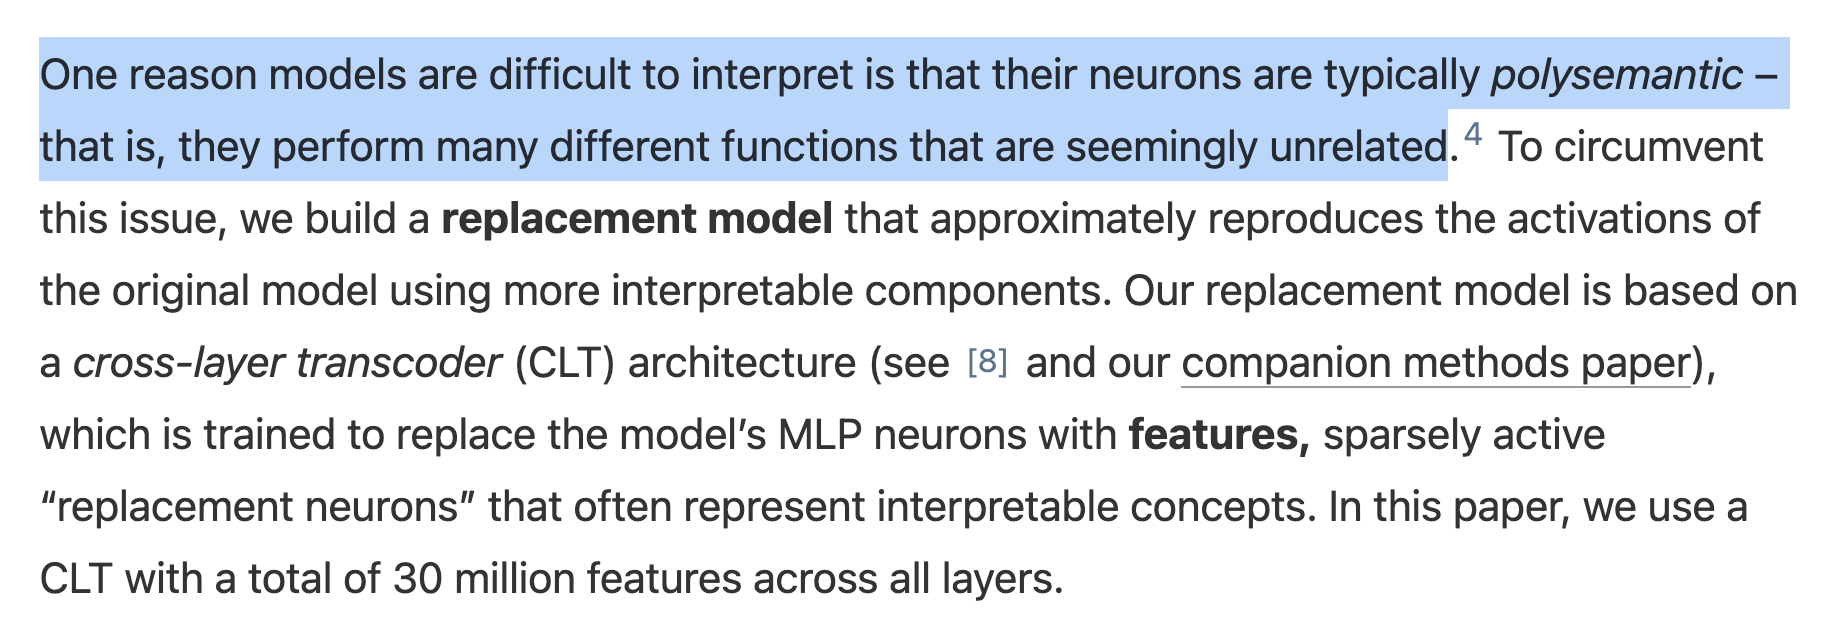
But it's much harder than simply observing individual neuron activations, because of superposition: a single neuron participates in many unrelated concepts, and any given concept is smeared across many neurons. You can't just read meaning off one unit. You need to get creative.
Circuit tracing
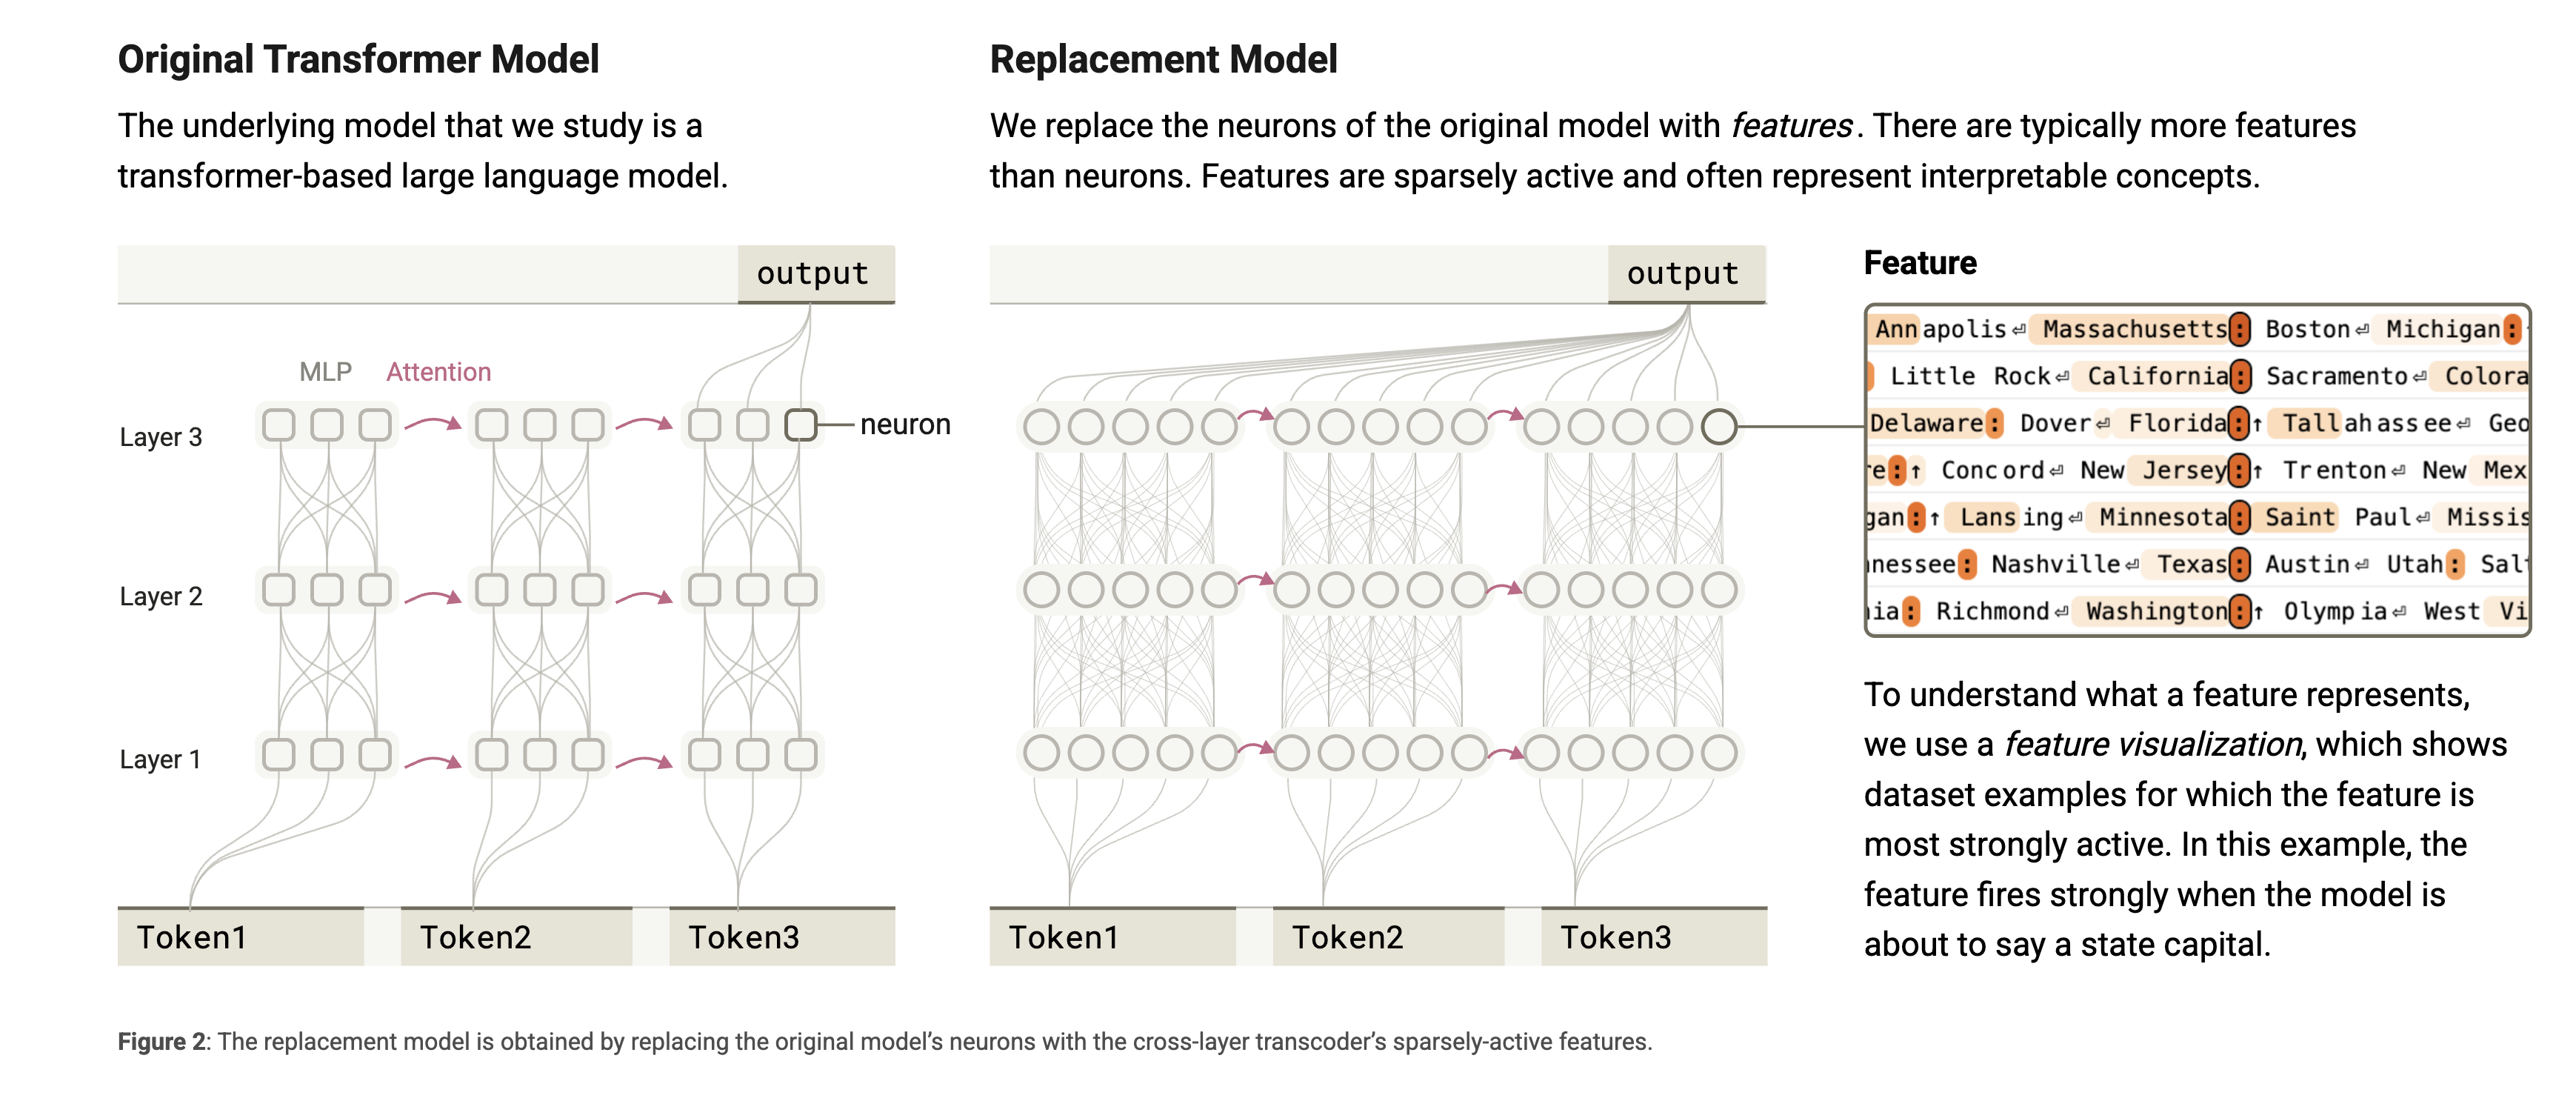
One approach: train a second model to identify discrete concepts, then monitor how those concepts interact over the course of a forward pass.
Anthropic's circuit tracing technique trains a "replacement" model to sparsely recreate the outputs of the base model's MLP layers. This effectively decomposes the base model's activations into a set of sparse features — and it turns out these features correspond to high-level concepts that humans can readily identify, like "Texas" or "the Olympics."
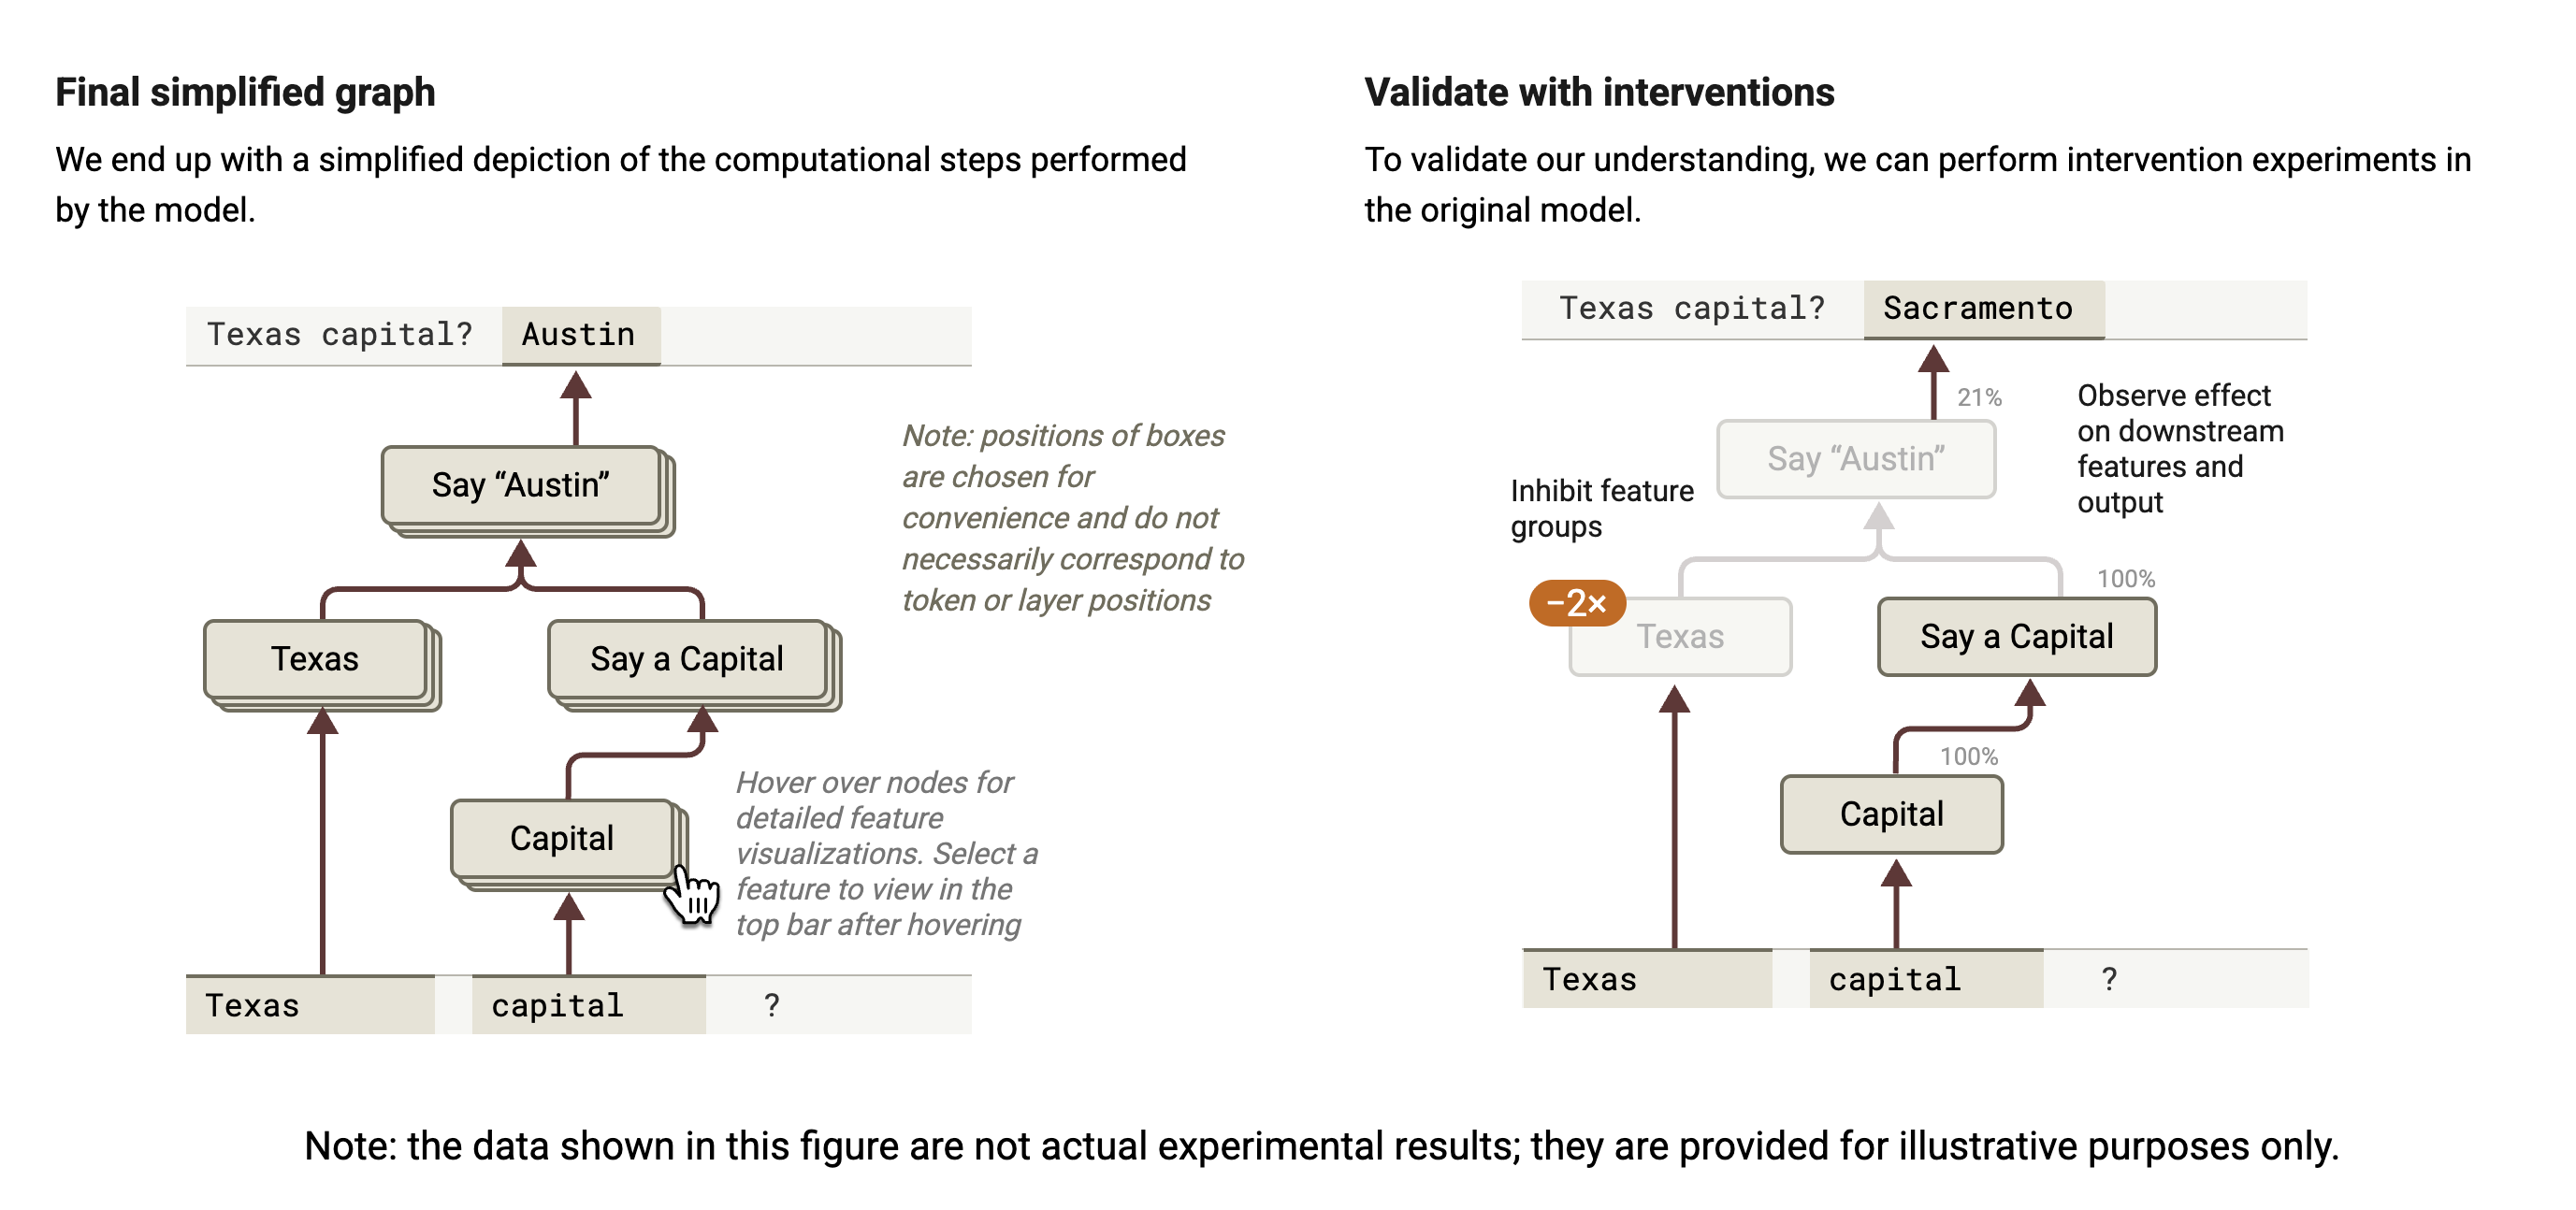
Once you have these human-interpretable features, you can group them into causally-linked clusters by tracing how they interact during the forward pass — building up a wiring diagram of the computation.
Models really do reason in multiple steps
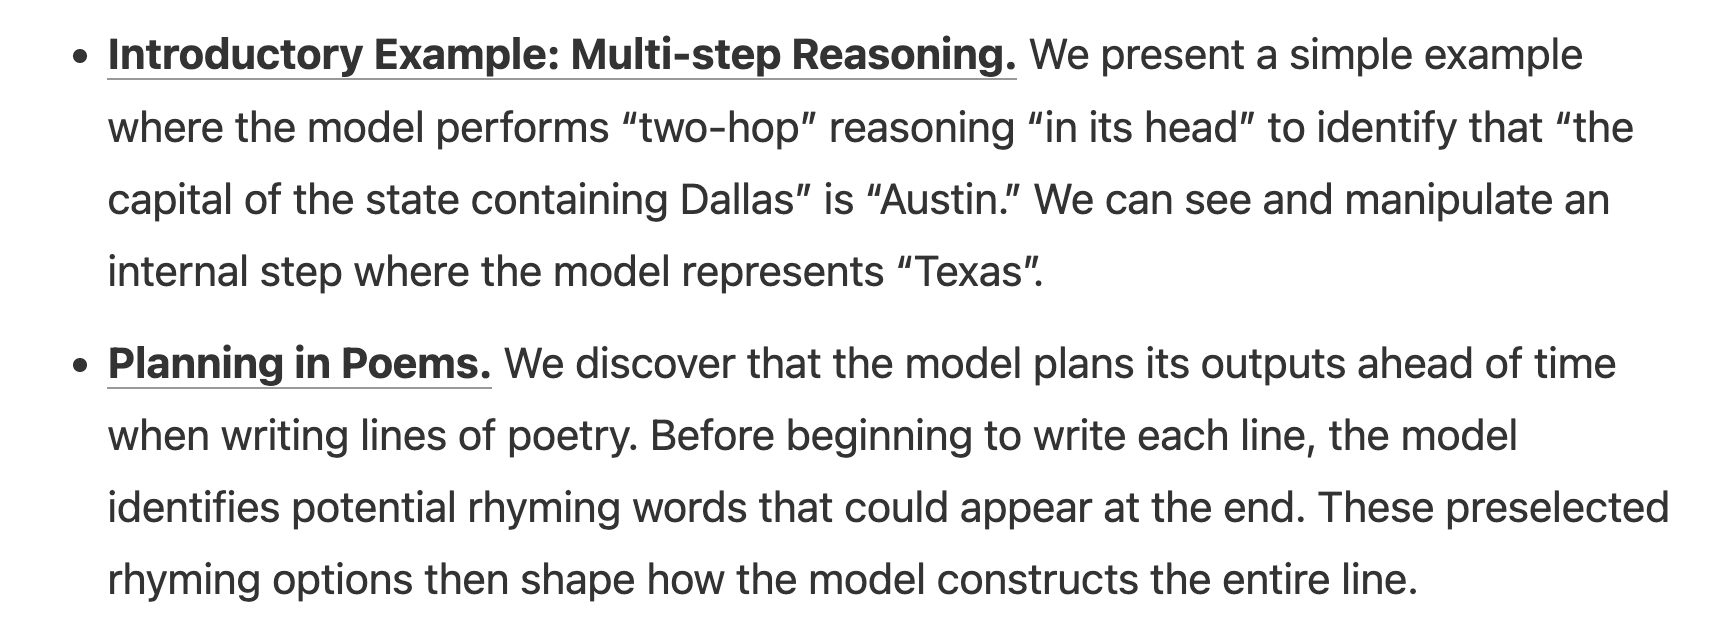
When you run this in practice, you can watch models engage in genuine multi-step reasoning via intermediary concepts. The model will even "think ahead" to future rhyme candidates when planning a poem.
Ask it "what is the capital of the state containing Dallas" and you can observe, in order:
- the Dallas feature goes active,
- which causes the Texas feature to light up,
- which then causes Austin to light up.
It seems fairly clear that this is tracing semantic relationships between high-level concepts — and in doing so, performing a kind of pseudo-symbolic inference, similar to what some philosophers would describe as "higher reasoning."
This isn't unique to LLMs
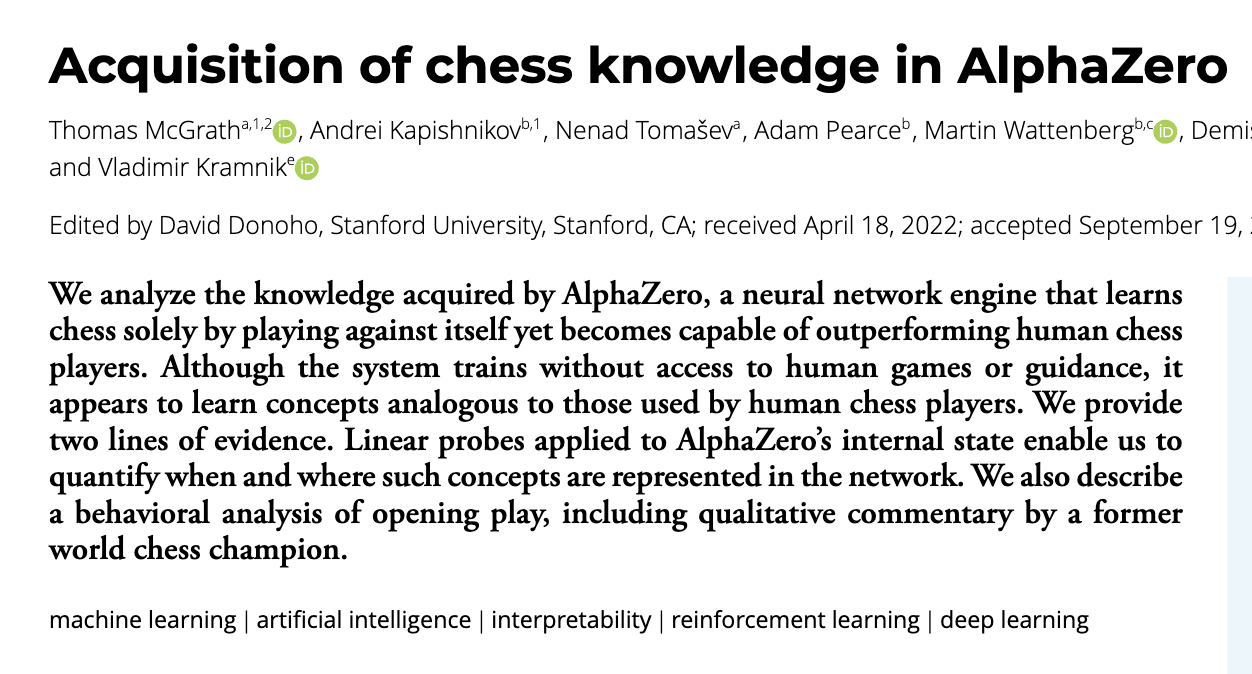
This phenomenon doesn't only apply to language models. MCTS-based systems like AlphaZero also converge on concepts that humans recognize.
DeepMind (2022) showed that AlphaZero learned intermediary representations aligning with human chess concepts such as "in check" and "pinning a piece" — entirely on its own, with no human chess knowledge supplied.
Better understanding → better algorithms
Breaking down a model's implicit reasoning can help us design better learning algorithms.
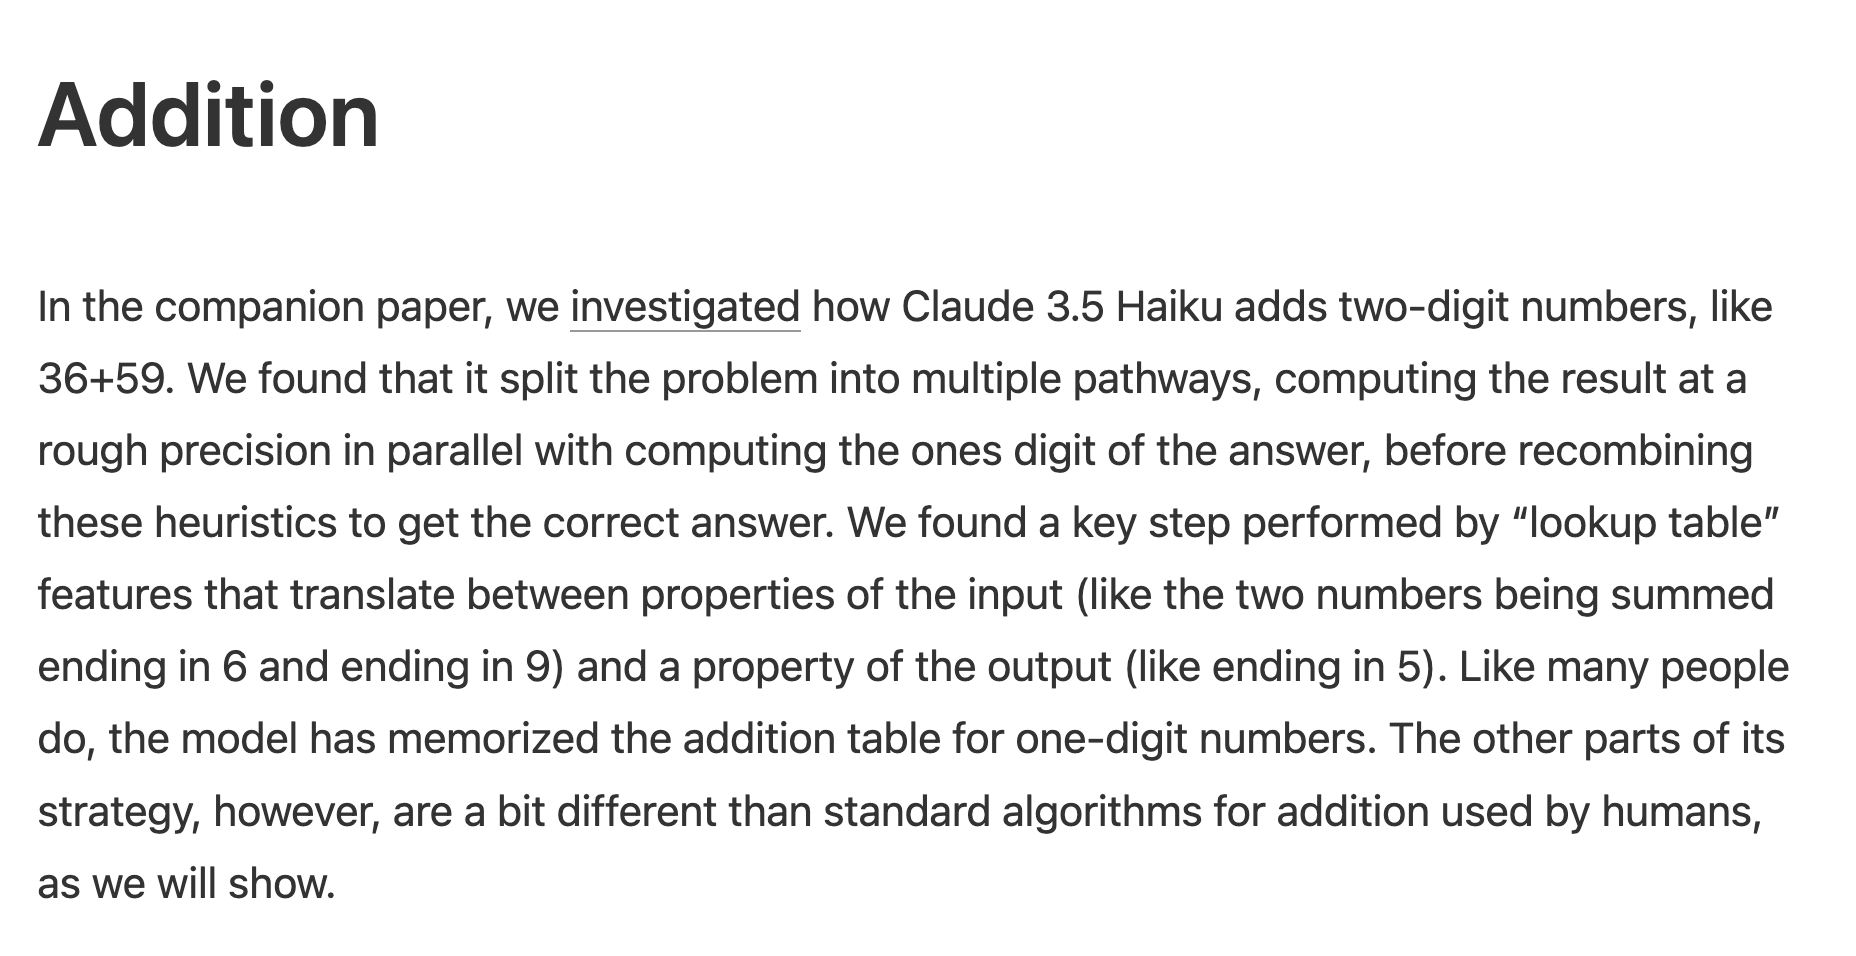
For example: Claude 3.5 Haiku learned an algorithm for small-integer addition that does not cleanly map to human mental math. It splits the problem into multiple parallel pathways — computing a rough magnitude alongside the precise ones-digit — and recombines them, leaning on memorized "lookup table" features.
The natural question follows: can we identify this, then "guide" the model toward a better algorithm?
The model has a "subconscious"
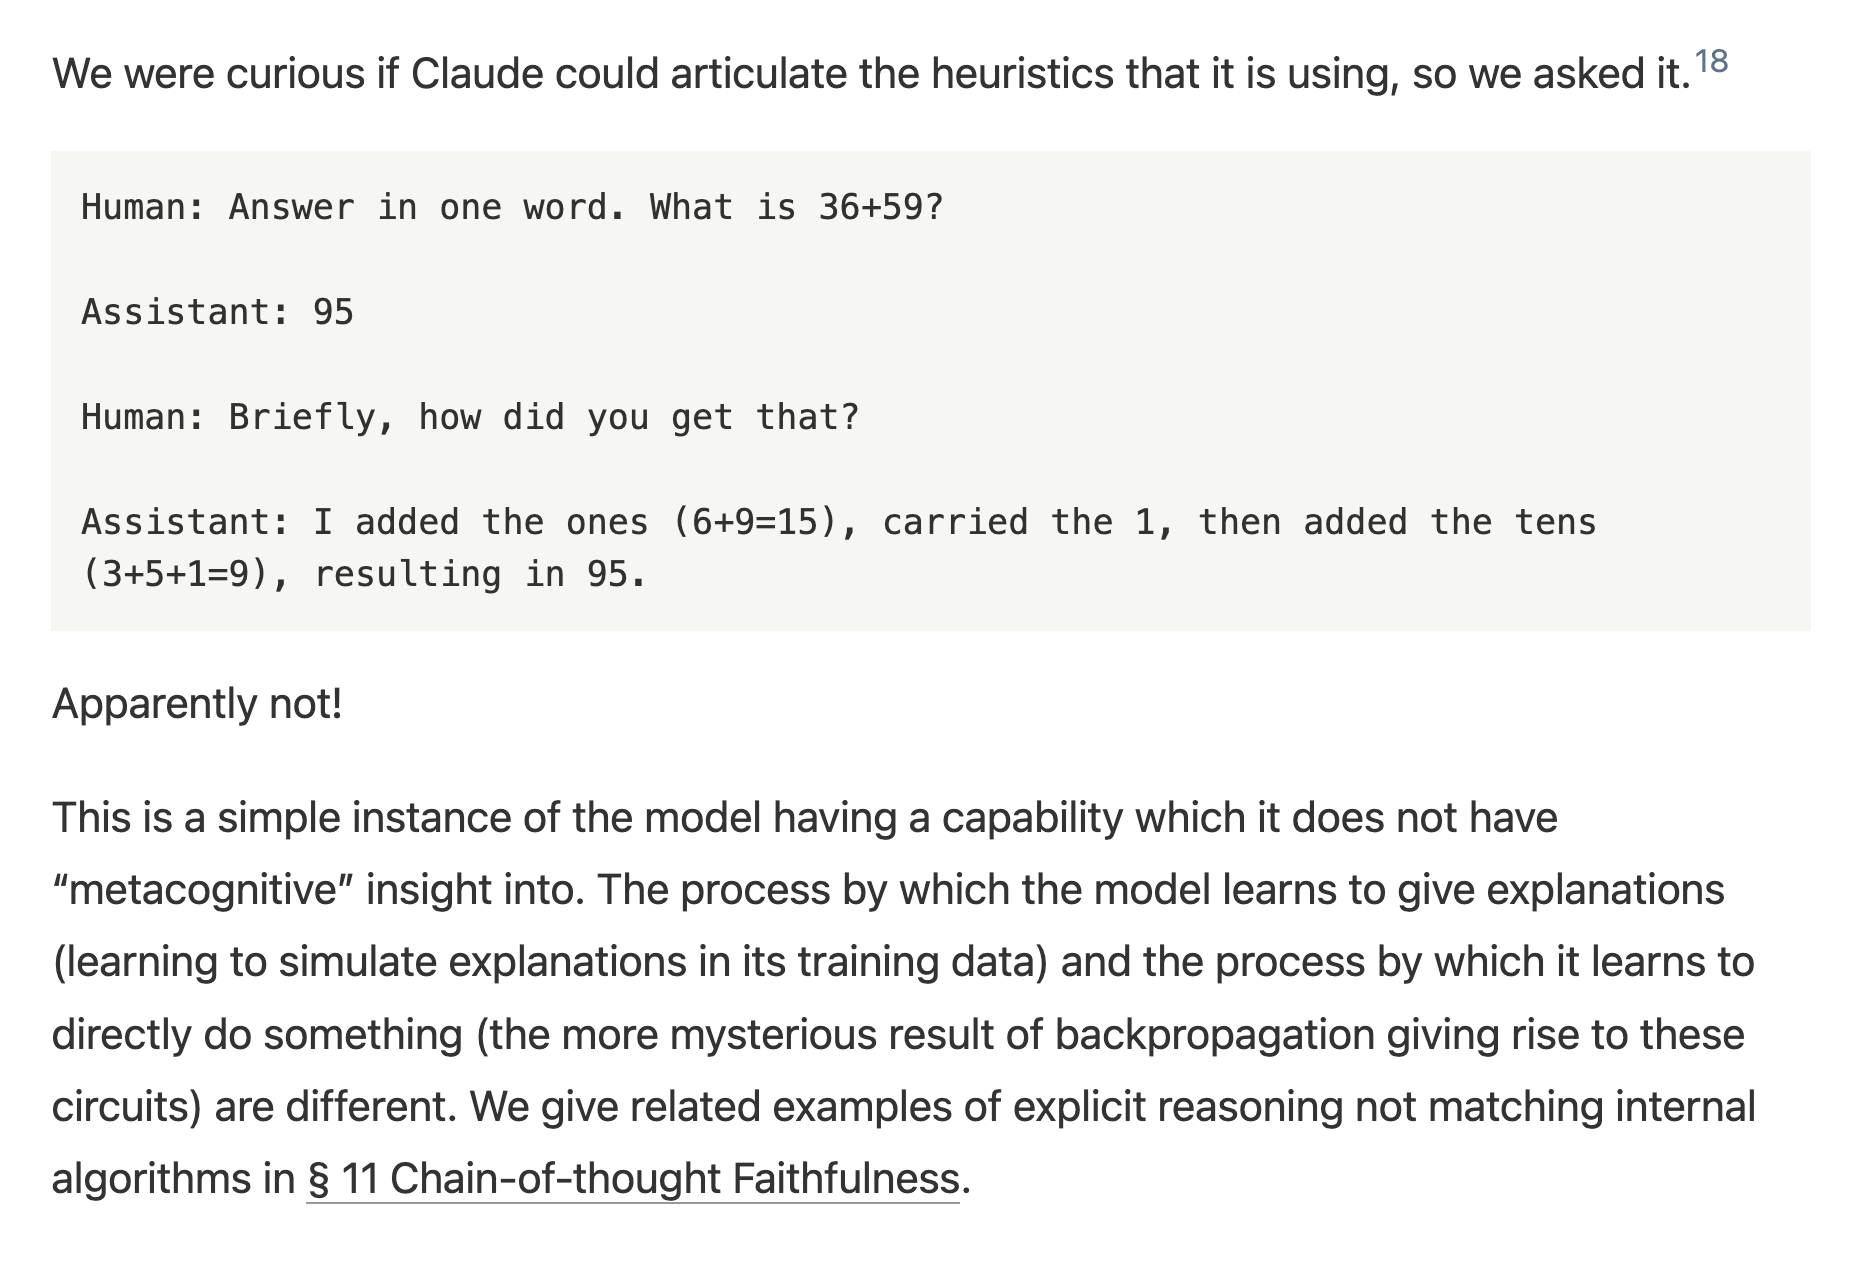
It's worth noting that the model itself does not necessarily have metacognitive insight into the underlying thinking process uncovered by circuit tracing. Ask it to explain how it added two numbers and it will narrate a tidy, human-style procedure — which is not the algorithm it actually ran.
For better or worse, the model has some level of subconscious. And that's precisely what lets us peer in.
Why this matters
Mechanistic interpretability is a fascinating, fast-developing line of work with major Ws on the scoreboard.
Contrary to what your ML professor may have told you a decade ago, in some ways this is now the most insight we've ever extracted from a model. And the implications are significant — for identifying model misbehavior, for steering, and even for designing better learning algorithms.
For the original thread, see the post on X. For the full research, read Anthropic's paper.
Jay Hack