







By using Multi-Token Prediction (MTP) drafters, Gemma 4 models reduce latency bottlenecks and achieve improved responsiveness for developers.
Maarten Grootendorst
Developer Relations Engineer
Your browser does not support the audio element.
Listen to article
This content is generated by Google AI. Generative AI is experimental
[[duration]] minutes
Just a few weeks ago, we introduced Gemma 4, our most capable open models to date. With over 60 million downloads in just the first few weeks, Gemma 4 is delivering unprecedented intelligence-per-parameter to developer workstations, mobile devices and the cloud. Today, we are pushing efficiency even further.
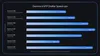
We’re releasing Multi-Token Prediction (MTP) drafters for the Gemma 4 family. By using a specialized speculative decoding architecture, these drafters deliver up to a 3x speedup without any degradation in output quality or reasoning logic.
Tokens-per-second speed increases, tested on hardware using LiteRT-LM, MLX, Hugging Face Transformers, and vLLM.
Why speculative decoding?
The technical reality is that standard LLM inference is memory-bandwidth bound, creating a significant latency bottleneck. The processor spends the majority of its time moving billions of parameters from VRAM to the compute units just to generate a single token. This leads to under-utilized compute and high latency, especially on consumer-grade hardware.
Speculative decoding decouples token generation from verification. By pairing a heavy target model (e.g., Gemma 4 31B) with a lightweight drafter (the MTP model), we can utilize idle compute to “predict” several future tokens at once with the drafter in less time than it takes for the target model to process just one token. The target model then verifies all of these suggested tokens in parallel.
How speculative decoding works
Standard large language models generate text autoregressively, producing exactly one token at a time. While effective, this process dedicates the same amount of computation to predicting an obvious continuation (like predicting “words” after “Actions speak louder than…”) as it does to solving a complex logic puzzle.
MTP mitigates this inefficiency through speculative decoding, a technique introduced by Google researchers in Fast Inference from Transformers via Speculative Decoding. If the target model agrees with the draft, it accepts the entire sequence in a single forward pass —and even generates an additional token of its own in the process. This means your application can output the full drafted sequence plus one token in the time it usually takes to generate a single one.
Unlocking faster AI from the edge to the workstation
For developers, inference speed is often the primary bottleneck for production deployment. Whether you are building coding assistants, autonomous agents that require rapid multi-step planning, or responsive mobile applications running entirely on-device, every millisecond matters.
By pairing a Gemma 4 model with its corresponding drafter, developers can achieve:
- Improved responsiveness: Drastically reduce latency for near real-time chat, immersive voice applications and agentic workflows.
- Supercharged local development: Run our 26B MoE and 31B Dense models on personal computers and consumer GPUs with unprecedented speed, powering seamless, complex offline coding and agentic workflows.
- Enhanced on-device performance: Maximize the utility of our E2B and E4B models on edge devices by generating outputs faster, which in turn preserves valuable battery life.
- Zero quality degradation: Because the primary Gemma 4 model retains the final verification, you get identical frontier-class reasoning and accuracy, just delivered significantly faster.
Gemma 4 26B on a NVIDIA RTX PRO 6000. Standard Inference (left) vs. MTP Drafter (right) in tokens per second. Same output quality, half the wait time.
Where you can dive deeper into MTP drafters
To make these MTP drafters exceptionally fast and accurate, we introduced several architectural enhancements under the hood. The draft models seamlessly utilize the target model's activations and share its KV cache, meaning they don't have to waste time recalculating context the larger model has already figured out. For our E2B and E4B edge models, where the final logit calculation becomes a big bottleneck, we even implemented an efficient clustering technique in the embedder to further accelerate generation.
We've also been closely analyzing hardware-specific optimizations. For example, while the 26B mixture-of-experts model presents unique routing challenges at a batch size of 1 on Apple Silicon, processing multiple requests simultaneously (e.g., batch sizes of 4 to 8) unlocks up to a ~2.2x speedup locally. We see similar gains with Nvidia A100 when increasing batch size.
Want to see the exact mechanics of how this works? We’ve published an in-depth technical explainer that unpacks the visual architecture, KV cache sharing and efficient embedders powering these drafters.
How to get started
The MTP drafters for the Gemma 4 family are available today under the same open-source Apache 2.0 license as Gemma 4. Read the documentation to learn how to use MTP with Gemma 4. You can download the model weights right now on Hugging Face, Kaggle, and start experimenting with faster inference with transformers, MLX, VLLM, SGLang, and Ollama or try them directly on Google AI Edge Gallery for Android or iOS.
We can't wait to see how this newfound speed accelerates what you build next in the Gemmaverse.