

惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

D
DataBreaches.Net
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
云风的 BLOG
云风的 BLOG
B
Blog
博客园 - Franky
I
InfoQ
A
About on SuperTechFans
博客园_首页
L
LangChain Blog
量子位
腾讯CDC
Microsoft Security Blog
博客园 - 【当耐特】
美团技术团队
V
V2EX
Apple Machine Learning Research
雷峰网
雷峰网
MongoDB | Blog
MongoDB | Blog
Microsoft Azure Blog
月光博客
月光博客
T
The Blog of Author Tim Ferriss
P
Proofpoint News Feed
G
Google Developers Blog
Last Week in AI
Last Week in AI

Hacker News: Front Page

SPICE simulation → oscilloscope → verification with Claude Code — Lucas Gerads Introducing Claude Opus 4.7 Qwen Studio The Future of Everything is Lies, I Guess: Where Do We Go From Here? GitHub - SeanFDZ/macmind: Single-layer transformer in HyperTalk for the classic Macintosh Show HN: Agent-cache – Multi-tier LLM/tool/session caching for Valkey and Redis Ancient DNA reveals pervasive directional selection across West Eurasia [pdf] AI cybersecurity is not proof of work Moving a large-scale metrics pipeline from StatsD to OpenTelemetry / Prometheus GitHub - Nightmare-Eclipse/RedSun: The Red Sun vulnerability repository GitHub - SethPyle376/hiraeth: Local AWS emulator focused on fast integration testing, with SQS support, SQLite-backed state, and a debug-friendly web UI. A Better Ludum Dare; Or, How to Ruin a Legacy GitHub - macOS26/Agent: Any AI, replaces Claude Code, Cursor, OpenClaw. Over 18 LLM providers (Claude, OpenAI, Gemini, Ollama, Zai, HF, Qwen) wired into a native Mac app that writes code, builds Xcode projects, bumps versions, manages git, automates Safari, use AppleScript, JS or Accessibility, extend Agent! w/ MCP Servers, run tasks from your iPhone via Messages. YouTube now lets you turn off Shorts I Made a Terminal Pager Burgers | マクドナルド公式 Commands — HackerNews CLI documentation ChatGPT for Excel PiCore - Raspberry Pi Port of Tiny Core Linux Live Nation illegally monopolized ticketing market, jury finds Google Broke Its Promise to Me. Now ICE Has My Data. Founding Engineer at Adaptional | Y Combinator CRISPR takes important step toward silencing Down syndrome’s extra chromosome GitHub - saffron-health/libretto: The AI toolkit for building reliable browser automations US v. Heppner (S.D.N.Y. 2026) no attorney-client privilege for AI chats [pdf] Unexpected €54k billing spike in 13 hours: Firebase browser key without API restrictions used for Gemini requests Fragments: April 14 Cal.com Goes Closed Source: Why AI Security Is Forcing Our Decision | Cal.com - Scheduling Software for Online Bookings Laravel raised money and now injects ads directly into your agent Codex Hacked a Samsung TV
The 100,000 whys of AI
lcamtuf · 2026-06-21 · via Hacker News: Front Page

One of the most painful arguments I keep having with fellow techies is the question of whether you can distinguish between human-written and AI-generated text.

Their skepticism is rooted in reason: at their core, LLMs are state-of-the-art statistical models of how humans talk. If so, the output from the model should be almost by definition indistinguishable from human language under any statistical test.

I don’t think this is always argued in good faith; at least some of the debates are started by folks who wish to maintain deniability for their own underhanded use of the tech. But if you sincerely hold this belief, I present you the following collage:
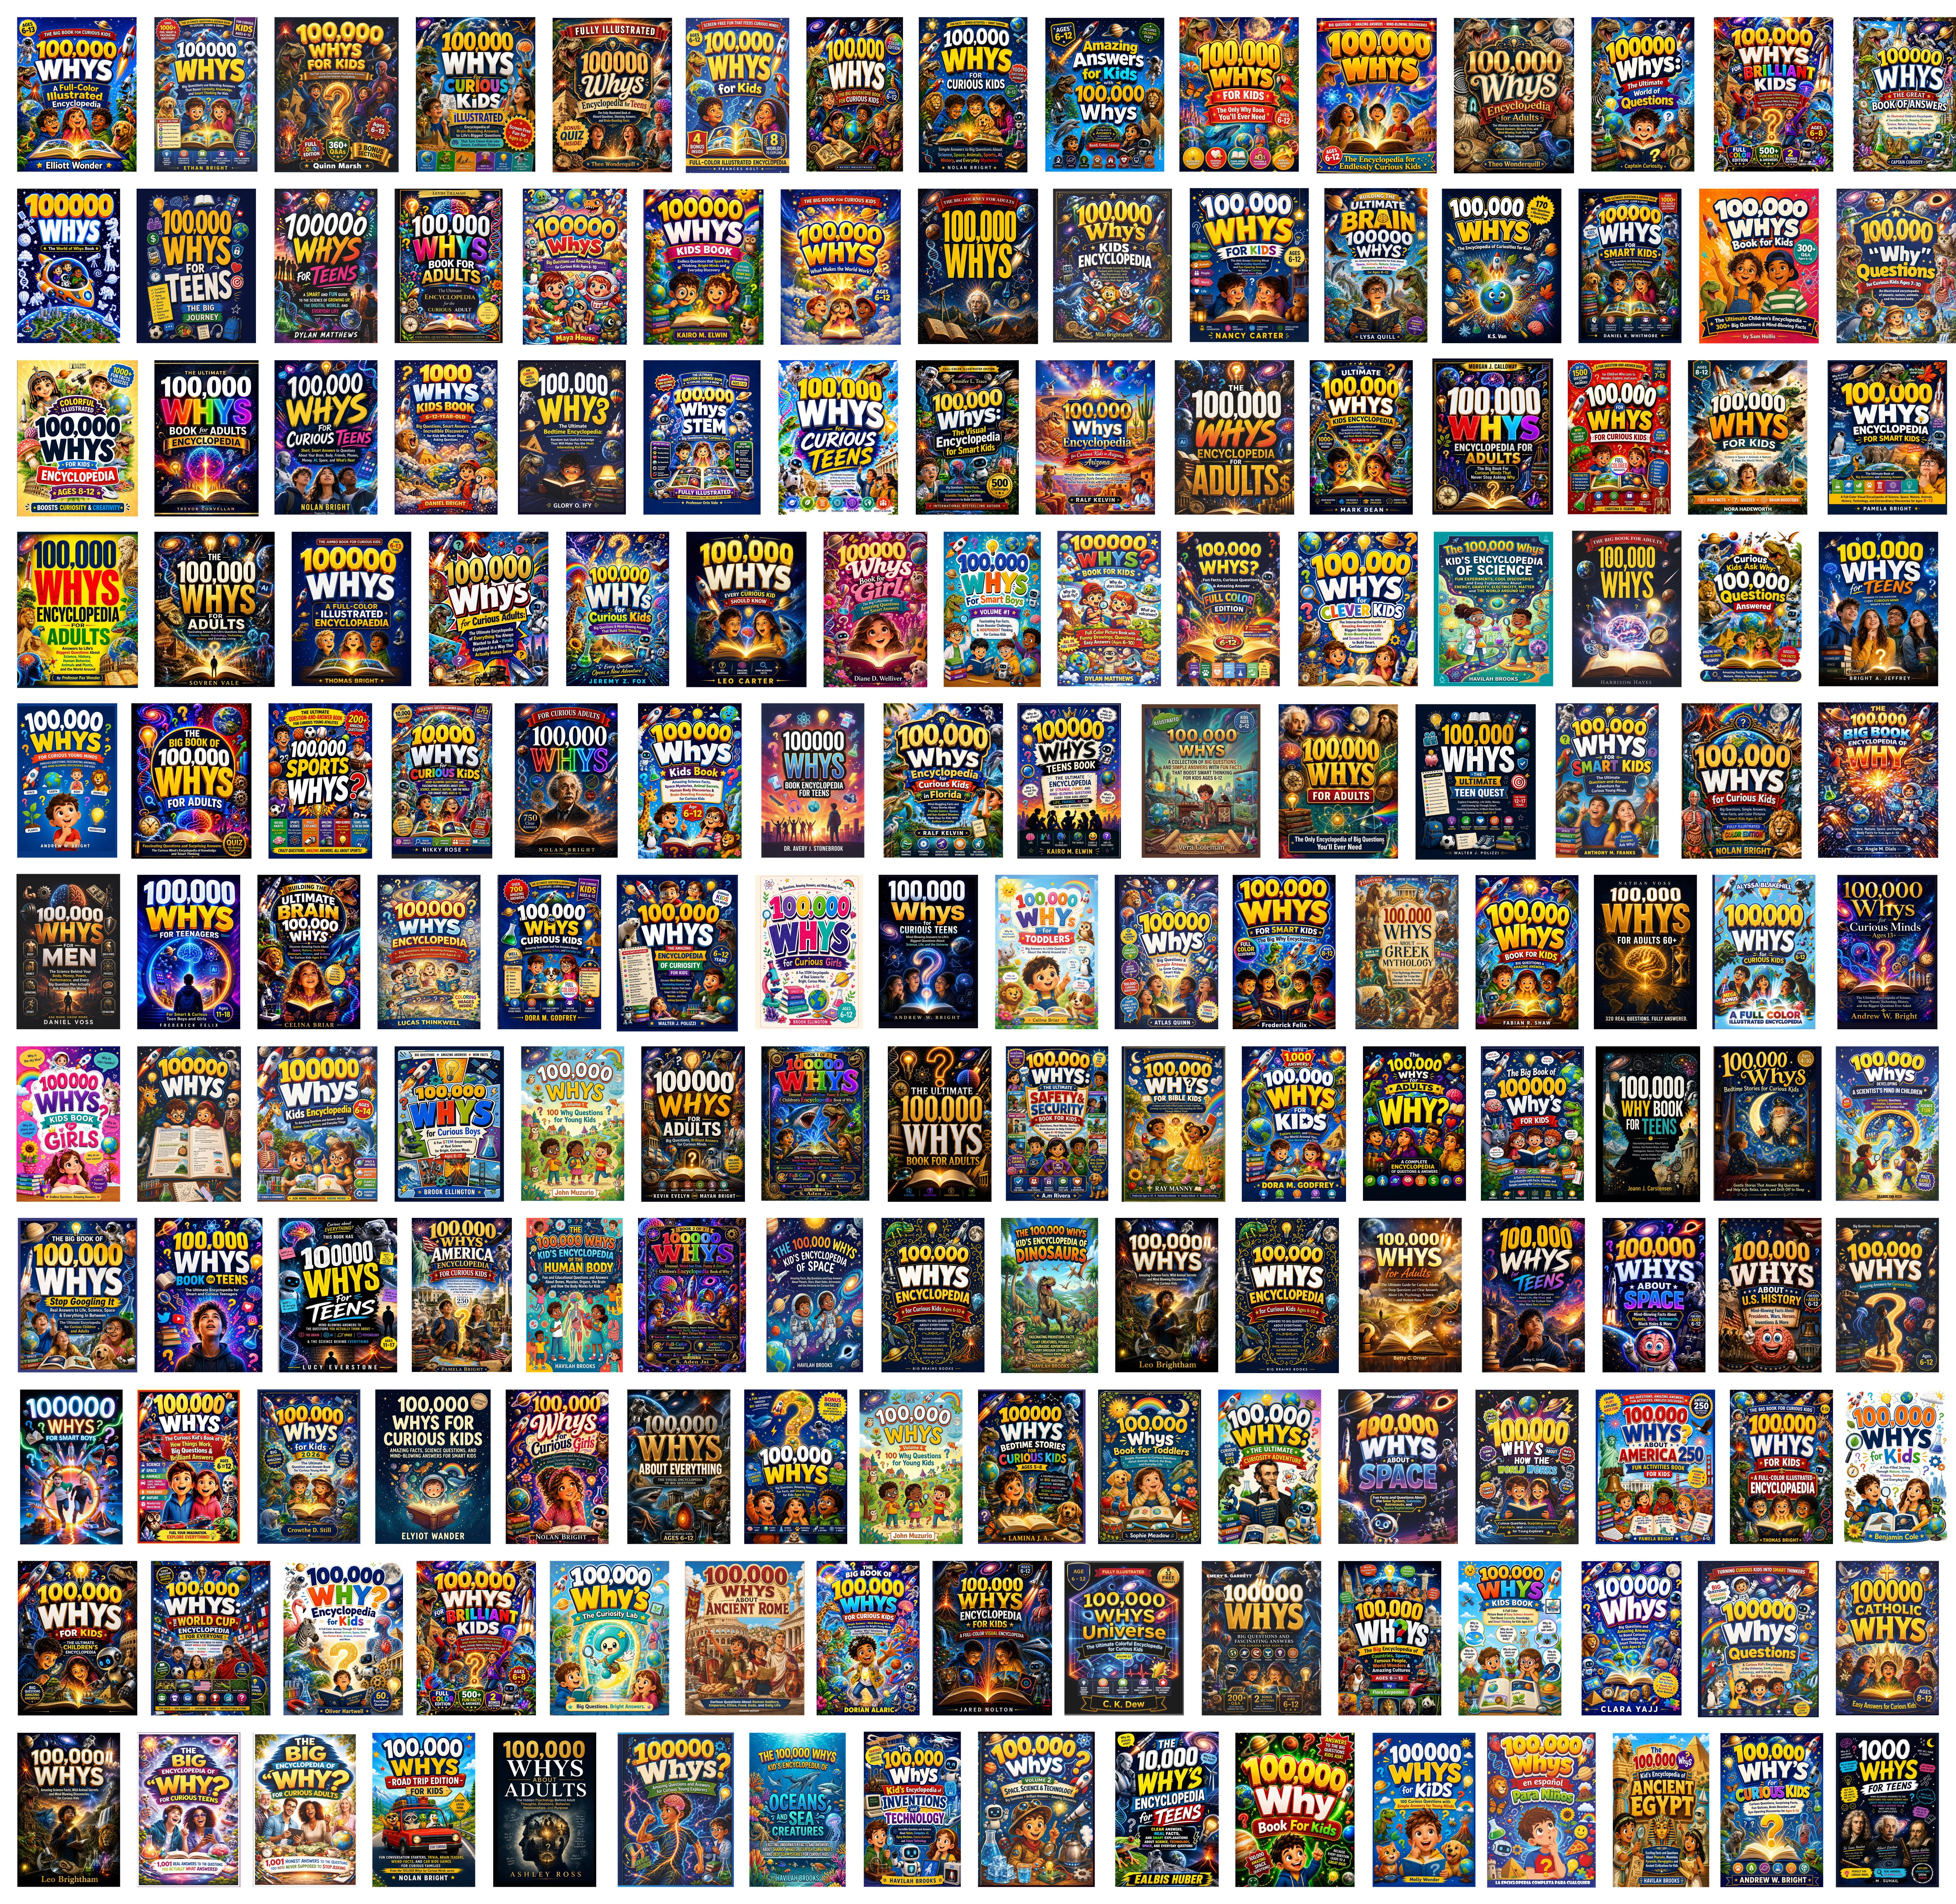
The image shows about 150 Amazon book covers that appear if you search the site for “100000 whys” (link). Some of these books are category bestsellers in children literature. You can view a zoomable, full-resolution version here.

There’s nothing inhuman about any of these titles or covers. At the same time, I probably don’t need to convince you that you’re staring at the purest form of AI slop that is now the scourge of many non-fiction book categories on Amazon. What we’re seeing here is the artifact of LLMs being quasi-deterministic: if you give them the same prompt — say, “generate a reference book for children” — they will produce functionally identical output perhaps 80% of the time.

The similarities in the collage go far beyond the choice of titles: for example, all the covers in the top row feature a roaring dinosaur in the top left corner of the design. There are many other clusters in the data, too. Look for a recurring red-and-white cartoon rocket, a golden retriever, a lion, and so forth.

This is precisely what makes LLM writing distinctive: it’s not that the models’ individual mannerisms are different from ours. It’s that they resort to the same, complex set of mannerisms in response to almost any normal prompt. This is a fuzzy signal, so you shouldn’t fire your intern when they say “it’s not this — it’s that”. But in more casual settings, it’s OK to trust your gut. In fact, these instincts are becoming increasingly important because traditional models of online interactions fall apart if it takes much less effort to produce content than to engage with it.

PS. If you’re using an LLM to automate blogging: yes, the tech is amazing, but chances are, your publication could be renamed to “100,000 Whys”.

Discussion about this post

Ready for more?