







We are releasing Roboschool: open-source software for robot simulation, integrated with OpenAI Gym.
Roboschool ships with twelve environments, including tasks familiar to Mujoco users as well as new challenges, such as harder versions of the Humanoid walker task, and a multi-player Pong environment. We plan to expand this collection over time and look forward to the community contributing as well.
For the existing MuJoCo environments, besides porting them to Bullet, we have modified them to be more realistic. Here are three of the environments we ported, with explanations of how they differ from the existing environments.
You can find trained policies for all of these environments in the [agent_zoo](https://github.com/openai/roboschool/tree/master/agent_zoo) folder in the GitHub repository. You can also access a [demo_race](https://github.com/openai/roboschool/blob/master/agent_zoo/demo_race2.py) script to initiate a race between three robots.
In several of the previous OpenAI Gym environments, the goal was to learn a walking controller. However, these environments involved a very basic version of the problem, where the goal is simply to move forward. In practice, the walking policies would learn a single cyclic trajectory and leave most of the state space unvisited. Furthermore, the final policies tended to be very fragile: a small push would often cause the robot to crash and fall.
We have added two more environments with the 3D humanoid, which make the locomotion problem more interesting and challenging. These environments require interactive control — the robots must run towards a flag, whose position randomly varies over time.
HumanoidFlagrun is designed to teach the robot to slow down and turn. The goal is to run towards the flag, whose position varies randomly.
HumanoidFlagrunHarder in addition allows the robot to fall and gives it time to get back on foot. It also starts each episode upright or laying on the ground, and the robot is constantly bombarded by white cubes to push it off its trajectory.
We ship trained policies for both
HumanoidFlagrun(opens in a new window) and HumanoidFlagrunHarder(opens in a new window). The walks aren’t as fast and natural-looking as the ones we see from the regular humanoid, but these policies can recover from many situations, and they know how to steer. This policy itself is still a multilayer perceptron, which has no internal state, so we believe that in some cases the agent uses its arms to store information.
Roboschool lets you both run and train multiple agents in the same environment. We start with RoboschoolPong, with more environments to follow.
With multiplayer training, you can train the same agent playing for both parties (so it plays with itself), you can train two different agents using the same algorithm, or you can even set two different algorithms against each other.
The multi-agent setting presents some interesting challenges. If you train both players simultaneously, you’ll likely see a learning curve like the following one, obtained from a policy gradient method:
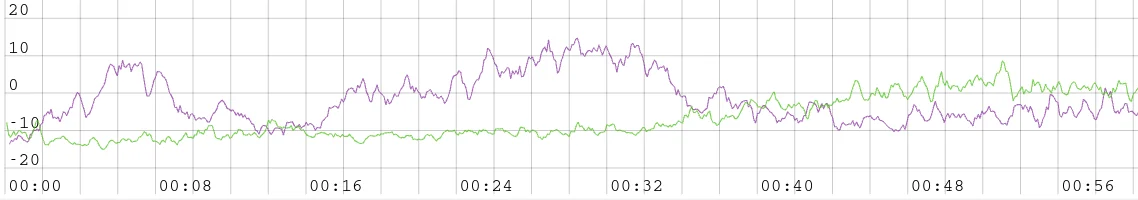
Learning curves for pong, where policies are updated with policy gradient algorithms running simultaneously.
Here’s what’s happening:
- Agent1 (green) learns it can sometimes hit a ball at the top, so it moves to the top.
- Agent2 (purple) discovers that its adversary is at the top, so it sends the ball to the bottom and overfits to other agent being away.
- Agent1 eventually discovers it can defend itself by moving to the bottom, but now always stay at the bottom, because Agent2 always sends ball to the bottom.
That way, the policies oscillated, and neither agent learned anything useful after hours of training. As in generative adversarial networks, learning in an adversarial setting is tricky, but we think it’s an interesting research problem because this interplay can lead to sophisticated strategies even in simple environments, and it can provide a natural curriculum.