


We’ve observed agents discovering progressively more complex tool use while playing a simple game of hide-and-seek. Through training in our new simulated hide-and-seek environment, agents build a series of six distinct strategies and counterstrategies, some of which we did not know our environment supported. The self-supervised emergent complexity in this simple environment further suggests that multi-agent co-adaptation may one day produce extremely complex and intelligent behavior.
In our environment, agents play a team-based hide-and-seek game. Hiders (blue) are tasked with avoiding line-of-sight from the seekers (red), and seekers are tasked with keeping vision of the hiders. There are objects scattered throughout the environment that hiders and seekers can grab and lock in place, as well as randomly generated immovable rooms and walls that agents must learn to navigate. Before the game begins, hiders are given a preparation phase where seekers are immobilized to give hiders a chance to run away or change their environment.
There are no explicit incentives for agents to interact with objects in the environment; the only supervision given is through the hide-and-seek objective. Agents are given a team-based reward; hiders are given a reward of +1 if all hiders are hidden and -1 if any hider is seen by a seeker. Seekers are given the opposite reward, -1 if all hiders are hidden and +1 otherwise. To confine agent behavior to a reasonable space, agents are penalized if they go too far outside the play area. During the preparation phase, all agents are given zero reward.
As agents train against each other in hide-and-seek, as many as six distinct strategies emerge. Each new strategy creates a previously nonexistent pressure for agents to progress to the next stage. Note that there are no direct incentives for agents to interact with objects or to explore; rather, the emergent strategies shown below are a result of the autocurriculum(opens in a new window) induced by multi-agent competition and the simple dynamics of hide-and-seek.
We use the same training infrastructure and algorithms used to train OpenAI Five and Dactyl. However, in our environment each agent acts independently, using its own observations and hidden memory state. Agents use an entity-centric state-based representation of the world, which is permutation invariant with respect to objects and other agents.
Each object is embedded and then passed through a masked residual self attention block, similar to those used in transformers(opens in a new window), where the attention is over objects instead of over time. Objects that are not in line-of-sight and in front of the agent are masked out such that the agent has no information of them.
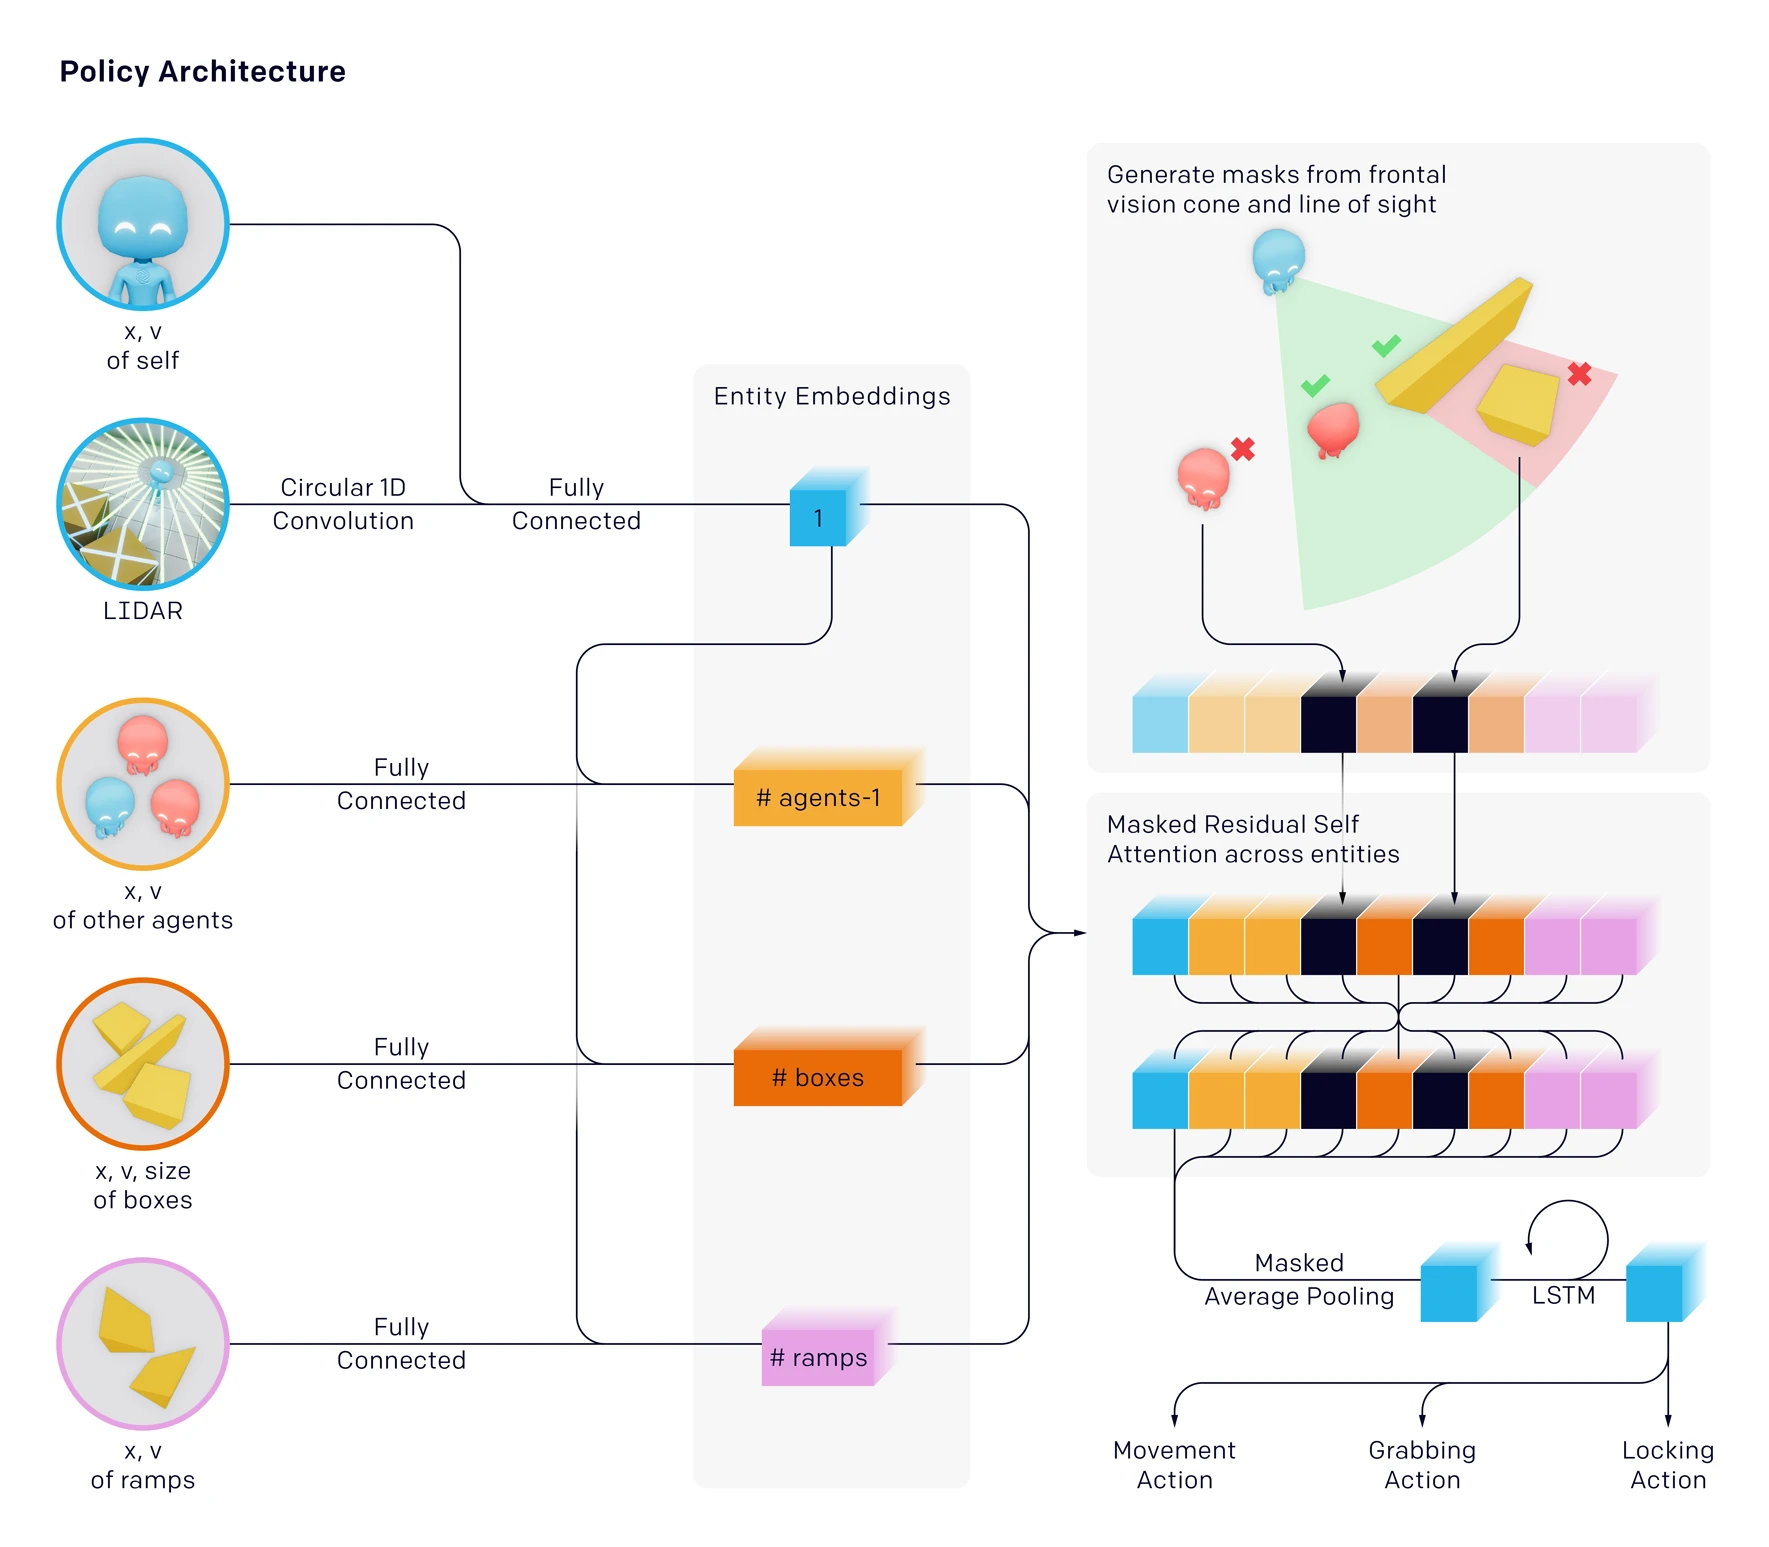
Agent policies are trained with self-play and Proximal Policy Optimization. During optimization, agents can use privileged information about obscured objects and other agents in their value function.
We found that large scale training was critical in agents progressing through the various stages of emergence. Below we show both the time and number of episodes it takes agents to reach stage 4 (ramp defense) for various batch sizes. We find increasing batch size gives a drastic speedup in wall-clock time to convergence, though doesn’t affect the sample efficiency greatly at or above 32k. However, we found that batch sizes of 8k and 16k never reached stage 4 in the allotted number of episodes.
In this work we show evidence that agents learn complex strategies and counterstrategies through a self-supervised autocurriculum in hide-and-seek. Another method to learn skills in an unsupervised manner is intrinsic motivation, which incentivizes agents to explore with various metrics such as model error or state counts. We ran count-based exploration in our environment, in which agents keep an explicit count of states they’ve visited and are incentivized to go to infrequently visited states. The primary modeling choice to tune in this setting is the state representation; for instance, in our first baseline we only include 2-D box positions in the state, such that agents are only incentivized to interact with and move boxes to novel positions. We then compare this to a count-based policy which takes the full state given to the agents that play hide-and-seek.
As can be seen, agents trained in hide-and-seek qualitatively center around far more human interpretable behaviors such as shelter construction, whereas agents trained with intrinsic motivation move objects around in a seemingly undirected fashion. Furthermore, as the state space increases in complexity, we find that intrinsic motivation methods have less and less meaningful interactions with the objects in their environment. For this reason, we believe multi-agent competition will be a more scalable method for generating human-relevant skills in an unsupervised manner as environments continue to increase in size and complexity.
In the previous section, we qualitatively compare behaviors learned in hide-and-seek to those learned with intrinsic motivation. However, as environments increase in scale, so will the difficulty in qualitatively measuring progress. Tracking reward is an insufficient evaluation metric in multi-agent settings, as it can be ambiguous in indicating whether agents are improving evenly or have stagnated. Metrics like ELO or Trueskill can more reliably measure whether performance is improving relative to previous policy versions or other policies in a population; however, these metrics still do not give insight into whether improved performance is caused by new adaptations or improving previously learned skills. Finally, using environment-specific statistics such as object movement can also be ambiguous (for example, the choice to track absolute movement does not illuminate which direction agents moved), and designing sufficient metrics will become difficult and costly as environments scale.
We propose using a suite of domain-specific intelligence tests that target capabilities we believe agents may eventually acquire. Transfer performance in these settings can act as a quantitative measure of representation quality or skill, and we compare against pretraining with count-based exploration as well as a trained from scratch baseline.
Though the hide-and-seek agent performs better on many of the transfer tasks, it does not drastically improve performance or convergence time. From viewing its behavior, we know it has the latent skill to move objects in a precise manner to construct shelter in the hide-and-seek game; however, it does not have the capability to use this skill in other contexts when trained with a low number of samples.
We believe the cause for the mixed transfer results is rooted in agents learning skill representations that are entangled and difficult to fine-tune. As future environments become more diverse and agents must use skills in more contexts, we believe we will see more generalizable skill representations and more significant signal in this evaluation approach. We additionally open-source the evaluation tasks as a way to evaluate learning progress in our environment.
We’ve shown that agents can learn sophisticated tool use in a high fidelity physics simulator; however, there were many lessons learned along the way to this result. Building environments is not easy and it is quite often the case that agents find a way to exploit the environment you build or the physics engine in an unintended way.