





Our newest open experimental model delivers up to 4x faster inference on dedicated GPUs and opens the door to exploring speed-critical, interactive local workflows.
Sebastian Flennerhag
Research Scientist
Today, we’re introducing DiffusionGemma, an experimental open model that explores text diffusion, an exceptionally fast approach to text generation. Released under an Apache 2.0 license, this 26B Mixture of Experts (MoE) model moves beyond the sequential token-by-token processing of typical autoregressive Large Language Models (LLMs). Instead, it generates entire blocks of text simultaneously, delivering up to 4x faster text generation on GPUs.
Built upon the industry-leading intelligence-per-parameter of our Gemma 4 family and cutting-edge Gemini Diffusion research, DiffusionGemma integrates a novel diffusion head designed to maximize generation speed. While autoregressive Gemma 4 models remain the standard for high-quality production outputs, DiffusionGemma is designed for researchers and developers exploring speed-critical, interactive local workflows such as in-line editing, rapid iteration, and generating non-linear text structures.
Unlocking new value for developers
Developers building real-time interactive AI applications often struggle with the latency bottlenecks of local inference. DiffusionGemma addresses these challenges directly, with some key trade-offs:
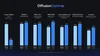
- Blazing fast inference: By shifting the decode bottleneck from memory-bandwidth to compute, DiffusionGemma generates up to 4x faster token output on dedicated GPUs. (1000+ tokens per second on a single NVIDIA H100, 700+ tokens per second on NVIDIA GeForce RTX 5090). 1
- Accessible hardware footprint: Operating as a 26B total Mixture of Experts (MoE) model that activates only 3.8B parameters during inference, DiffusionGemma fits comfortably within 18GB VRAM limits of high-end dedicated consumer GPUs when quantized.
- Bi-directional attention: Generating 256 tokens in parallel with each forward pass allows every token to attend to all others. This provides significant advantages for non-linear domains such as in-line editing, code infilling, amino acid sequences or mathematical graphs.
- Intelligent self-correction: The model iteratively refines its own output, allowing it to evaluate the entire text block at once to fix mistakes in real-time.
- Experimental status & production recommendations: Because it prioritizes speed and parallel layout generation, DiffusionGemma’s overall output quality is lower than standard Gemma 4. For applications that demand maximum quality, we recommend deploying standard Gemma 4.
You can improve DiffusionGemma's performance on specific tasks through fine-tuning. In the example below, Unsloth fine-tuned DiffusionGemma to play Sudoku — a task autoregressive models struggle with because each token depends on future tokens. DiffusionGemma's bi-directional attention makes this much easier.
Fine-tuned DiffusionGemma solving Sudoku.

Why diffusion for text?
While the AI research community has explored diffusion-based text generation for years, applying it to large models has remained a challenge. DiffusionGemma changes this by shifting how models use hardware.
The trade-off with traditional models
Most language models act like a typewriter, generating one token at a time from left to right. In the cloud, this is efficient because servers can batch thousands of user requests together to share the hardware load. But when run locally for a single user, this word-by-word process leaves your dedicated GPU or TPU underutilized — it spends most of its time simply waiting for the next "keystroke."
DiffusionGemma reverses this inefficiency. Instead of predicting words sequentially, it drafts an entire 256-token paragraph simultaneously. By giving the computer's processor a larger chunk of work at once, DiffusionGemma utilizes your hardware to its full potential. It upgrades your model inference from a single, sequential typewriter to a massive printing press that stamps the entire block of text simultaneously.
DiffusionGemma text-to-3D SVG demo by Hugging Face. Step-by-step generation.
This means DiffusionGemma's speedup is designed for local and low-concurrency inference. In high-QPS cloud serving, autoregressive models can be deployed to saturate compute efficiently, so DiffusionGemma's parallel decoding offers diminishing returns and can result in higher serving costs. The throughput advantage is strongest at low-to-medium batch sizes on a single accelerator.
How text diffusion works
Similar to AI image generators that start with visual static and iteratively refine it into a clear picture, DiffusionGemma applies this to text:
- The canvas: The model starts with a canvas of random placeholder tokens.
- Iterative refinement: The model makes multiple passes, locking in correct tokens and using them as context clues to refine the rest.
- Final polish: The text converges into high-quality output.
Because the model can process the whole paragraph while generating, it unlocks new patterns of model behavior, like perfectly closing complex markdown formatting or generating and rendering code in near real-time.
Get started today
- Download the weights: Access the experimental model weights (released under a permissive Apache 2.0 license) right now on Hugging Face.
- Integrate & learn: Learn more in our DiffusionGemma developer guide. Or deep dive into A Visual Guide to DiffusionGemma to understand the mechanics under the hood.
- Use your favorite development tools: Serve the model efficiently using MLX, vLLM (with integration supported by Red Hat), and Hugging Face Transformers. For rapid experimentation, we are releasing a fine-tuning tutorial using Hackable Diffusion, a modular JAX toolbox designed for composability. You can also explore fine-tuning with Unsloth and NVIDIA NeMo. Additionally, official support for llama.cpp is arriving soon.
- Experience optimized performance: We worked with NVIDIA to optimize across their hardware stack, ensuring compatibility with consumer setups (quantized for GeForce RTX 5090 and 4090 GPUs) alongside high performance on enterprise systems (Hopper and Blackwell using advanced NVFP4 kernels), including NVIDIA DGX Spark and DGX Station for local deskside deployment, and RTX PRO for AI professionals. Native support for NVFP4 (4-bit floating-point) accelerates compute throughput, allowing the model to run at faster speeds with near-lossless accuracy.
- Try your way: Run on your desktop dedicated GPU or in the cloud through Gemini Enterprise Agent Platform Model Garden or NVIDIA NIM.