




Gemma 4 12B is designed to bring high-performance multimodal intelligence directly to your laptop, combining mobile-first efficiency with advanced reasoning.

Gus Martins
Product Manager, Google DeepMind
Your browser does not support the audio element.
Listen to article
This content is generated by Google AI. Generative AI is experimental
[[duration]] minutes
Today, we are introducing Gemma 4 12B, our latest model designed to bring agentic multimodal intelligence directly to laptops. Bridging the gap between our edge-friendly E4B and our more advanced 26B Mixture of Experts (MoE), Gemma 4 12B packages powerful capabilities inside a reduced memory footprint. It is also our first mid-sized model to feature native audio inputs.
Thanks to the developer community, Gemma 4 models have now crossed 150 million downloads. You’ve built everything from wearable robotic arms for physical assistance to enterprise-grade AI security. We're excited to see what you build with this latest addition.
Here’s an overview of what makes Gemma 4 12B unique:
- Novel unified architecture: No multimodal encoders. The vision and audio inputs flow directly into the LLM backbone.
- Advanced reasoning: Benchmark performance nearing our 26B model, unlocking powerful multi-step reasoning and agentic workflows.
- Laptop ready: Small enough to run locally with just 16GB of VRAM or unified memory.
- Open and accessible: Released under an Apache 2.0 license with support across the developer ecosystem.
- Drafter-ready: Gemma 4 12B comes equipped with Multi-Token Prediction (MTP) drafters to reduce latency.
Together, these features bring advanced multimodal capabilities to everyday hardware without sacrificing speed or reasoning. Let's now take a closer look at how Gemma 4 12B achieves this.
Run state-of-the-art agents locally
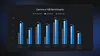
Gemma 4 12B delivers performance nearing our larger 26B MoE model on standard benchmarks, but at less than half the total memory footprint. Small enough to run locally on consumer laptops with 16GB of RAM, it unlocks powerful multimodal and agentic experiences right on your machine.
Experience a uniquely efficient, unified architecture
What makes Gemma 4 12B stand out is its streamlined approach to processing visual and audio inputs. Traditional multimodal models typically rely on separate encoders to translate images and audio before passing those representations to the language model. Because these split encoders add latency and increase memory usage, we trained Gemma 4 12B with an encoder-free architecture to integrate audio and vision input directly.
Here is how Gemma 4 12B processes multimodal inputs natively:
- Vision: We replaced Gemma 4’s vision encoder with a lightweight embedding module consisting of a single matrix multiplication, positional embedding and normalizations. This allows the LLM backbone to take over visual processing.
- Audio: We simplified audio processing even further. We removed the audio encoder entirely and projected the raw audio signal into the same dimensional space as text tokens.
For developers who want a breakdown, head over to our companion Gemma 4 12B Developer Guide.
Get started today
- Try it yourself: Experiment with a couple of clicks in LM Studio, Ollama, Google AI Edge Gallery App, the Google AI Edge Eloquent app and the LiteRT-LM CLI
- Download the weights: Download the pre-trained and instruction-tuned checkpoints directly from Hugging Face and Kaggle.
- Integrate & learn: Review the developer documentation and the quick start notebook.
- Use your favorite development tools: Implement local inference pipelines with Hugging Face Transformers, llama.cpp, MLX, SGLang, and vLLM, or fine-tune with efficiency using Unsloth.
- Unlock Agentic Development with Gemma Skills: To support agents to build with the latest Gemma advancements, we are releasing our official Skills Repository. This is a library of skills designed specifically to enable agents to build with Gemma models.
- Deploy your way: Spin up endpoints in production using Google Cloud. Deploy your way through Gemini Enterprise Agent Platform Model Garden, Cloud Run and GKE.