


安装 官方教程 进行即可,大致如下:
# Download the compose file to the current directory.
curl -LO https://github.com/knadh/listmonk/raw/master/docker-compose.yml

# Run the services in the background.
docker compose up -d
主程序 main.py
 	import feedparser
	import requests
	import json
	import os
	import logging
	from time import sleep
	from dateutil import parser
	from typing import List, Dict
	import re

	# 配置日志
	logging.basicConfig(
	    level=logging.DEBUG,
	    format='%(asctime)s - %(levelname)s - %(message)s',
	    handlers=[
	        logging.FileHandler('rss_checker.log'),
	        logging.StreamHandler()
	    ]
	)
	logger = logging.getLogger(__name__)

	RSS_URL = os.getenv('RSS_URL', "https://xxx.com/feed/")
	LISTMONK_API_URL = os.getenv('LISTMONK_API_URL', "https://listmonk.xxx.com/api/campaigns")
	LISTMONK_TOKEN = os.getenv('LISTMONK_TOKEN', "bot:xxx")
	LISTMONK_SEND_LIST_ID = int(os.getenv('LISTMONK_SEND_LIST_ID', 4))
	LISTMONK_SEND_LIST_IDS = [LISTMONK_SEND_LIST_ID]

	class RSSChecker:
	    def __init__(self):
	        self.rss_url = RSS_URL
	        self.listmonk_url = LISTMONK_API_URL
	        self.headers = {
	            "Content-Type": "application/json",
	            "Authorization": "token" + LISTMONK_TOKEN
	        }
	        self.max_retries = 3
	        self.retry_delay = 5  # seconds

	    def clean_html_content(self, html_content: str) -> str:
	        """清理HTML内容,移除以http://或https://开头的内容"""
	        try:
	            if not html_content:
	                return ""

	            # 移除以http://或https://开头的内容
	            cleaned_content = re.sub(r'https?://\S+', '', html_content)

	            # 清理多余的空白字符
	            cleaned_content = re.sub(r'\s+', ' ', cleaned_content).strip()

	            return cleaned_content

	        except Exception as e:
	            logger.error(f"清理HTML内容时出错: {str(e)}")
	            return html_content  # 如果处理失败,返回原始内容


	    def get_last_check_time(self) -> str:
	        try:
	            with open('last_check.txt', 'r') as f:
	                last_time = f.read().strip()
	                logger.debug(f"读取到上次检查时间: {last_time}")
	                return last_time
	        except:
	            logger.warning("未找到上次检查时间文件")
	            return ''

	    def save_check_time(self, time: str) -> None:
	        try:
	            with open('last_check.txt', 'w') as f:
	                f.write(time)
	            logger.debug(f"保存本次检查时间: {time}")
	        except Exception as e:
	            logger.error(f"保存检查时间时出错: {str(e)}")

	    def create_email_content(self, entries: List[Dict]) -> str:
	        """创建美化的HTML邮件内容"""
	        html_content = """
	        <style>
	            .header {
	                text-align: center;
	                margin-bottom: 40px;
	                padding: 20px;
	                background-color: #f8f9fa;
	                border-radius: 8px;
	            }
	            .main-title {
	                font-size: 28px;
	                color: #2c3e50;
	                margin-bottom: 10px;
	            }
	            .subtitle {
	                font-size: 20px;
	                color: #34495e;
	                margin-bottom: 15px;
	            }
	            .blog-name {
	                font-size: 24px;
	                color: #16a085;
	                margin-bottom: 10px;
	            }
	            .blog-description {
	                font-size: 16px;
	                color: #7f8c8d;
	                margin-bottom: 20px;
	            }
	            .article-container {
	                font-family: Arial, sans-serif;
	                max-width: 800px;
	                margin: 0 auto;
	                padding: 20px;
	            }
	            .article {
	                margin-bottom: 30px;
	                border-bottom: 1px solid #eee;
	                padding-bottom: 20px;
	            }
	            .article-title {
	                color: #333;
	                font-size: 24px;
	                margin-bottom: 10px;
	            }
	            .article-summary {
	                color: #666;
	                line-height: 1.6;
	                margin-bottom: 15px;
	            }
	            .read-more {
	                display: inline-block;
	                padding: 8px 15px;
	                background-color: #4CAF50;
	                color: white;
	                text-decoration: none;
	                border-radius: 4px;
	            }
	            .read-more:hover {
	                background-color: #45a049;
	            }
	        </style>
	        <div class="article-container">
	            <div class="header">
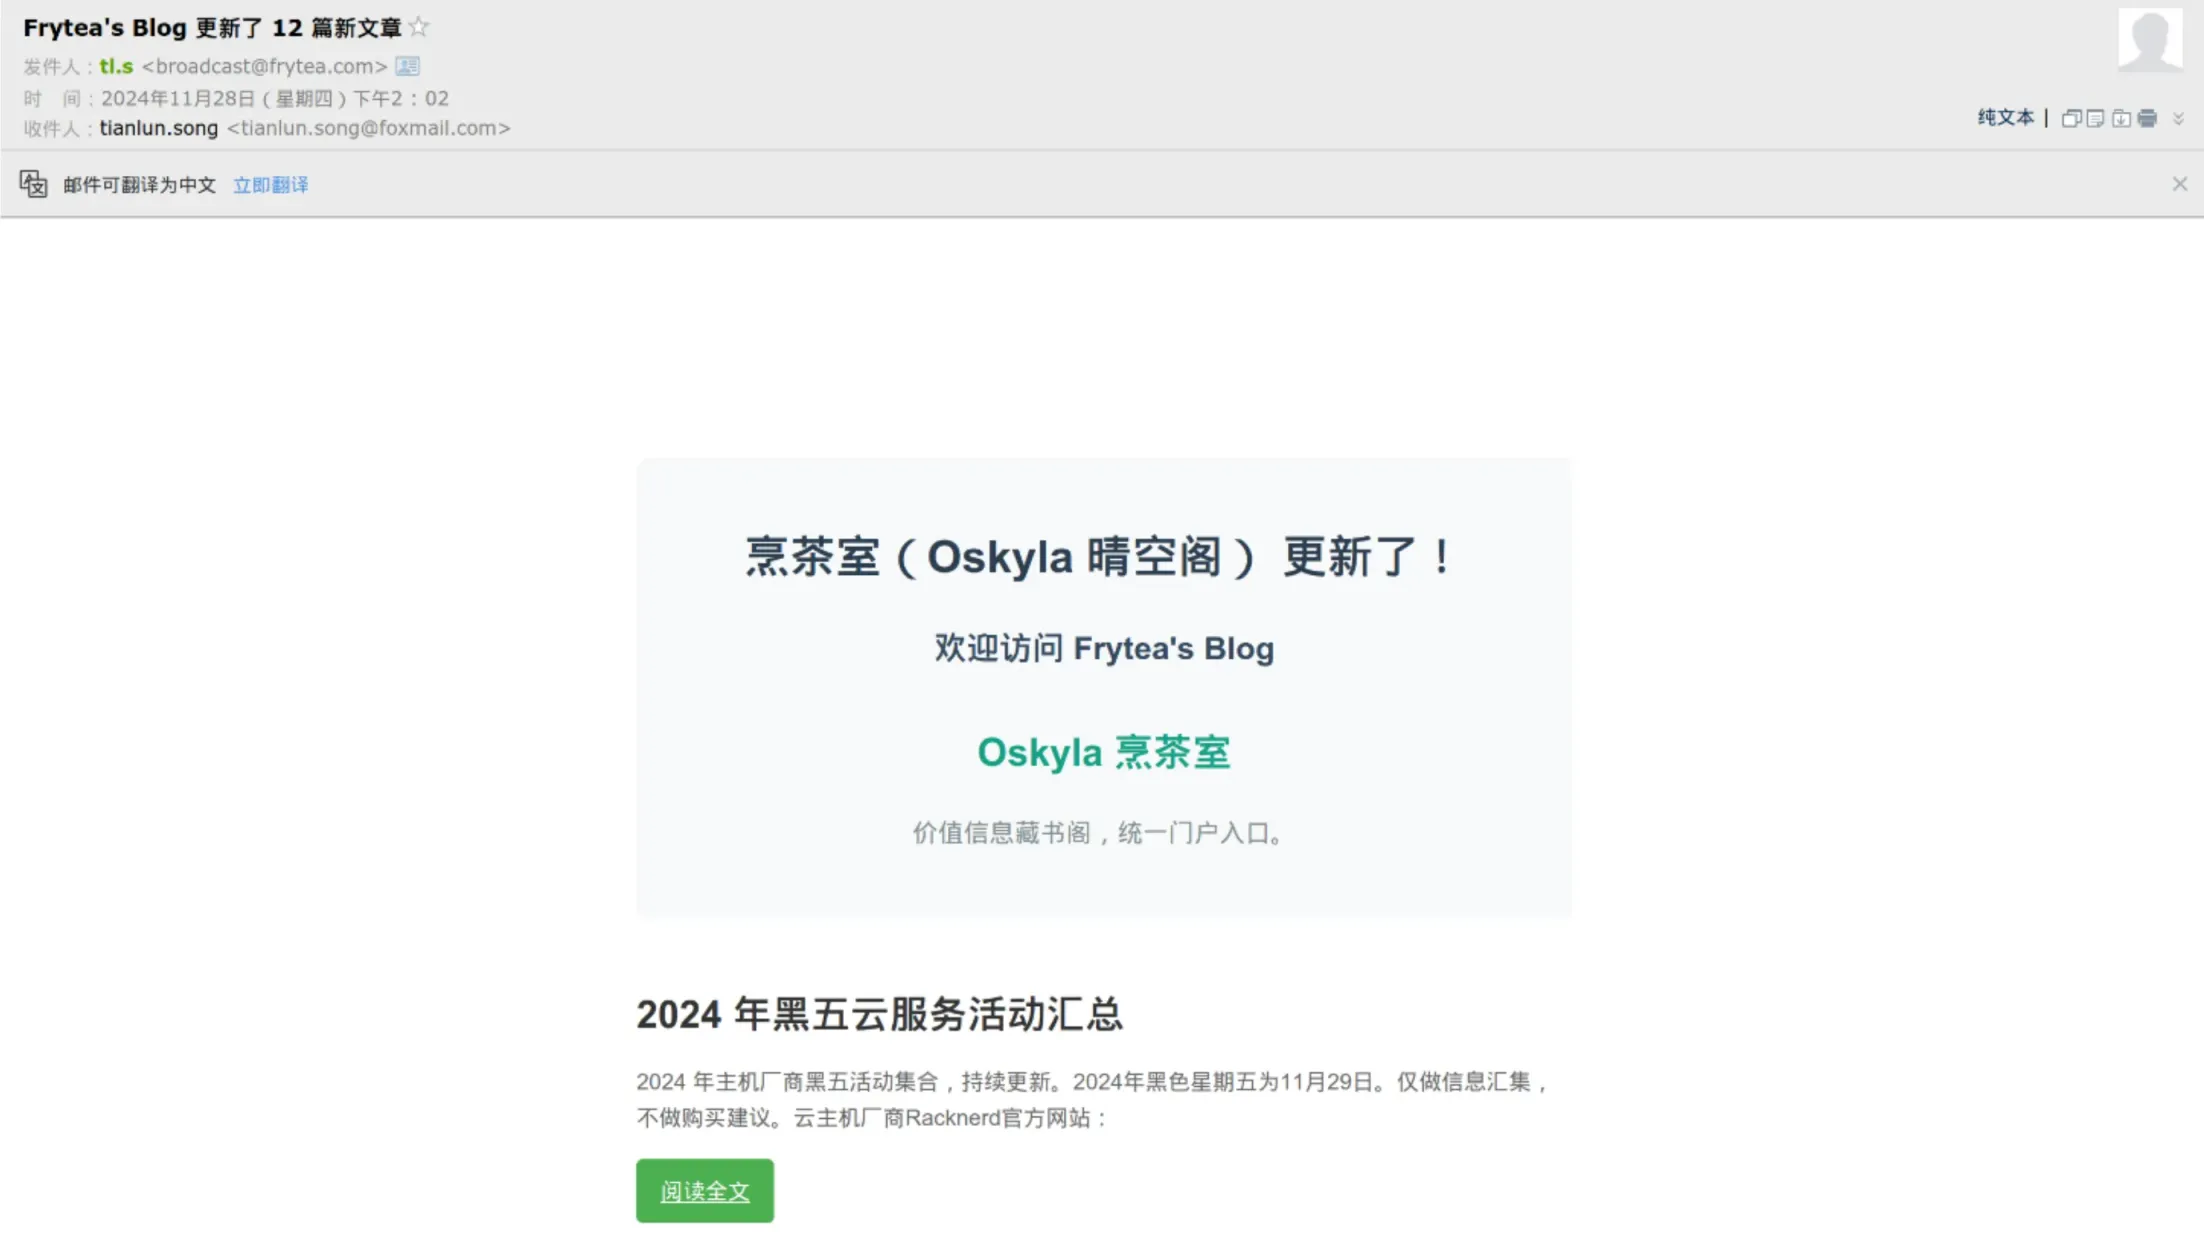
                <h1 class="main-title">烹茶室(Oskyla 晴空阁) 更新了!</h1>
	                <h2 class="subtitle">欢迎访问 Frytea's Blog</h2>
	                <h3 class="blog-name">Oskyla 烹茶室</h3>
	                <p class="blog-description">价值信息藏书阁,统一门户入口。</p>
	            </div>
	        """

	        for entry in entries:
	            # 清理文章标题和摘要中的HTML内容
	            clean_title = self.clean_html_content(entry.title)
	            clean_summary = self.clean_html_content(entry.summary)

	            html_content += f"""
	            <div class="article">
	                <h2 class="article-title">{clean_title}</h2>
	                <div class="article-summary">{clean_summary}</div>
	                <a href="{entry.link}" class="read-more">阅读全文</a>
	            </div>
	            """

	        html_content += "</div>"
	        return html_content


	    def publish_campaign(self, campaign_id: int) -> bool:
	        for attempt in range(self.max_retries):
	            try:
	                publish_url = f"{self.listmonk_url}/{campaign_id}/status"
	                response = requests.put(
	                    publish_url,
	                    headers=self.headers,
	                    json={"status": "running"}
	                )

	                if response.status_code == 200:
	                    logger.info(f"活动 {campaign_id} 发布成功")
	                    return True

	                logger.warning(f"发布尝试 {attempt + 1} 失败: HTTP {response.status_code}")
	                if attempt < self.max_retries - 1:
	                    sleep(self.retry_delay)

	            except requests.exceptions.RequestException as e:
	                logger.error(f"发布API请求异常: {str(e)}")
	                if attempt < self.max_retries - 1:
	                    sleep(self.retry_delay)

	        return False

	    def send_newsletter(self, new_entries: List[Dict]) -> bool:
	        try:
	            content = self.create_email_content(new_entries)
	            # 获取文章数量
	            article_count = len(new_entries)
	            # 清理标题中的HTML内容
	            #titles = ", ".join(self.clean_html_content(entry.title) for entry in new_entries)

	            data = {
	                "name": "Frytea's Blog 更新通知",
	                "subject": f"Frytea's Blog 更新了 {article_count} 篇新文章",
	                "lists": LISTMONK_SEND_LIST_IDS,
	                "content_type": "html",
	                "body": content,
	                "type": "regular"
	            }

	            logger.debug("准备发送的数据: %s", json.dumps(data, indent=2))

	            response = requests.post(self.listmonk_url, headers=self.headers, json=data)
	            if response.status_code == 200:
	                campaign_id = response.json().get('data', {}).get('id')
	                if campaign_id:
	                    return self.publish_campaign(campaign_id)

	            logger.error(f"创建活动失败: HTTP {response.status_code}")
	            return False

	        except Exception as e:
	            logger.error(f"发送邮件时出错: {str(e)}")
	            return False

	    def check_and_send(self) -> None:
	        try:
	            logger.info(f"开始解析RSS源: {self.rss_url}")
	            feed = feedparser.parse(self.rss_url)

	            if feed.bozo:
	                logger.error(f"RSS解析错误: {feed.bozo_exception}")
	                return

	            if not feed.entries:
	                logger.warning("RSS源没有任何条目")
	                return

	            last_check = self.get_last_check_time()
	            new_entries = []

	            #for entry in feed.entries:
	            #    if not last_check or entry.published > last_check:
	            #        new_entries.append(entry)

	            for entry in feed.entries:
	                # 将字符串解析为 datetime 对象
	                entry_time = parser.parse(entry.published)
	                last_check_time = parser.parse(last_check) if last_check else None

	                if not last_check_time or entry_time > last_check_time:
	                    new_entries.append(entry)

	            if new_entries:
	                logger.info(f"检测到 {len(new_entries)} 篇新文章")
	                if self.send_newsletter(new_entries):
	                    self.save_check_time(max(entry.published for entry in new_entries))
	            else:
	                logger.info("没有新文章")

	        except Exception as e:
	            logger.error(f"执行过程中出现未预期的错误: {str(e)}", exc_info=True)


	if __name__ == "__main__":
	    checker = RSSChecker()
	    checker.check_and_send()
依赖 requirements.txt
beautifulsoup4==4.12.3
feedparser==6.0.11
Requests==2.32.3
为方便使用的 Makefile
all: broadcast

broadcast: venv
    venv/bin/python3 main.py

venv:
    python3 -m venv venv
    venv/bin/pip3 install -r requirements.txt -i https://mirrors.tuna.tsinghua.edu.cn/pypi/web/simple
定时触发脚本,定时运行即可,修改为自己的内容。
export RSS_URL=https://xxx.com/feed/
export LISTMONK_API_URL=https://listmonk.xxx.com/api/campaigns
export LISTMONK_TOKEN=apiusername:api-token
export LISTMONK_SEND_LIST_ID=3

cd /mnt/data/script/listmonk_RSS_to_mail &&  make
欢迎订阅:https://frytea.com/subscribe.html
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。