


The maintenance burden for open-source developers extends beyond technical tasks like code reviews, bug fixing, and feature implementation. Especially for popular projects, much of the work comes down to triaging and responding to a deluge of issues, questions, and discussions.
Unfortunately, folks new to a project often open a new issue without first searching to see if a similar issue exists, increasing the workload of maintainers, who must find and link related issues when responding.
In this post, we’ll examine how CodiumAI's open-source PR-agent works, how it uses semantic search to automatically find and link issues related to new issues opened by community members, and how the Pinecone vector database and its metadata filtering feature powers this use case.
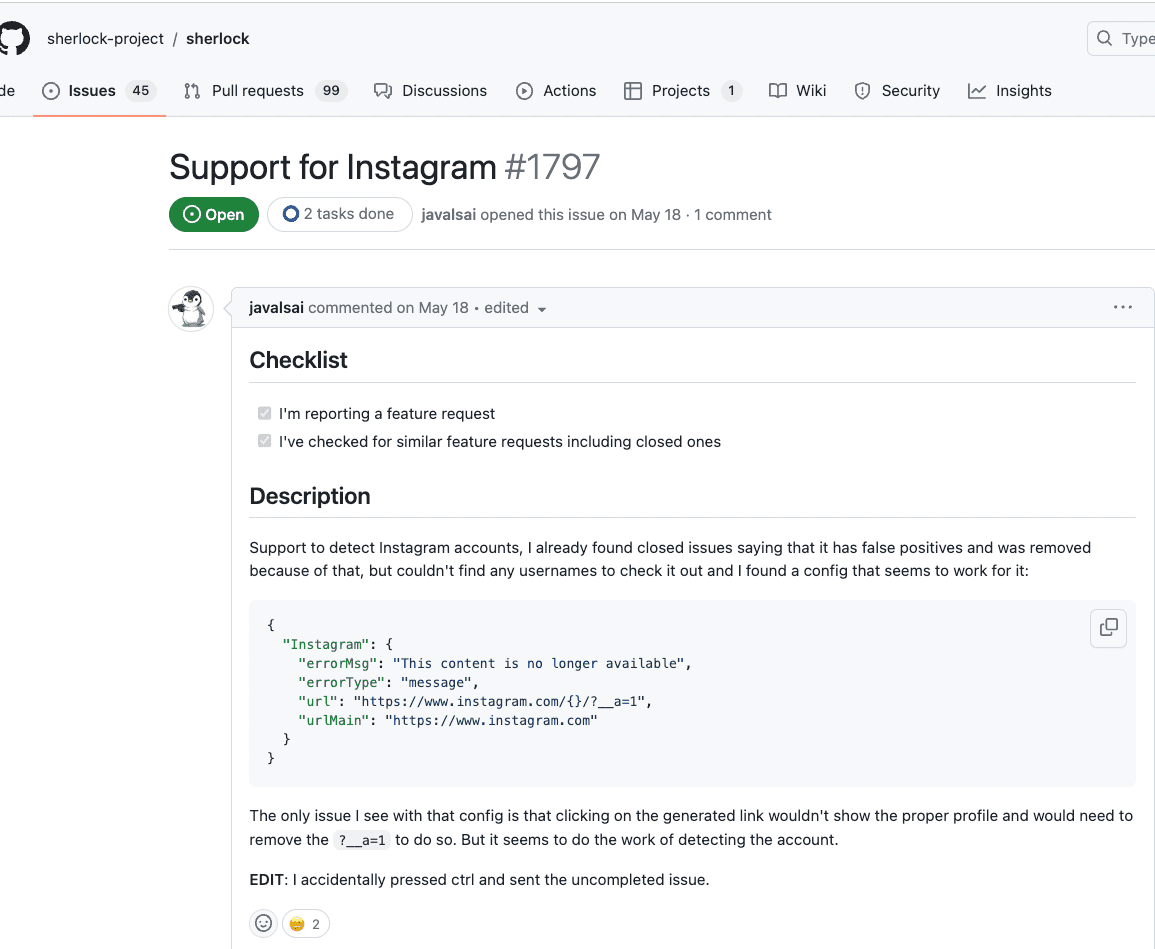
Let’s suppose an enthusiastic new community member visits your GitHub project and files this issue without first checking if there are any similar issues already open:
PR-agent will find similar issues that have already been opened, with a high degree of accuracy, and automatically comment, linking to the pre-existing issues:
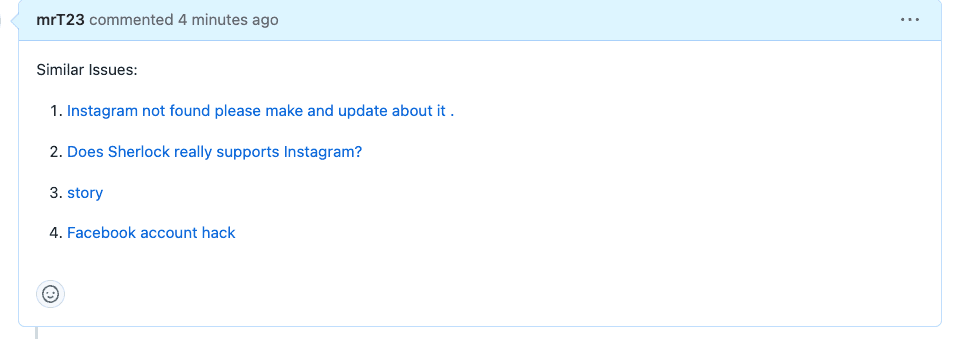
This automates away a great deal of open-source maintainer toil, allowing human developers to focus where they can have the most impact: creative problem-solving and improving software projects.
Every user visiting a GitHub project connected to PR-agent can issue a
command to pull back the list of issues about the same bug or feature request.
This functionality is more complex than it may initially seem: naive text-matching searches will not retrieve issues about the same topic or problem with a high enough degree of accuracy to be useful. Let’s look under the hood at how the solution works end to end.
The CodiumAI / Pinecone integration uses semantic search, which examines the intent behind the user’s words. We’ve written in-depth about semantic search here (and even more in-depth here). It converts the user’s ambiguous natural language query into vectors and then queries a vector database, such as Pinecone, to return matches closest to the user’s meaning.
Whereas naive keyword-matching search will get tripped up by the different contexts in which the word “bank” can be used, as in:
Semantic search will return the correct results based on the intent and context of the user’s query because it converts human language into vectors, which vector databases can use to determine semantic similarity.
CodiumAI’s engineering team built a custom solution that converts the initial GitHub issue into vectors that can be stored in Pinecone.
GitHub offers webhooks support, allowing notifications to be delivered to external web servers when certain events occur on GitHub. For example, you can configure a GitHub webhook that calls your server whenever a new issue is opened against one of your repositories.
This chart demonstrates the flow end to end:
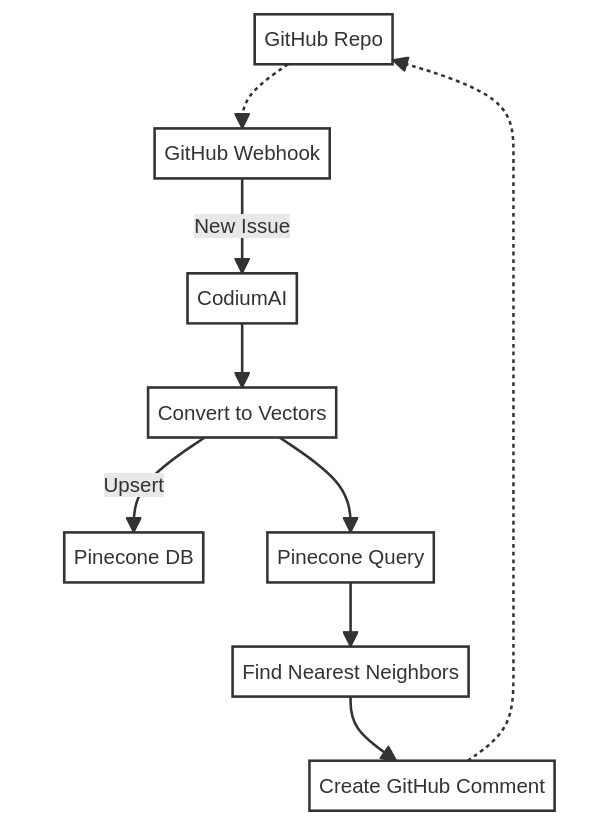
When a new issue is opened, Pinecone’s vector database can be queried to find the “nearest neighbors” to the new issue, meaning the issues most similar in their actual content and meaning.
CodiumAI’s solution uses OpenAI’s text-embedding-ada-02 embedding model to convert the GitHub issue title and body into vectors. In the initial stages of building out this solution, the CodiumAI team considered flattening and vectorizing subsequent follow-up comments on GitHub issues but ultimately found the best accuracy was achieved by converting the GitHub issue title and body to vectors and then querying Pinecone for nearest neighbors to retrieve issues discussing the same problem or feature.
Helping out open-source maintainers is essential. But CodiumAI has broader ambitions to reduce developer toil across the entire development lifecycle by auto-generating tests for your codebase, catching security issues within your IDE before insecure code is committed, generating pull request descriptions, and more. If you’re a developer who wishes they had some more free time, CodiumAI’s solutions are worth a look.
The CodiumAI team shared that they were able to go from idea to working implementation in about 4 days using Pinecone’s API. They especially found Pinecone’s filtering feature useful because it allowed them to manage and address multiple repositories via metadata.
CodiumAI’s similar issue solution allows each GitHub user to supply their own Pinecone API key when installing the application for even more privacy and control over their data.
Even though GitHub issues are completely public, meaning that even folks not signed into GitHub can find them in search engines and read them, the CodiumAI team takes security seriously, which was part of why they chose Pinecone as their vector database.
Pinecone is a cloud-native and fully managed solution designed for extreme scale and security. When you use Pinecone, you provision indexes, upsert vectors, and make queries via API calls, and all of your vectors are encrypted in flight and at rest. Pinecone never looks at embeddings and only stores data necessary to service your API requests.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。