Industrial environments are entering the era of Physical AI. Driven by machine vision, autonomous vehicles, and Software-Defined Automation, this new intelligence sits on top of thousands of already-networked PLCs, HMIs, safety controllers, and motor drives. Because every piece of the factory floor is now hyper-connected, maximizing network uptime is no longer optional—it is a critical business mandate.
While network anomalies are unavoidable, effective troubleshooting is essential to minimizing mean time to detection (MTTD) and resolution (MTTR).
The industrial network troubleshooting gap
- Current approaches are slow for the factory floor. When an issue disrupts production, every minute counts. But today’s troubleshooting is largely reactive – problems surface when a line stops or a device goes unreachable, and then the investigation begins. Correlating issues to root cause is manual, spread across multiple tools, and depends on whoever happens to be available. In an environment where downtime is measured in tens of thousands of dollars per minute, that process doesn’t move fast enough.
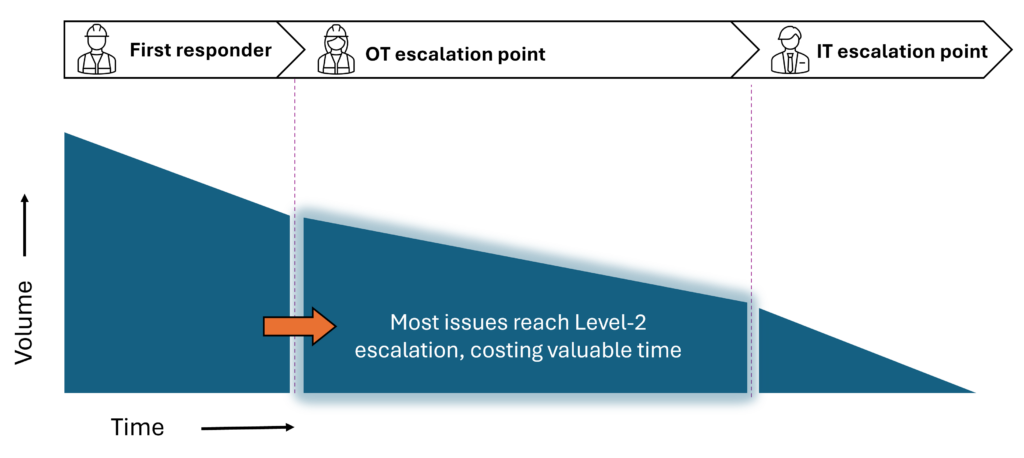
- Too many escalations for too few experts. The first responder – the maintenance technician on the floor — knows the physical systems but struggles to diagnose when an issue is network-related. IT tools lack enough OT context to help, and OT technicians lack networking expertise to use these tools. Even straightforward problems – for example, an OT endpoint that was accidentally moved to a different port causing it to go offline – get escalated because the first responder is unable to determine the root cause. The OT escalation point – the network expert team that absorb these escalations is small and stretched across sites.
The result: hours of production downtime while experts catch up. For physical-layer issues – a damaged cable, a failing fiber optic transceiver – the fix is often simple enough for the technician on the floor to act on directly, if they can get to root cause. For network operations issues, it still needs the network experts – but the gap is the same: getting from issue to root cause fast enough to keep the line moving.
A digital teammate for your OT team
As part of Cisco AgenticOps and available through Cisco Cloud Control, AI Troubleshooting for Industrial Networks is an always-on ambient agent in the factory floor that acts as a digital teammate for your OT team – giving technicians a path from symptoms to root cause, and giving network engineers a headstart when they need to step in.
The on-premises, ambient agent senses the environment 24×7, detects alerts and patterns, diagnoses the signals, and prepares recommended actions before a maintenance technician has to ask. It detects issues by monitoring switch system messages and clustering related events in a time window — rather than treating every alert as a separate incident. It diagnoses root causes using deterministic logic built on Cisco’s industrial networking expertise. By gathering and reasoning over evidence from the network’s topology, state and configuration, the agent quickly identifies the most likely cause. And then it recommends clear, sequenced next steps – whether that’s a physical fix the OT technician can follow or a precise escalation for a network configuration issue the network expert can act on immediately.
An example: A machine in the packing area suddenly halts. The agent detects a problem with the fiber connection from the access switch, gathers interface and SFP state, and determines that the SFP on port 1/1 is experiencing signal degradation, likely due to environmental dust blocking the signal. The alert tells the OT technician exactly which switch and port are affected and provides a clear physical fix: clean and reseat the SFP module. Without the agent, this same issue would have been reported as “comms fault” by the OT technician, escalated to the network expert team, and diagnosed hours later.
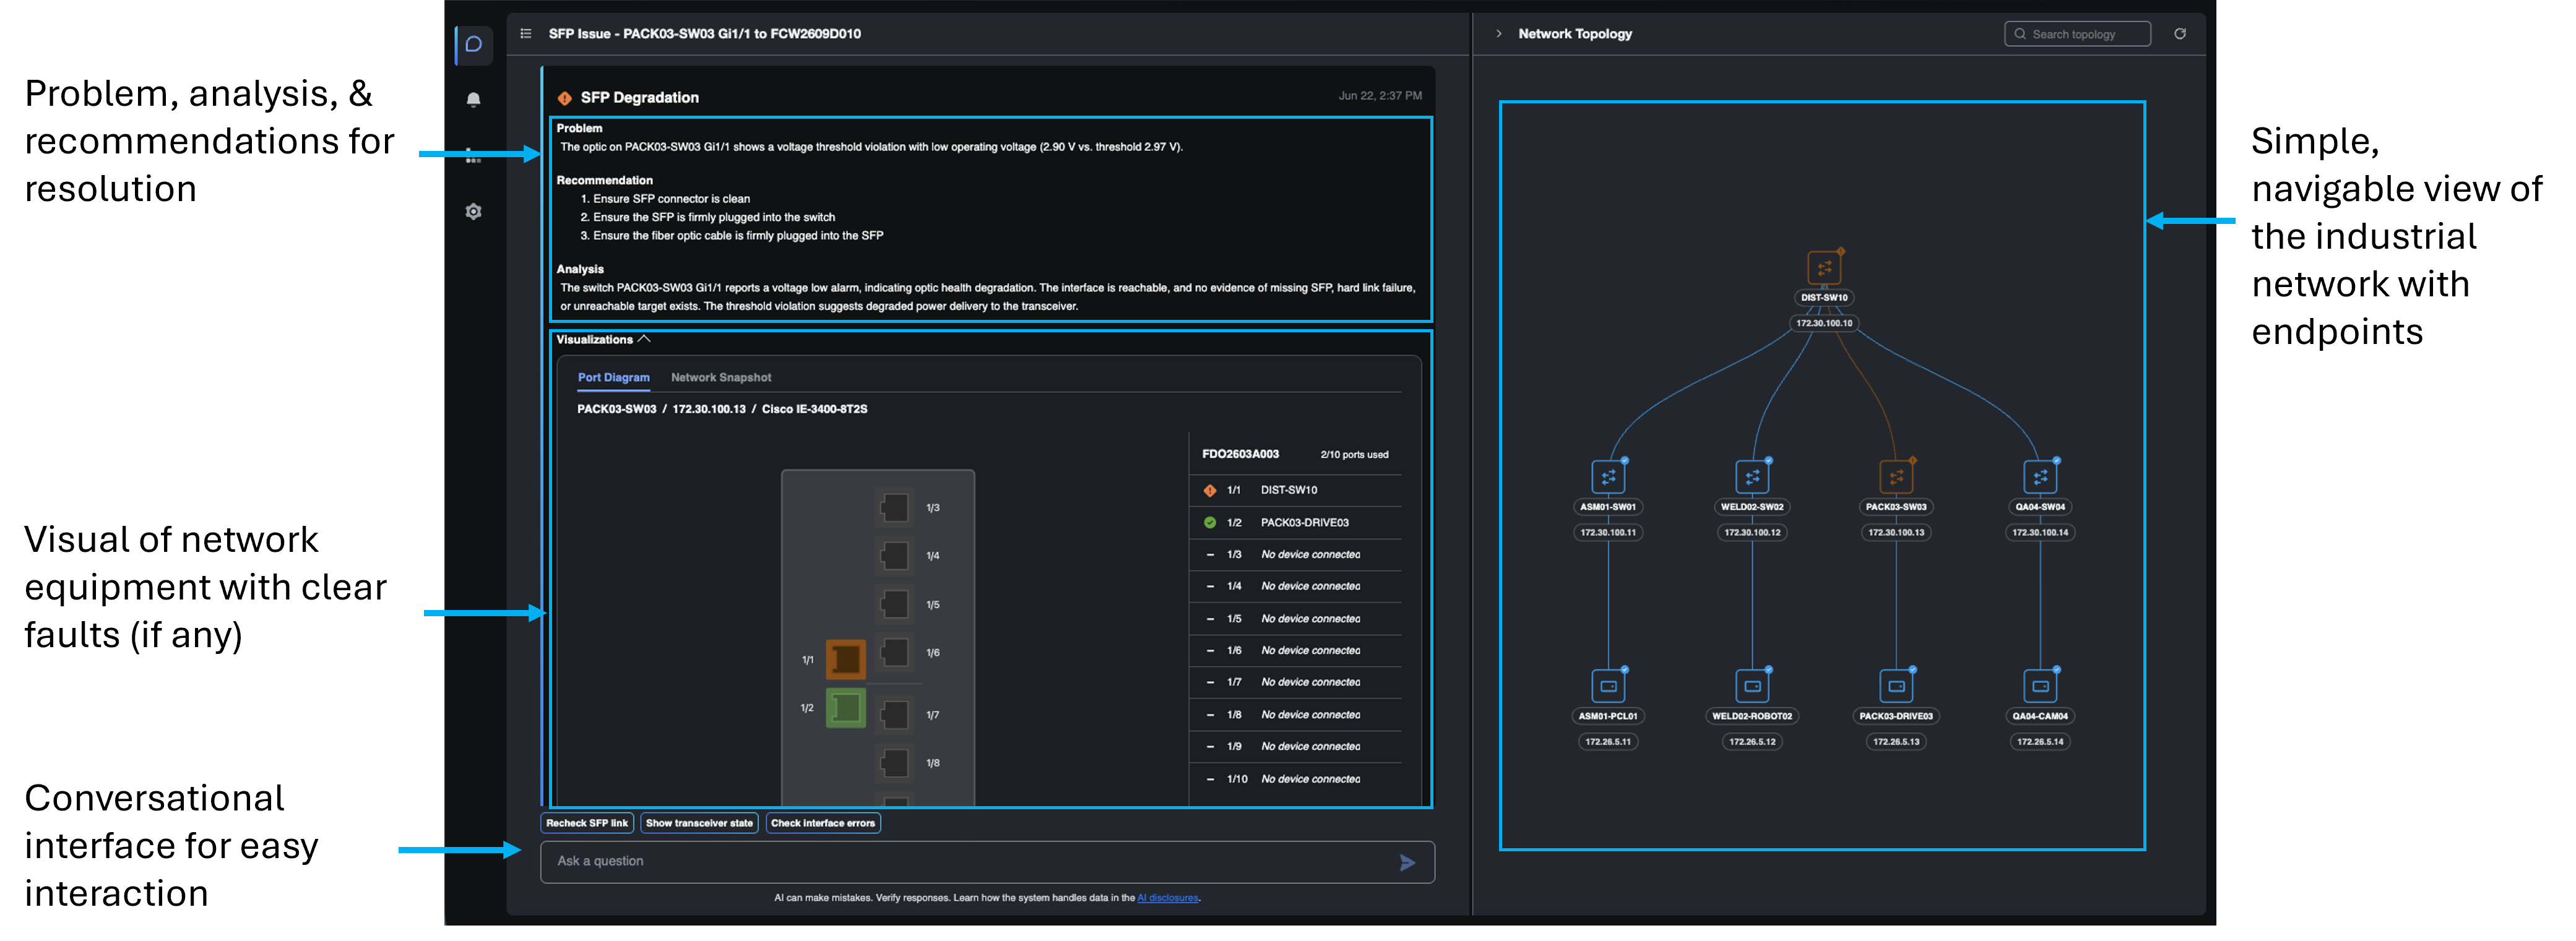
The agent handles the most common issues experienced on the factory floor – spanning physical faults and operational disruptions – through the evidence-driven diagnostic logic:
- Cable and fiber optic faults: Detects link instability and determines whether the cause is physical such as a damaged cable or fiber optic module. For suspected cable damage, it can run a cable diagnostic test (with technician consent) to pinpoint the fault distance from the switch.
- Endpoint device offline: Investigates non-physical reasons why an endpoint stopped communicating such as duplex mismatch, endpoint moved to a different switch port with VLAN mismatch or duplicate IP due to L2NAT misconfiguration.
- Power over Ethernet (PoE) failures: Checks power delivery status, available budget, recent power events, and enforcement status to determine whether the cause is a port-level policy fault or insufficient switch power budget.
- Switch power supply failures: Monitors for power supply failure, input power quality, surfaces the loss of a redundant power supply.
- Switch stability issues: Monitors high memory or CPU utilization, warns a process is consuming up CPU cycles, enabling technicians to escalate with diagnostic data.
Everyday operational questions
Beyond proactive alerting, the agent helps OT teams answer common questions without needing to log into a switch and run CLI commands. OT teams can select a switch and start a conversation with it to get live operational and configuration data. The agent also suggests the most relevant prompts based on the device and context. Network experts can tag devices with familiar names, locations, and production areas (e.g., “Line 1 welder”), so OT teams can query switches using OT language instead of IP addresses or hostnames.
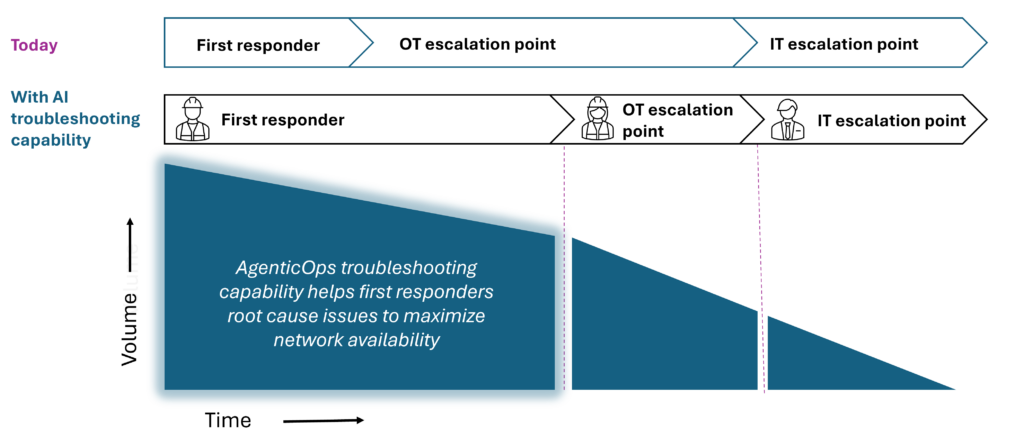
As one customer OT network expert from an early alpha trial put it: “This will help me sleep better at night — it’ll reduce escalations during testing and bring up.” AI Troubleshooting for Industrial Networks is designed to close the gap between symptoms and root causes on the factory floor — reducing escalations, compressing resolution times, and keeping production moving.
The promise of Physical AI relies entirely on maximizing network uptime. AI Troubleshooting for Industrial Networks empowers your OT teams to slash downtime and secure the foundation for this new era.
If you are interested in shaping the next phase of the agent and gaining access, join the beta program today.
Learn more
Authors